Artificial Intelligence

Sean Cai on the State of AI Data Markets

Sean Cai dissects the AI data market, highlighting fragmentation, the importance of 'type one' data, and the pitfalls of current benchmarks.

Daniel Singer

By Daniel Singer, Editor, StartupHub.ai

4 min read

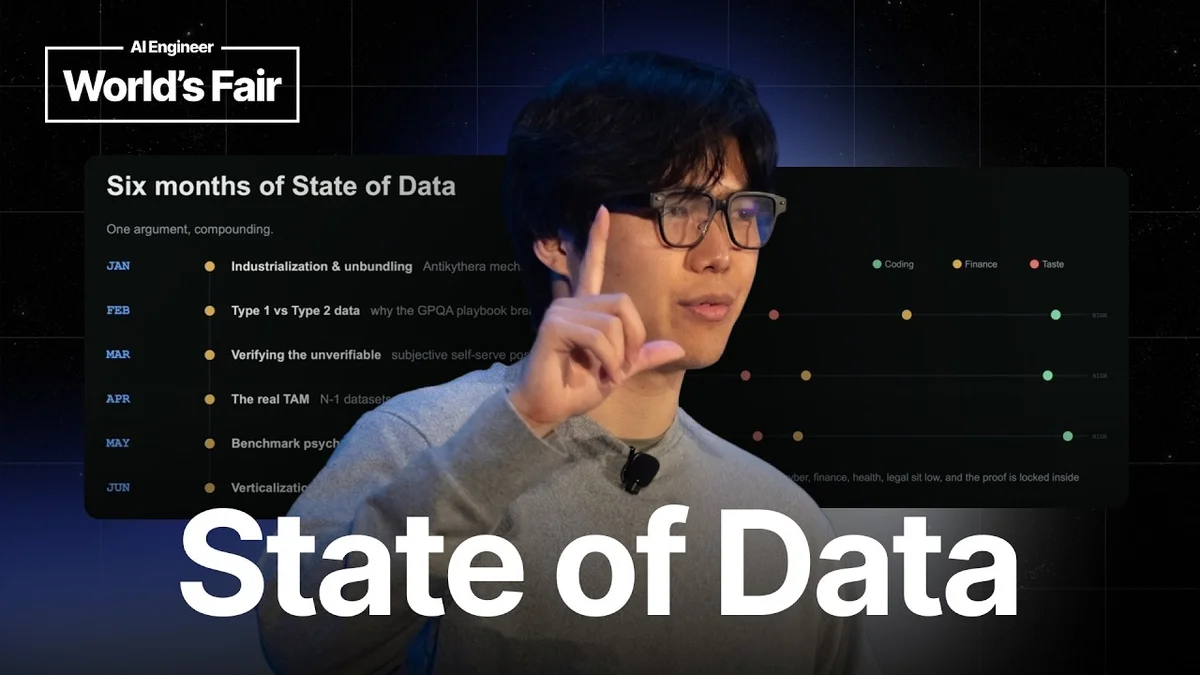
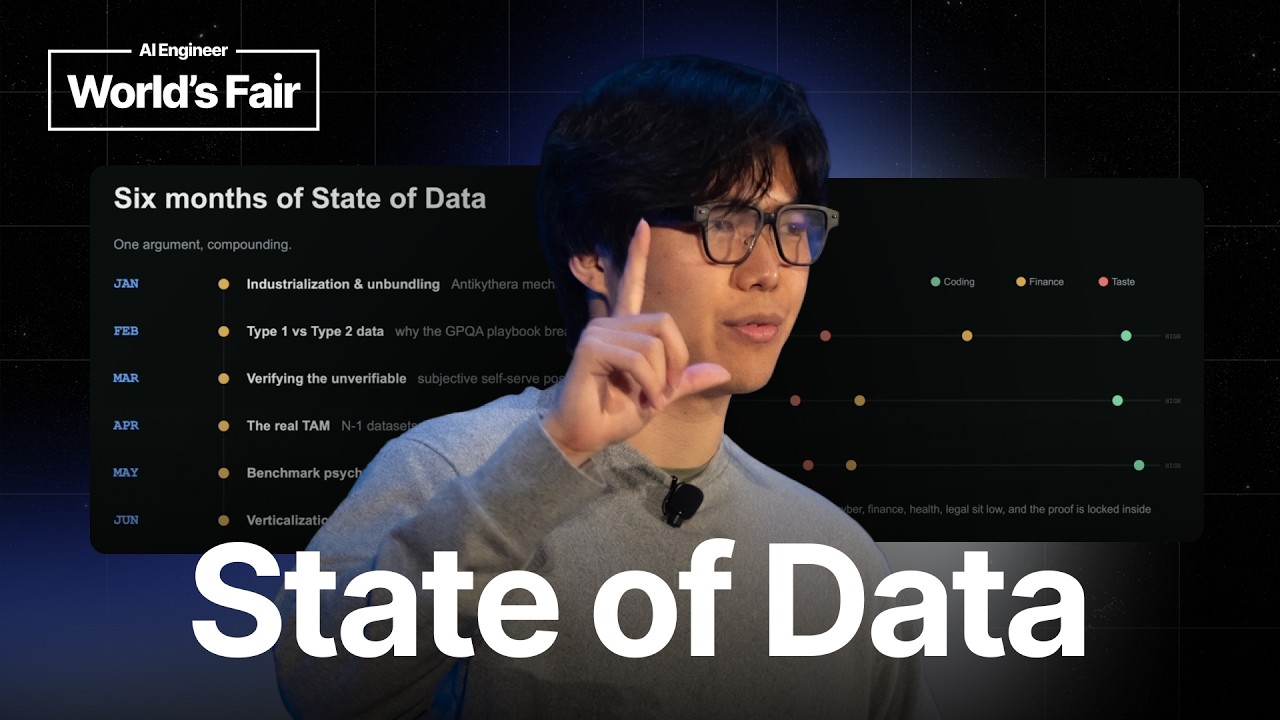
Sean Cai presenting on the State of Data at AI Engineer World's Fair
Credit: AI Engineer
Visual TL;DR
AI Data MarketContext
From the article 9+ mentionsSean Cai, an independent researcher and speaker, delivered a compelling talk on the "State of Data" at the AI Engineer World's Fair, offering a critical look at the AI data market.
Beyond Basic LabelingDriver
From the articleCai argued that the focus on basic data labeling is the "least interesting part" of AI development, with the real value lying in data that transitions models from generalist competence to true expertise.
Market FragmentationDriver
shift from vertically integrated giants to a fragmented landscape of specialist providers
From the article 3 mentionsThis fragmentation, he believes, is permanent, not transitional.
Type One DataCore
pure capture of real workflows like GitHub commits, crucial for true expertise
From the article 6 mentionsA key point of his presentation was the concept of "type one" versus "type two" data.
Specialists OutcompeteEffect
From the article 2 mentionsHe noted that "specialists outcompete the giants at a lot of steps," including sourcing talent, building environments, designing rewards, and running evaluations.
True ExpertiseOutcome
From the article 2 mentionsCai argued that the focus on basic data labeling is the "least interesting part" of AI development, with the real value lying in data that transitions models from generalist competence to true expertise.
Verifiability BottleneckDriver
current benchmarks are problematic, hindering reliable data quality assessment
From the articleHe broke down verifiability into three axes: asymmetry (decomposing a task into checkable steps), veracity (consensus on what constitutes correctness), and proliferation (frequency of real-world examples).
Future: Custom DataOutcome
future of data lies in enterprise and highly customized, specialized datasets
Contents(3)

Sean Cai, an independent researcher and speaker, delivered a compelling talk on the "State of Data" at the AI Engineer World's Fair, offering a critical look at the AI data market. Cai argued that the focus on basic data labeling is the "least interesting part" of AI development, with the real value lying in data that transitions models from generalist competence to true expertise.

Sean Cai on the State of AI Data Markets - AI Engineer
Sean Cai on the State of AI Data Markets, AI Engineer

The Evolving Data Market: Fragmentation and Quality

Cai highlighted a significant shift in the data market, moving away from the vertically integrated giants of the past towards a more fragmented landscape of specialists. He noted that "specialists outcompete the giants at a lot of steps," including sourcing talent, building environments, designing rewards, and running evaluations. This fragmentation, he believes, is permanent, not transitional.

A key point of his presentation was the concept of "type one" versus "type two" data. Type one data is a pure capture of real workflows, such as GitHub commits or session replays, with minimal reward shaping. Type two data, conversely, involves hiring experts to create contrived examples in arbitrary settings. Cai emphasized that while type two data is useful for initial model training, type one data is crucial for achieving higher levels of performance and expertise, as its realism is inherited from the work itself.

A stark warning was issued regarding the industry's practices: "The dirty secret of the industry though is that everybody sells type two and bills it as type one." This practice, he explained, leads to a situation where quality does not scale linearly with quantity, prompting many labs to diversify their vendor base to mitigate risks.

Verifiability as a Bottleneck and the Problem with Benchmarks

Cai introduced "Verifier's Law," a concept posited by researcher Jason Wei, stating that the ease of training a model is proportional to how verifiable the task is. He broke down verifiability into three axes: asymmetry (decomposing a task into checkable steps), veracity (consensus on what constitutes correctness), and proliferation (frequency of real-world examples). He used coding as an example, citing GitHub's unit tests and commit messages as solving all three axes simultaneously, which contributed to AI's early success in this domain.

The daily brief

Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.

Join 64,000 other subscribers.

Conversely, domains like biology, security, finance, healthcare, and law score lower on these axes, making data acquisition and verification more challenging. Cai also critiqued the prevalent use of "contrived benchmarks," which he described as a "recipe" for creating fake evaluations. This involves hiring experts to generate tasks, solve them with AI, cherry-pick failures, and then sell the data to "hill climb" that same benchmark. He called this "Goodhart's Law with a profit motive," where the measure becomes the target itself, leading to a "fog of war" where no one truly knows which data genuinely improves models.

The Future of Data: Enterprise and Customization

Cai predicted that the next wave of AI application maturity would move into these more complex, less verifiable domains. He also discussed the evolving role of models, noting that as open-source models improve (like GLM 5.2 surpassing GPT in some rubrics), application layer companies can decouple from foundation model labs. This decoupling, he argued, prevents durable lock-in and shifts the focus to efficiency and modality differences.

The most significant trend, however, is the pivot of successful data companies towards enterprise solutions. Cai stated, "Data businesses do not stay data businesses because the durable value accrues to the services and app layer of actual work." This means building specialized infrastructure, including "Antikythera mechanisms" to translate messy business contexts into actionable data, managing RL data sets across base model migrations, and serving route small models efficiently. He concluded with two key takeaways for the AI community: researchers should avoid outsourcing their definition of realism to vendors, and builders should focus on pipelines into real-world work, coupled with the infrastructure for continuous retraining.

Mentioned in this story

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

TopicsSean CaiAI Engineer World's FairData MarketsArtificial IntelligenceMachine LearningData QualityAI benchmarksEnterprise AI

Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute, free.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

