#AI benchmarks
23 articles with this tag
Most read in #AI benchmarks, last 30 days
Vals: The AI Scorekeeper We Need
Vals is building the essential trust layer for AI, evaluating models on real-world tasks, not just academic benchmarks.
David Brumley on Teaching AI to Find Real Zero Day Vulnerabilities
David Brumley details how reinforcement learning sandboxes and deterministic graders allow AI models to reliably discover real software vulnerabilities.

OpenAI Triples Benchmark Scores With Simple Settings
OpenAI found simple API setting tweaks tripled scores on the ARC-AGI-3 benchmark, proving harness design significantly impacts AI evaluation.
Sean Cai on the State of AI Data Markets
Sean Cai dissects the AI data market, highlighting fragmentation, the importance of 'type one' data, and the pitfalls of current benchmarks.
Benchmarks Fail Modern AI, Says OpenAI Scientist
OpenAI's Noam Brown discusses why traditional benchmarks fail modern AI, emphasizing the need for new evaluation methods that account for computational budgets and model capabilities.
OpenAI Unveils LifeSciBench
OpenAI's LifeSciBench is a new benchmark designed to test AI's real-world applicability in complex life science research, moving beyond basic question answering.
Task Fidelity Scaling Laws: Kobie Crawford on AI Data Quality
Kobie Crawford of Snorkel discusses 'Task Fidelity Scaling Laws,' emphasizing how data quality impacts AI model performance and outlining Snorkel's approach to creating verifiable datasets.
Google Gemma 4 Review: How a 31B Open Model Beats 400B Rivals
Google Gemma 4 review: benchmarks, features, and how the 31B model outperforms Llama 4 and Qwen 3.5 on math, coding, and agentic tasks under Apache 2.0.
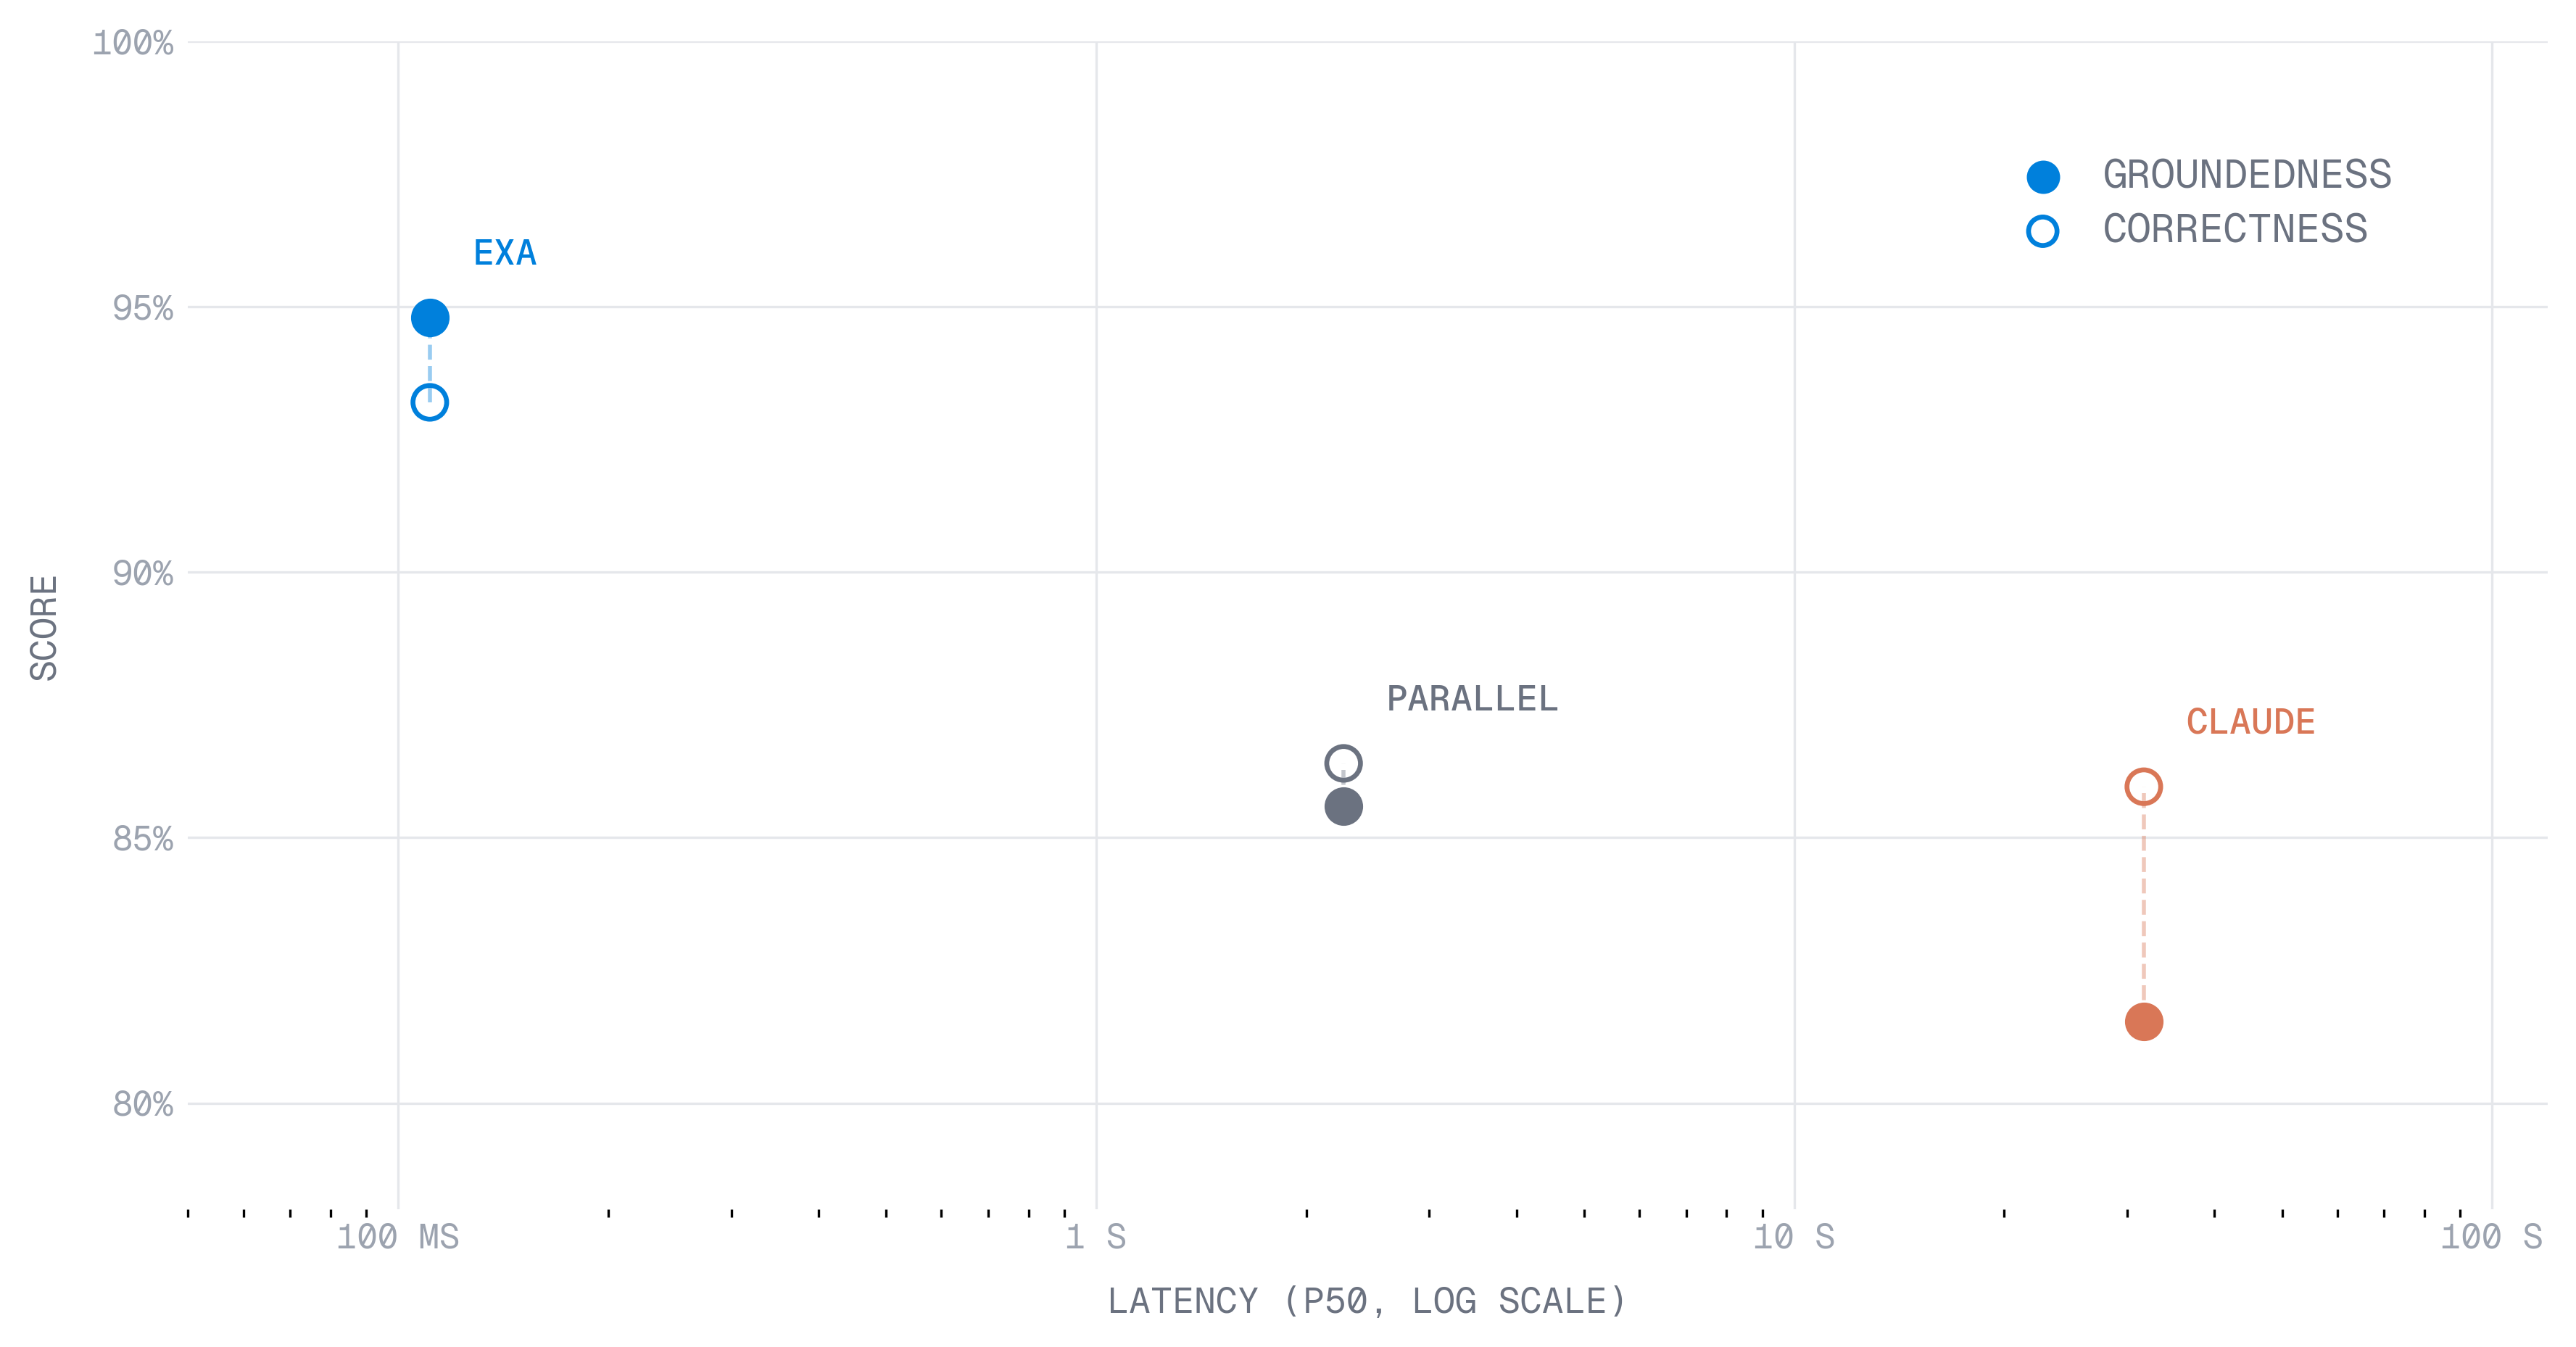
Exa Unveils New Code Search Benchmarks
Exa.ai releases 'WebCode', a new benchmark suite for evaluating search performance in coding agents, addressing limitations in existing tools.
Poetiq's Small Team Sets New Together AI Benchmark Records
Poetiq's small team is setting new Together AI benchmark records by leveraging recursively self-improving meta-systems to optimize existing LLMs.
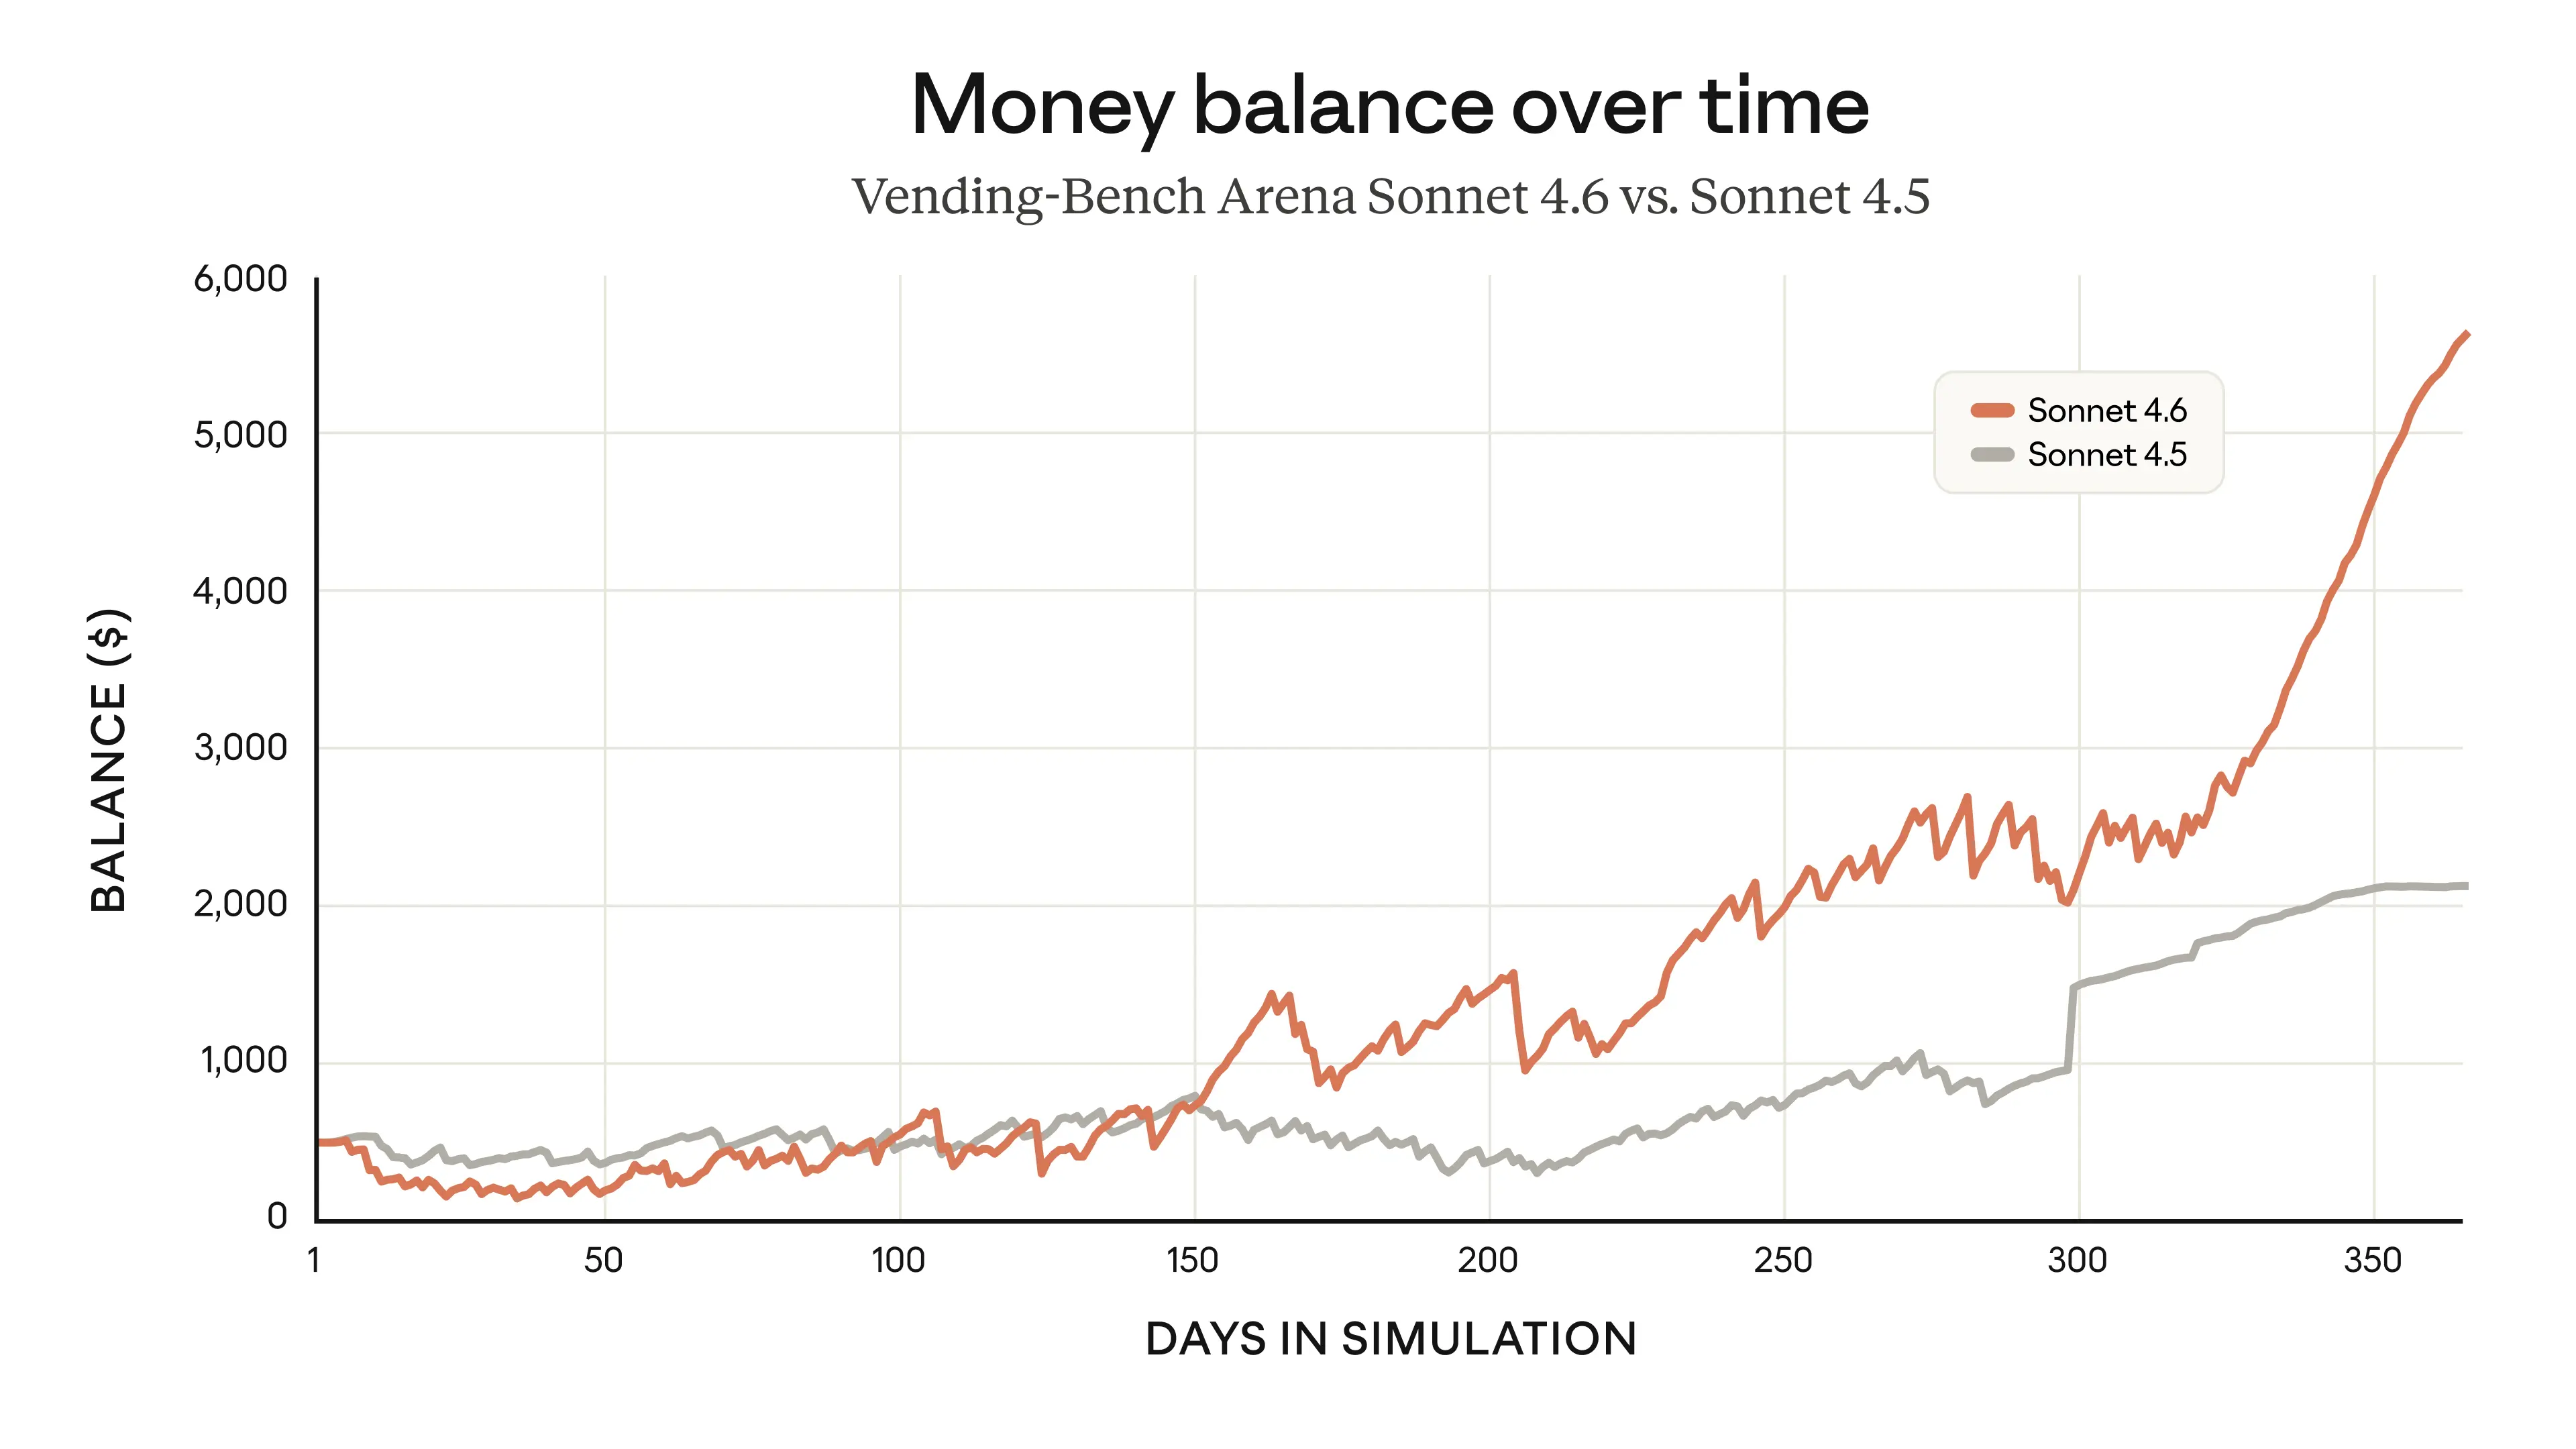
Claude Sonnet 4.6 Ups the AI Ante
Anthropic's Claude Sonnet 4.6 launches with major upgrades in coding, reasoning, and computer use, plus a 1M token context window.
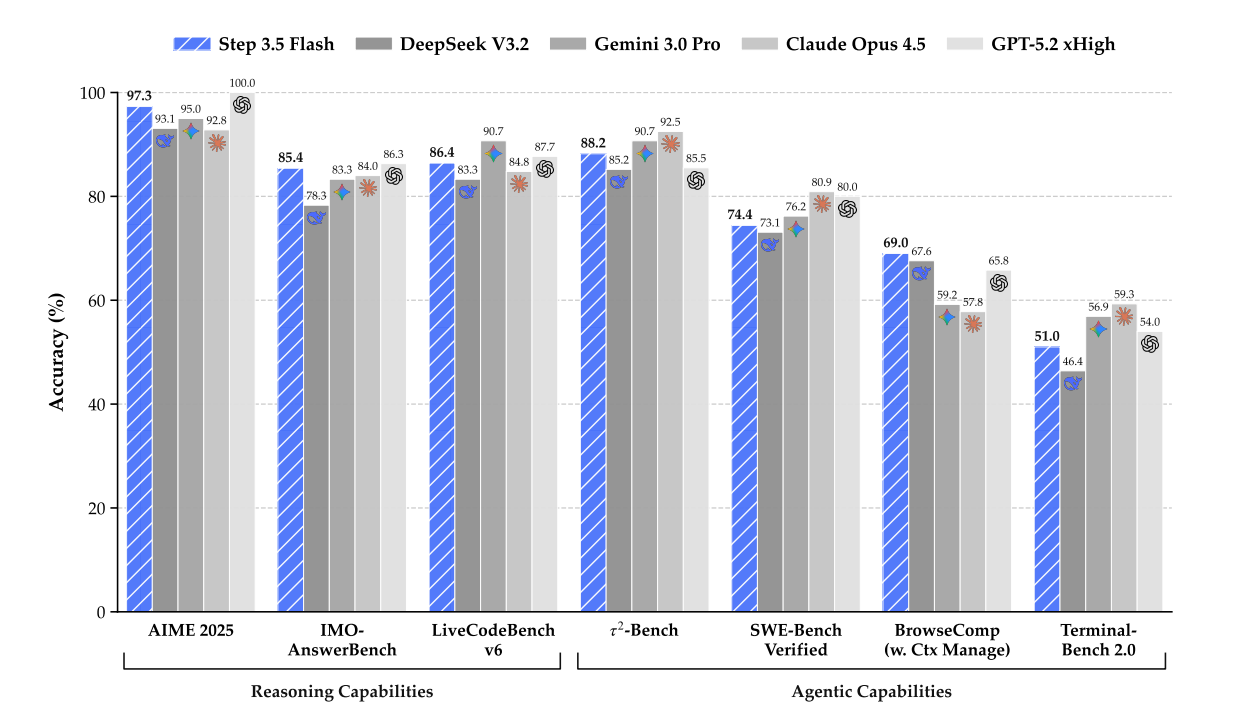
Step 3.5 Flash: AI's New Efficiency Standard
Step 3.5 Flash AI model revolutionizes AI efficiency with a 196B parameter foundation and 11B active parameters, offering competitive performance with lower latency.

Claude Opus 4.6: Smarter, Faster, and Longer Context
Anthropic's Claude Opus 4.6 launches with a 1M token context window, enhanced coding, and state-of-the-art benchmark performance.
Unifying AI Benchmarks: A New Lens on Model Capabilities and Progress
Anthropic's Opus 4.5: Redefining AI Capabilities and Efficiency
GLM 4.6 Challenges Frontier Models with Open-Source Prowess
The open-source model GLM 4.6 has achieved a remarkable feat, standing shoulder-to-shoulder with proprietary giants like GPT-4o and Claude 3.
GLM 4.6 Challenges Frontier Models with Open-Source Prowess
The open-source model GLM 4.6 has achieved a remarkable feat, standing shoulder-to-shoulder with proprietary giants like GPT-4o and Claude 3.
Beyond Benchmarks: AI's Shift to Orchestrated Intelligence
Google's Gemini 3 Dominance Reshapes AI Landscape
Terminal-Bench 2.0 and Harbor Reset the Bar for AI Agent Evaluation
The recent launch party for Terminal-Bench 2.0 and Harbor, hosted by Mike Merrill and Alex Shaw, unveiled a pivotal shift in how AI agents are evaluated, moving...
Terminal-Bench 2.0 and Harbor Reset the Bar for AI Agent Evaluation
The recent launch party for Terminal-Bench 2.0 and Harbor, hosted by Mike Merrill and Alex Shaw, unveiled a pivotal shift in how AI agents are evaluated, moving...
Google Cloud Simplifies AI Inference with GKE Quickstart