Task Fidelity Scaling Laws: Kobie Crawford on AI Data Quality

Kobie Crawford of Snorkel discusses 'Task Fidelity Scaling Laws,' emphasizing how data quality impacts AI model performance and outlining Snorkel's approach to creating verifiable datasets.

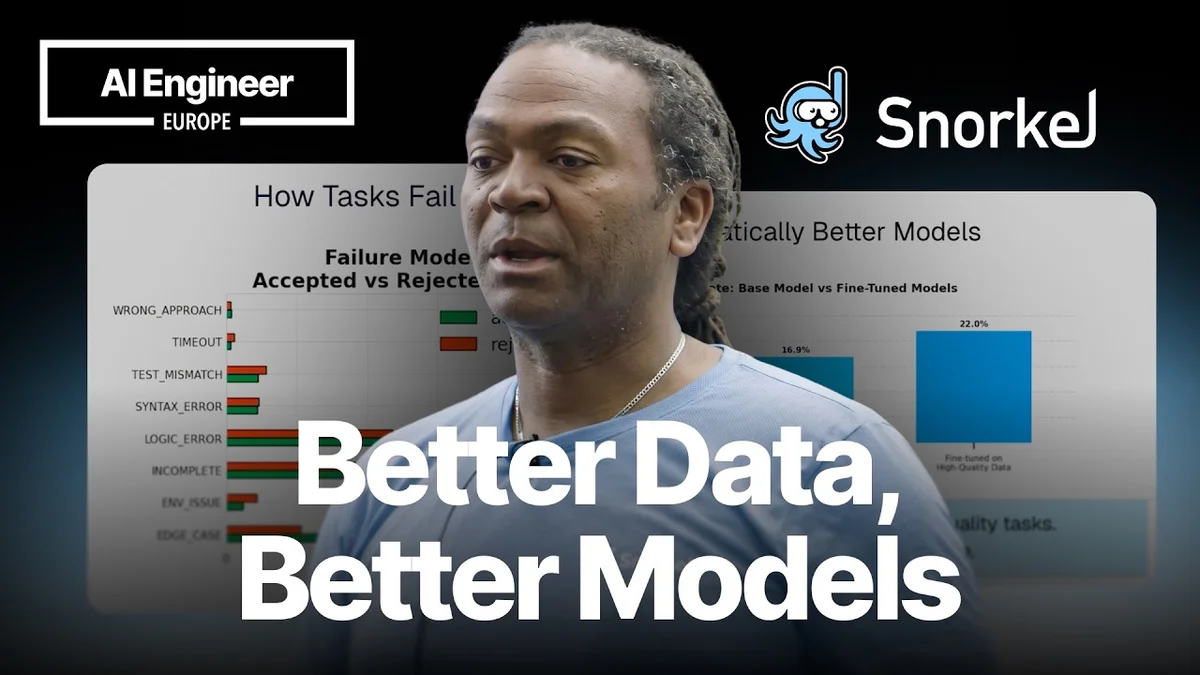
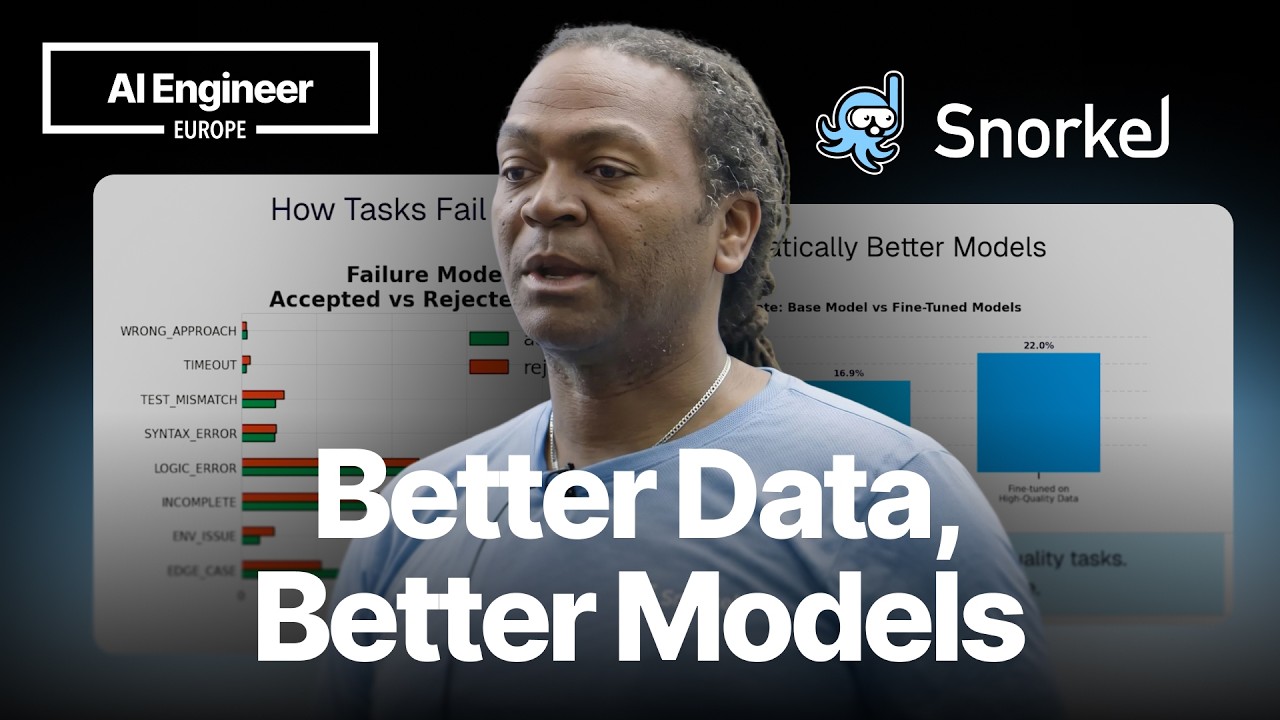
Kobie Crawford presenting on Task Fidelity Scaling Laws at AI Engineer Europe
Kobie Crawford, Developer Advocate at Snorkel, presenting on Task Fidelity Scaling Laws.· AI Engineer
Visual TL;DR
Task Quality MattersDriver
From the article 6 mentionsCrawford began by posing the central question: "Does Task Quality Actually Matter?" She asserted that AI model capabilities are fundamentally bounded by the quality of the training data.
Snorkel ApproachCore
Library for generating verifiable training data for foundation models
From the article 9+ mentionsRejected tasks, however, showed a higher proportion of 'Wrong Approach' and 'Syntax Error' failures, indicating issues with the task definition or the model's fundamental understanding of the problem.
Task Fidelity Scaling LawsContext
From the articleIn a presentation at AI Engineer Europe, Kobie Crawford, Developer Advocate at Snorkel, explored the critical role of "Task Fidelity Scaling Laws" in advancing AI model development.
High-Quality TasksEffect
Impacts model performance positively, regardless of architecture
From the article 9+ mentionsThe core finding presented was that high-quality tasks lead to dramatically better models.
Define & Evaluate QualityContext
Understanding and measuring the quality of training tasks
Analyze Failure ModesContext
Identifying specific ways tasks can go wrong
From the articleSpecifically, the data showed a significant difference in the prevalence of certain failure modes between accepted and rejected tasks.
Verifiable DatasetsOutcome
Snorkel's focus on delivering high-quality datasets for customers
From the articleCrawford explained that Snorkel's platform incorporates both human expertise and programmatic methods to create high-quality, verifiable datasets.
Contents(5)

In a presentation at AI Engineer Europe, Kobie Crawford, Developer Advocate at Snorkel, explored the critical role of "Task Fidelity Scaling Laws" in advancing AI model development. Crawford, whose work at Snorkel focuses on integrated research and production, highlighted that the company's origins in academic research, specifically a Stanford AI Lab PhD thesis, led to the development of a library for generating training data for foundation models. This foundational work has evolved into a focus on delivering data sets for their customers' models, with a consistent emphasis on how research integrates with production.

Task Fidelity Scaling Laws: Kobie Crawford on AI Data Quality - AI Engineer
Task Fidelity Scaling Laws: Kobie Crawford on AI Data Quality, AI Engineer

The Importance of Task Quality in AI Training

Crawford began by posing the central question: "Does Task Quality Actually Matter?" She asserted that AI model capabilities are fundamentally bounded by the quality of the training data. This principle holds true regardless of the model architecture, scale, or the specific agent harness used. For agentic benchmarks and evaluations, task quality is synonymous with data quality. However, Crawford noted that the field currently lacks sufficient empirical evidence to definitively prove that curating higher-quality tasks leads to meaningfully better training outcomes. This gap in evidence motivated Snorkel's research into measuring the impact of task quality on model performance.

Defining and Evaluating Task Quality

To address this, Snorkel evaluated terminal-bench style agentic coding tasks against four key acceptance criteria: Achievability, Non-triviality, Functional Correctness, and Reliability. Tasks that passed these criteria were categorized as 'Accepted Tasks,' while those that did not were marked as 'Rejected Tasks.' The objective was to compare the characteristics of accepted versus rejected tasks to validate their curation process and demonstrate that it selects for higher-quality tasks.

Crawford presented data showing that accepted tasks are generally harder and more complex, requiring multi-step workflows rather than single-shot answers. These tasks also resulted in a higher number of tool calls and more reasoning from the models attempting them. Conversely, rejected tasks often represented simpler problems or failures that were less informative for model improvement.

Analyzing Task Failure Modes

The presentation then delved into task failure categories, examining where and why models failed. By categorizing failures, Snorkel AImed to understand the impact of task quality on model training. The analysis revealed that accepted tasks, while more complex, led to 'cleaner' failures, providing more actionable insights for model improvement. Rejected tasks, on the other hand, often resulted in 'noisy' failures that were harder to learn from.

Specifically, the data showed a significant difference in the prevalence of certain failure modes between accepted and rejected tasks. For instance, 'Logic Error' and 'Incomplete' were far more common in accepted tasks, suggesting these models were tackling more challenging problems. Rejected tasks, however, showed a higher proportion of 'Wrong Approach' and 'Syntax Error' failures, indicating issues with the task definition or the model's fundamental understanding of the problem.

The Impact of High-Quality Tasks on Model Performance

The core finding presented was that high-quality tasks lead to dramatically better models. The experiment compared a base model with fine-tuned models using either low-quality or high-quality data. The results indicated a significant uplift in test pass rates when models were fine-tuned on high-quality data. Specifically, there was a +6.2 percentage point improvement from high-quality tasks and a +1.1 percentage point improvement from low-quality tasks, demonstrating a five-fold improvement attributed to data quality alone.

Crawford emphasized that while the models trained on low-quality data did show some improvement over the base model, the gains were marginal compared to those achieved with high-quality data. This underscores the critical importance of data quality in achieving robust and reliable AI model performance. The research also highlighted that the human-in-the-loop process for generating and validating these high-quality tasks is essential for ensuring that models are trained on data that accurately reflects the desired capabilities and challenges.

The Snorkel Approach to Data Curation

Crawford explained that Snorkel's platform incorporates both human expertise and programmatic methods to create high-quality, verifiable datasets. This approach allows for the generation of training data that is not only accurate but also scalable. By applying rigorous criteria and leveraging a combination of human and AI-driven annotation, Snorkel aims to overcome the inherent challenges in defining and measuring task quality, ultimately leading to more effective AI models.

The presentation concluded by highlighting the ongoing efforts at Snorkel to refine their methods for task creation and evaluation, focusing on building benchmarks that are both challenging and informative for AI development. The company's commitment to data quality is a key differentiator in the rapidly evolving AI landscape.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.