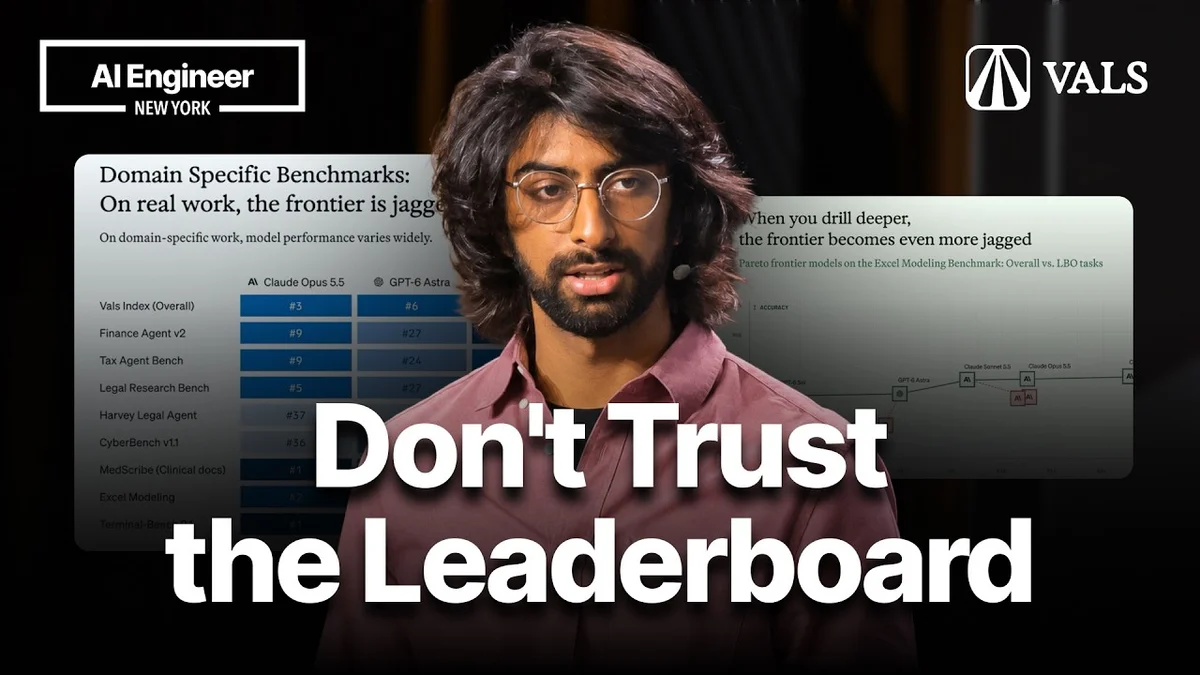
Rayan Krishnan of Vals AI told AI Engineer that Anthropic's $4-in/$20-out Opus 5.5 cost more per completed tax task than the $10-in/$50-out Fable 5.1 despite its lower list price.
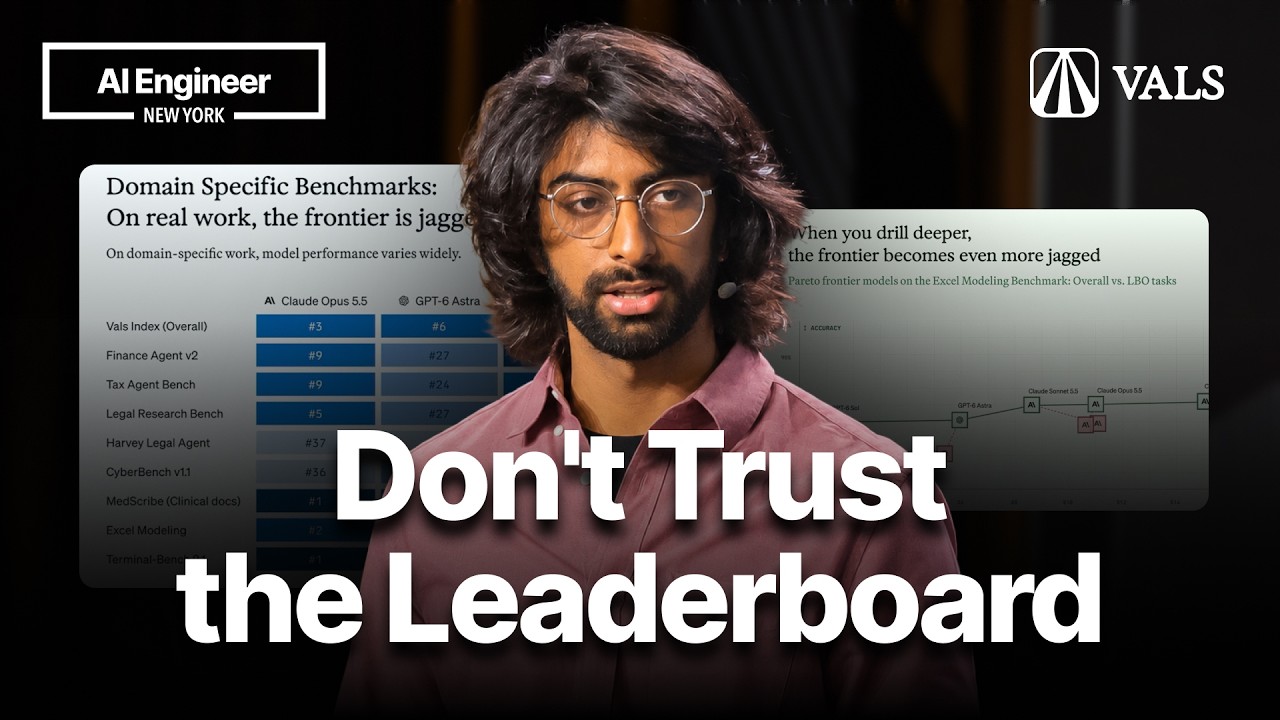
The gap came from token burn, not pricing.
Krishnan said the smaller model scored 3% lower while trying to spend extra tokens to finish the work, so teams paid more for worse accuracy.
That jagged frontier repeats across finance tasks, where Excel modeling in aggregate hides that LBO subtasks run on a lower Pareto curve and drop the supposed frontier model off the efficient edge.
Vals AI now runs more than 6 trillion tokens of evals and ships those checks as Val Smith, which replays GitHub pull requests to test whether an agent could have done the human work and then routes each issue to the cheapest model that clears the bar.
Even the cheapest useful chat today still starts at $0 for free tiers and $8 for ChatGPT Go according to Overpaying for AI pricing data, so routing to the right model matters more than chasing the lowest sticker price.