
Neural networks are the engine of modern AI, but their dense, billions-of-parameters architecture makes them inscrutable. We design the training rules, but the resulting behavior is a tangled mess of connections no human can easily trace. This opacity is a growing liability as AI infiltrates critical sectors like healthcare and finance.
Interpretability, the ability to explain why a model made a decision, is paramount. While techniques like Chain of Thought offer immediate, albeit brittle, explanations by forcing models to show their work, the deeper goal is mechanistic interpretability: reverse-engineering the model’s computations at the most granular level. This path is harder but promises a more robust understanding.
Researchers are now betting that the problem isn't just the complexity of the task, but the structure of the network itself. Traditional models are "dense," meaning nearly every neuron connects to thousands of others, creating functional chaos. The new approach flips this script by training sparse neural networks.
Building Simpler Circuits for Smarter AI
The core innovation is architectural constraint. By forcing the vast majority of a model’s weights to zero, researchers compel the network to achieve its goals using only a tiny fraction of its potential connections. Think of it as forcing a sprawling metropolis to function using only a few key highways instead of every possible side street.
The results, detailed in recent research, are compelling for simpler tasks. When tested on algorithmic challenges, like correctly closing a Python string with the matching quote mark, the resulting sparse models contained small, isolated "circuits" that performed the exact required logic. These circuits were both necessary and sufficient for the task; remove them, and the model fails.
The daily brief
Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.
Join 64,000 other subscribers.
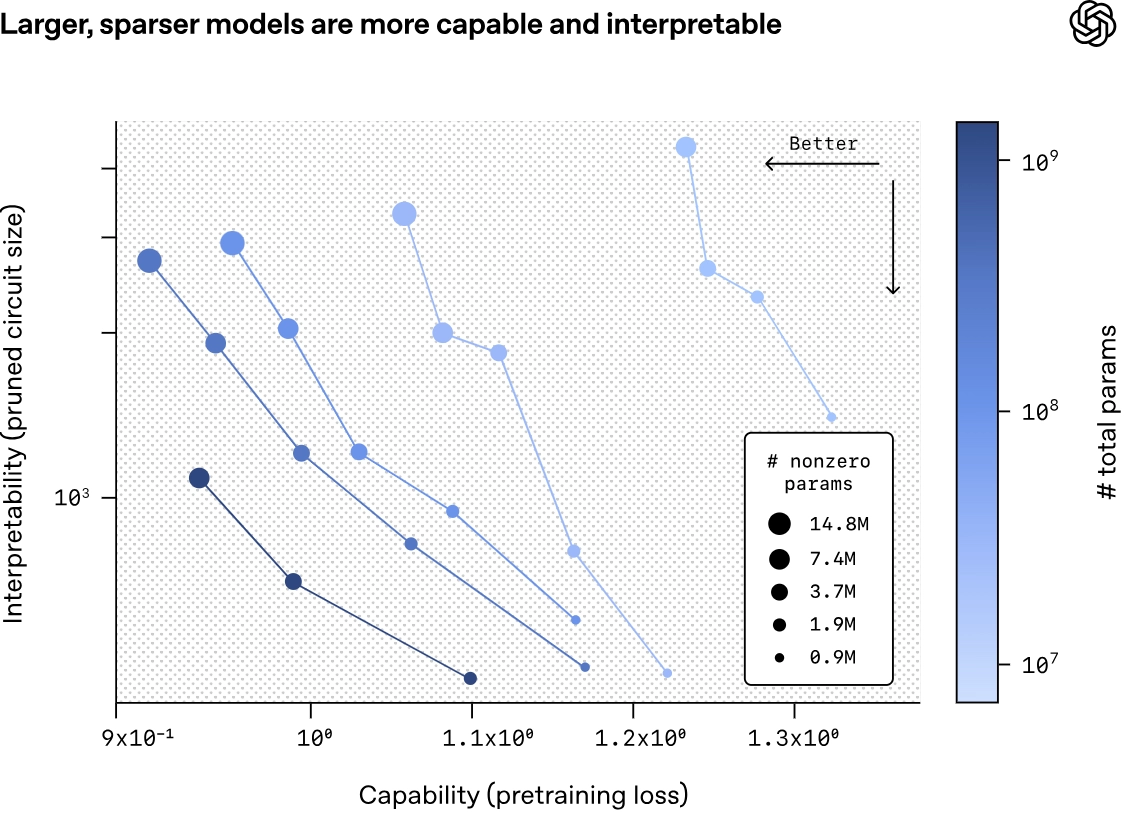
The trade-off is clear: for a fixed model size, increasing sparsity reduces capability while dramatically boosting interpretability. However, the research suggests a path forward: scaling up the *total* number of parameters while maintaining high sparsity allows the model to become both more capable and retain simpler, understandable internal mechanisms. This shifts the interpretability frontier outward.
This work isn't a silver bullet for GPT-5 level complexity yet. The current sparse models are far smaller than frontier LLMs, and much of their computation remains opaque. The next steps involve scaling these techniques or, alternatively, developing methods to extract these clean, sparse circuits from already trained, efficient dense models. If successful, this research offers a tangible roadmap toward building AI systems where we don't just trust the output, but fundamentally understand the underlying mechanism.






