AI Models as Training Data: Weight Space Learning

Professor Damian Borth discusses 'weight space learning,' a novel approach to AI model development that treats trained model weights as data.

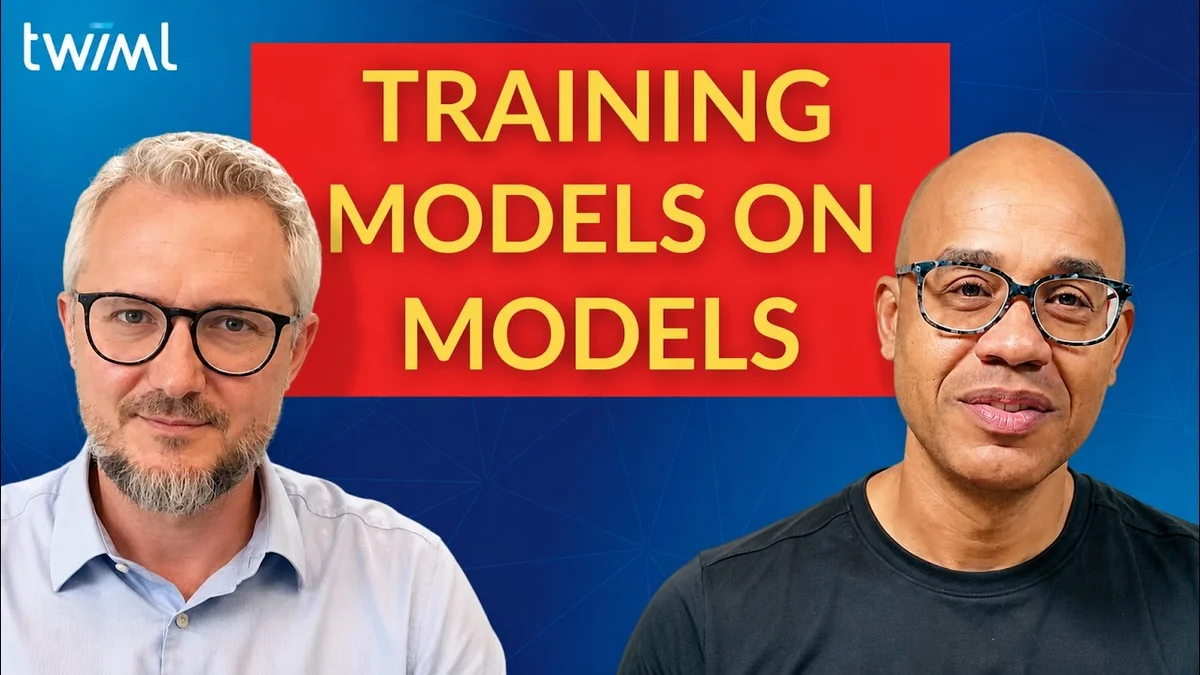
Professor Damian Borth speaking on the TWiML AI Podcast about weight space learning
TWIML
Visual TL;DR
High-quality data scarcityDriver
From the articleIn the quest to continually improve AI foundation models, a major hurdle is the diminishing availability of high-quality training data.
GPU hours investmentContext
From the article 2 mentionsProfessor Borth's research centers on the idea that the thousands or millions of GPU hours spent training a model represent a significant investment in discovering effective parameters.
Traditional solutionsContext
synthetic data and inference-time reasoning are common strategies to address scarcity
From the articleThis would allow users to 'sample on demand your favorite model whatever you need,' effectively replacing traditional pre-training.
Weight Space LearningCore
Professor Borth's novel approach: treating trained model weights as new data
From the article 7 mentionsThe field of 'weight space learning' is relatively new, having gained traction around 2020, but it has already shown surprising effectiveness.
Models as DataContext
neural network weights used as input to train another neural network
From the article 9+ mentionsGallen is exploring a novel approach: treating trained models themselves as data.
Analyze existing modelsEffect
enables analysis of effective parameters discovered during initial model training
From the article 2 mentions'So we can analyze weights of human networks and we can generate weights of neural networks.' This concept of treating weights as an 'input modality' could revolutionize how new models are created for specific tasks or how existing models are analyzed.
Generate new modelsOutcome
facilitates the generation of entirely new AI models from existing weight data
From the article 9+ mentionsBorth likens the process to how language models learn from sentences on the internet to understand and generate language, or how models trained on pixels can analyze and generate images.
Contents(4)

In the quest to continually improve AI foundation models, a major hurdle is the diminishing availability of high-quality training data. While synthetic data and inference-time reasoning are common strategies, Professor Damian Borth of the University of St. Gallen is exploring a novel approach: treating trained models themselves as data. In a conversation on the TWiML AI Podcast, Borth introduced the concept of 'weight space learning,' where the weights of neural networks are used as input to train another neural network, enabling the analysis and generation of entirely new models.

The Core Idea: Models as Data

Professor Borth's research centers on the idea that the thousands or millions of GPU hours spent training a model represent a significant investment in discovering effective parameters. Instead of viewing these weights solely as the end product of training, Borth suggests they can serve as the beginning of a new learning process. 'What happens actually if we take the weights of trained neural networks as the input to train a neural network to understand these weights that we have out there much much better?' Borth posited. This perspective opens up possibilities for faster model creation and more precise analysis of unfamiliar networks.

The full discussion can be found on TWIML's YouTube channel.

Why Models Are AI’s Next Training Dataset | Damian Borth - TWIML
Why Models Are AI’s Next Training Dataset | Damian Borth, from TWIML

Borth likens the process to how language models learn from sentences on the internet to understand and generate language, or how models trained on pixels can analyze and generate images. 'We do the same idea on all the weights of trained neural networks,' he explained. 'So we can analyze weights of human networks and we can generate weights of neural networks.' This concept of treating weights as an 'input modality' could revolutionize how new models are created for specific tasks or how existing models are analyzed. The field of 'weight space learning' is relatively new, having gained traction around 2020, but it has already shown surprising effectiveness.

From Fingerprinting to Generation

The initial motivation for Borth's work, starting in 2020, was to explore whether neural networks could be versioned or fingerprinted like software. The challenge lies in the fact that even minor weight updates during training can lead to significant differences in individual weights, making direct comparison difficult. 'If everything is different, nothing is different,' Borth noted.

The research team's breakthrough came from the idea of compressing neural network weights into a lower-dimensional space. By training an autoencoder on a population of neural networks, they aimed to learn a manifold where these networks reside, potentially encoding information about their training data, hyperparameters, and performance. The first paper published in 2021 demonstrated success on small, toy examples, showing that these compressed embeddings could predict accuracies and other performance metrics. This early work, though limited to thousands of parameters, proved the concept that 'weights are exciting, not only as the output of learning but as the input for learning.'

Scaling Up and Addressing Challenges

The journey from small-scale experiments to practical applications involved overcoming several challenges, particularly in scaling the models. A key hurdle was that early generative models produced 'blurry weights,' lacking the high-frequency details crucial for a network's functionality. Borth recounted the experience of having an autoencoder with a low mean squared error that, when its reconstructed weights were plugged back into a network, 'totally screwed up the entire new network.'

To address this, the team experimented with different loss functions and normalization techniques. A significant step forward came with the idea of windowing model parameters as sequences, which allowed them to scale up to larger networks like ResNets and beyond. This led to collaborations, including one with Michael Mahoney from UC Berkeley, who initially described the work as 'useless' but then contributed to scaling it up. The research also benefited from early community involvement to validate the idea's meaningfulness.

The Future of Weight Space Learning

The field is expanding, with researchers exploring symmetries in weight spaces, mode connectivity, and other phenomena that influence model behavior. Borth highlighted the potential for this approach to significantly reduce the computational cost of training new models. For instance, generating a remote sensing foundation model that previously required 12,000 GPU hours could potentially be achieved with a fraction of that using weight space learning, demonstrating a significant efficiency gain.

Looking ahead, Borth envisions a future where a vast 'foundation model of neural networks' could be trained on all available open-weight models. This would allow users to 'sample on demand your favorite model whatever you need,' effectively replacing traditional pre-training. The team is also exploring prompting with datasets rather than models, enabling the generation of models tailored to specific, private datasets without revealing the data itself, a crucial step for privacy-preserving AI. 'So you're a bank, you are a financial institution, healthcare provider, whatever. You don't reveal your data. You have your data set of I don't know 100 samples, thousand samples. You create one data set embedding. So you cannot infer you know the individual members or samples. You give this embedding to us, we provide you the weights, we give you the weights, you're much faster in continuing training.'

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.