
Artificial Intelligence

Context Engineering: The Key to Better AI Agents

AI experts discuss context engineering strategies, detailing how compaction, caching, and memory management improve AI agent performance and reduce costs.

StartupHub.ai Staff

By StartupHub.ai Staff, reviewed by Daniel Singer, Editor

3 min read

Presentation slide on Context Engineering in 2026
Credit: AI Engineer
Visual TL;DR
AI Context WindowDriver
finite context window fills with data, leading to performance degradation
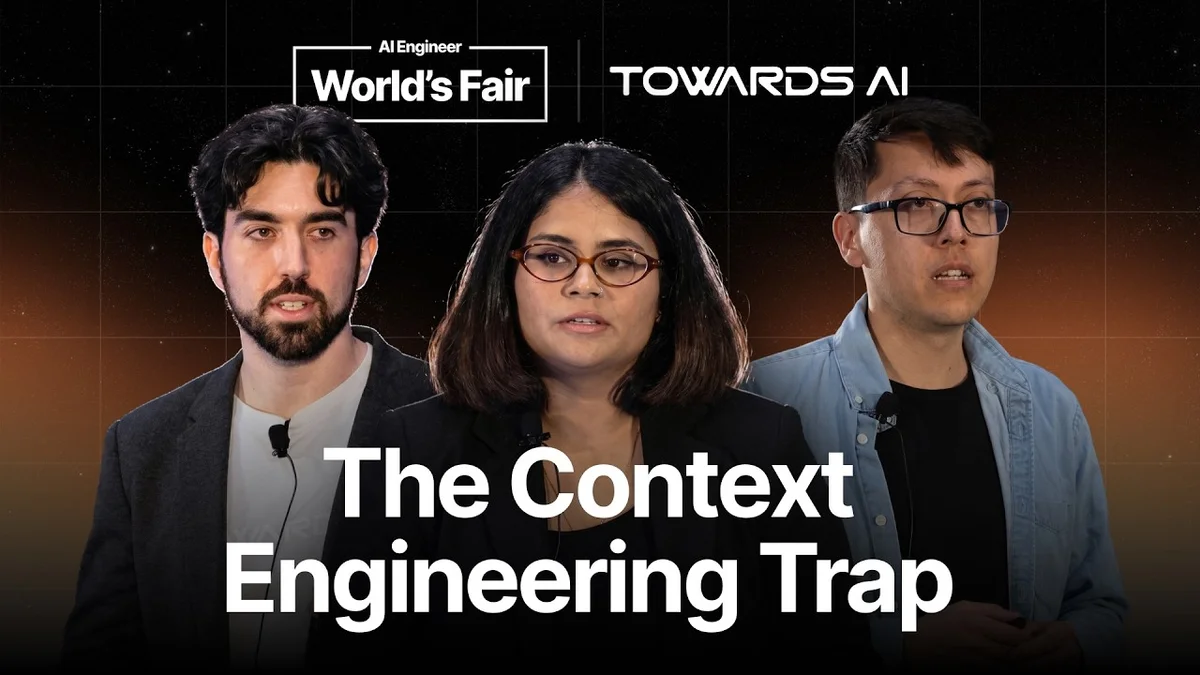
From the article 9+ mentionsLouis-François Bouchard, co-founder and CTO of Towards AI, along with colleagues Omar Solano and Samridhi Vaid, recently explored this vital area, focusing on strategies for managing the context window of large language models.
Context RotDriver
degradation in performance and increased token usage drives up costs
From the article 9+ mentionsTo combat context rot and its associated costs, several techniques were discussed:
Context EngineeringCore
deciding what information an AI model sees at each interaction
From the article 9+ mentionsIn the quest for more effective and efficient AI agents, the concept of "context engineering" is emerging as a critical discipline.
Compaction StrategiesContext
techniques like summarization and filtering to reduce context size
From the article 6 mentionsTowards AI conducted experiments to evaluate various context management strategies.
CachingContext
storing frequently accessed information for faster retrieval and reuse
From the article 3 mentionsA significant point raised was the impact of prompt caching, a feature offered by many LLM providers.
Memory ManagementContext
From the article 5 mentionsThis involves two primary challenges: managing the finite nature of the context window and addressing the statelessness of models, which means they don't retain information across sessions without explicit memory management.
Improved AI PerformanceEffect
better quality responses and more effective AI agent interactions
From the article 3 mentionsThe team emphasized the importance of logging all interactions to analyze performance metrics like cache hit rates, latency, and user feedback.
Reduced CostsOutcome
efficient token usage lowers operational expenses for AI agents
From the article 4 mentionsWhen context is appended rather than transformed, providers can leverage pre-computed caches, drastically reducing costs and latency.
Contents(4)

In the quest for more effective and efficient AI agents, the concept of "context engineering" is emerging as a critical discipline. Louis-François Bouchard, co-founder and CTO of Towards AI, along with colleagues Omar Solano and Samridhi Vaid, recently explored this vital area, focusing on strategies for managing the context window of large language models.

Context Engineering: The Key to Better AI Agents - AI Engineer
Context Engineering: The Key to Better AI Agents, AI Engineer

The core problem, as Bouchard explained, is that as AI agents interact and process information, their context windows become filled with data, leading to a degradation in performance known as "context rot." This not only impacts the quality of the agent's responses but also drives up costs due to increased token usage.

Understanding Context Engineering

Context engineering, in essence, is about deciding what information an AI model sees at each interaction. This involves two primary challenges: managing the finite nature of the context window and addressing the statelessness of models, which means they don't retain information across sessions without explicit memory management.

The components that typically fill an agent's context window include system prompts, tool definitions, chat history, old tool outputs, and retrieved course chunks or memory. The team at Towards AI, which builds AI engineering courses and provides an AI tutor for its students, identified "old tool outputs" as a major bottleneck for scaling context.

Compaction and Offloading Strategies

To combat context rot and its associated costs, several techniques were discussed:

  • Compaction: The fundamental idea is to minimize the context window by retaining only the most relevant information. This can be achieved through methods like observation truncation (cutting off excessive tool output), selective retention (AI deciding what to keep based on the conversation's direction), summarization, and prompt compression.
  • Offloading: This involves moving context data outside the immediate context window. Techniques like "retrieve augmented generation" (RAG) and "GraphRAG" were mentioned as powerful methods for storing and retrieving information from a knowledge base. The team's experience showed that while GraphRAG can be effective for highly interconnected data, it was often costlier and didn't necessarily outperform simpler RAG approaches for their specific use case.

The Power of Caching and Progressive Disclosure

A significant point raised was the impact of prompt caching, a feature offered by many LLM providers. When context is appended rather than transformed, providers can leverage pre-computed caches, drastically reducing costs and latency. However, any modification to the context, such as summarization, can break this cache, forcing recomputation and negating the savings.

The concept of "progressive disclosure" was also highlighted as a best practice, particularly for managing skills. Instead of loading all instructions at once, it's more efficient to load only the necessary components as they are needed, similar to how code modules are handled.

Experimental Findings and Best Practices

Towards AI conducted experiments to evaluate various context management strategies. Surprisingly, in their initial tests, keeping the "full history" without any compaction or modification often yielded the best results in terms of memory recall and was also cheaper and faster, largely due to the benefits of caching. This suggests that for certain use cases and with efficient caching mechanisms, aggressive compaction might not always be the optimal solution.

The team emphasized the importance of logging all interactions to analyze performance metrics like cache hit rates, latency, and user feedback. This data-driven approach is key to understanding which context engineering techniques are most effective for a given application.

Ultimately, context engineering is presented as a holistic discipline that encompasses compaction, memory management, and skill optimization. By carefully deciding what information an AI model receives, developers can significantly improve agent performance, reduce costs, and enhance user experience.

TopicsLouis-François BouchardOmar SolanoSamridhi VaidTowards AIContext EngineeringAI AgentsLLMPrompt Caching

StartupHub.ai StaffDaniel SingerWritten by StartupHub.ai Staff, Editorial teamReviewed by Daniel Singer, EditorAbout

StartupHub.ai Staff, Editorial team

The staff writers of StartupHub.ai, ranging from investment analysts to avid AI tool users, early adopters and critical enthusiasts. Backgrounds span engineering, business and the arts. We hold every piece to rigorous standards of research and review.

Daniel Singer, Editor

Daniel Singer is an AI expert who has been writing about, covering and building AI technology since 2018.

More from Daniel Singer

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute.

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

