#Prompt Caching
5 articles with this tag
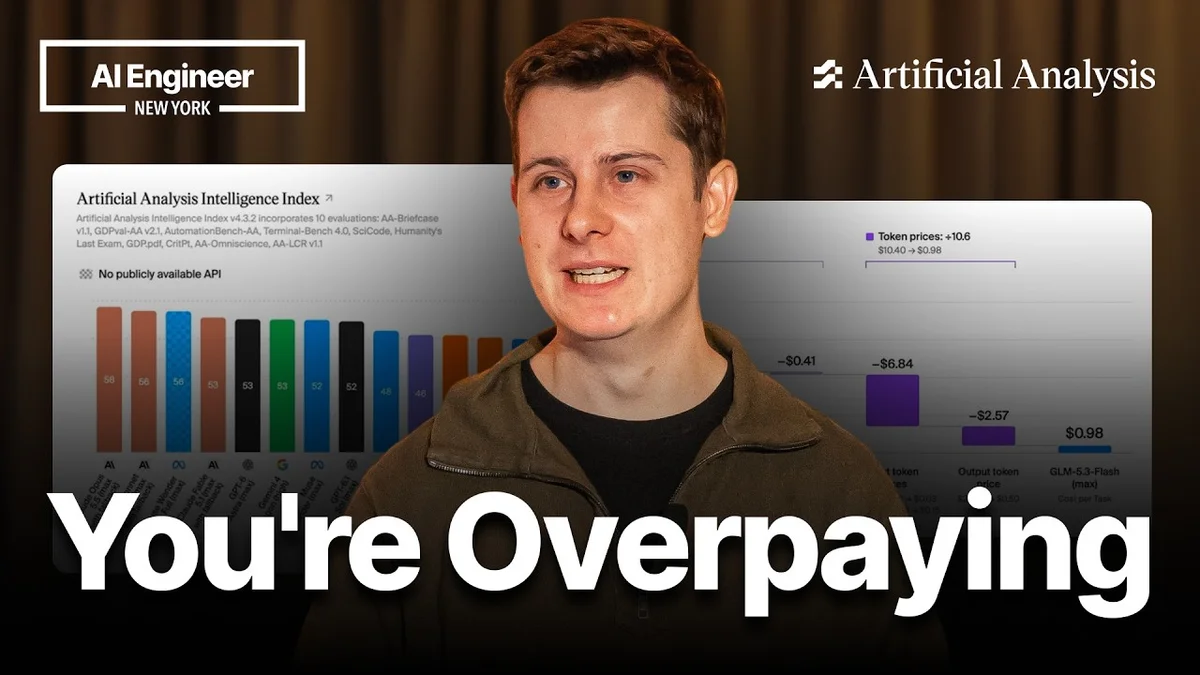
Without cache, AI agents cost 10x more
Artificial Analysis put Opus 5.5 at $21 per agent task with cache and over $200 without, showing cache hit rate now drives cost.
Context Engineering: The Key to Better AI Agents
AI experts discuss context engineering strategies, detailing how compaction, caching, and memory management improve AI agent performance and reduce costs.
CAG vs. Long Context: AI's Memory Explained
IBM's Martin Keen explains how AI models use Long Context and Cache Augmented Generation (CAG) to process information, highlighting the trade-offs and efficiency gains of each approach.
Databricks Speeds Up Open-Source LLMs
Databricks enhances open-source LLM performance with automatic prompt caching, reducing latency and boosting throughput without user configuration.
Prompt Caching: Turbocharging AI Transformers
Prompt caching dramatically reduces LLM latency and costs by storing and reusing intermediate computations, making AI transformers faster for applications like chatbots.

