DeepSeek V4.1 Flash is cheap, fast and visual

DeepSeek V4.1 Flash 1017 brings native vision and CED architecture with 8B/16B active parameters and 1M context at $0.10/$0.50.

S
StartupHub.ai Staff
2 min read
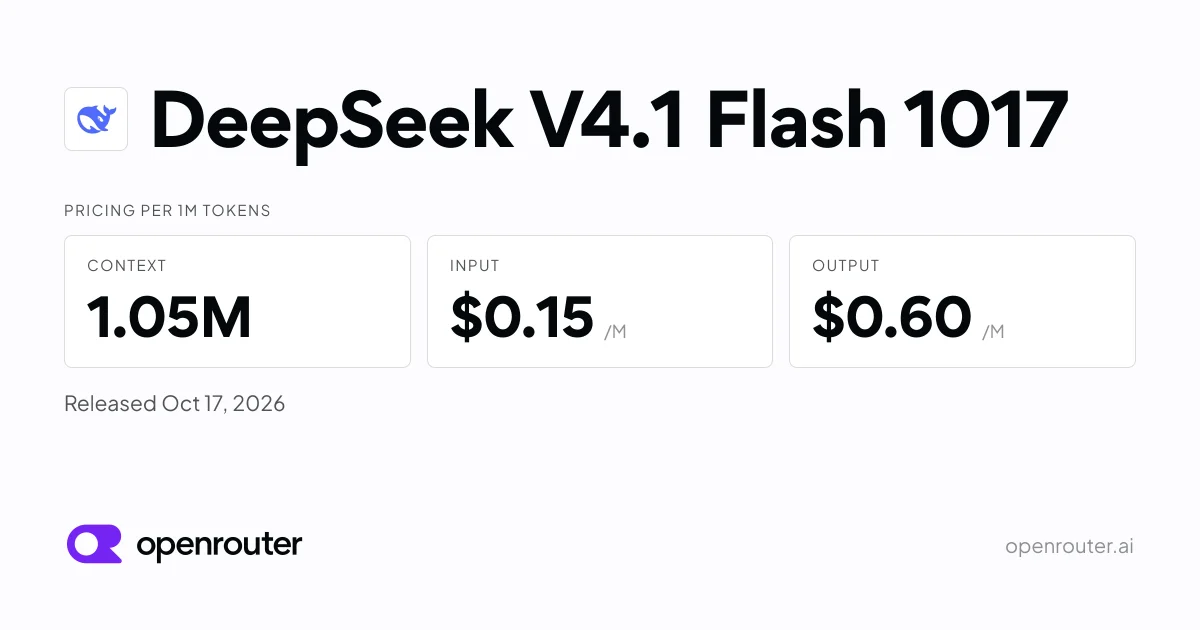
DeepSeek V4.1 Flash 1017 model card showing pricing and benchmarks on OpenRouter
Openrouter

No prediction venue as of prices OpenRouter listing for DeepSeek V4.1 Flash 1017 on Polymarket or Kalshi, with zero volume and no odds movement to track and no liquidity to trade.

Not financial advice.

Markets move fast.

OpenRouter lists DeepSeek V4.1 Flash 1017 as the snapshot served as deepseek-flash with 1,048,576 token context and $0.10 per million input and $0.50 per million output according to OpenRouter.

DeepSeek says the model is a 552B-parameter sparse mixture-of-experts that activates 8B on input and 16B on output on its first Causal Encoder-Decoder architecture.

Vision is native with visual and text embeddings trained jointly from the start of pre-training, not retrofitted like the earlier V4 Flash Vision Exp.

Compressed KV caching cuts cache memory to roughly a quarter of the previous Flash generation according to OpenRouter, which lowers cost on long agentic workloads.

DeepSeek positions it as the cost-efficient tier of the V4.1 family and claims it exceeds V4 Pro on performance, speed and task completion time according to OpenRouter.

That claim sets the comparison against V4 Pro directly, while the external field shows the 1017 snapshot ranks 35 of 224 at 65.61 across 33 displayable evaluations according to benchlm.ai.

Pricing and speed underline the pitch, with inference.net posting $0.10 input and $0.50 output at 0.45s latency and 103 tok/s and DeepSeek posting 153 tok/s at $0.15/$0.60 according to OpenRouter.

Benchmarks per Artificial Analysis via OpenRouter list Intelligence Index 39.5, HLE 39.2%, AA-LCR 84.0%, SciCode 51.9% and Terminal-Bench 4.0 26.8% with AA-Omniscience Non-Hallucination Rate at 3.5%.

You feel the trade in practice when the cache saving matters more than raw reasoning, and when that 3.5% non-hallucination rate forces stricter tool checks.

Availability was 99.91% over three days with 100% uptime on inference.net and DeepSeek routes according to OpenRouter, so routing still matters if you pin a provider.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

StartupHub.ai Staff

Written by

StartupHub.ai Staff

Editorial team

The staff writers of StartupHub.ai, ranging from investment analysts to avid AI tool users, early adopters and critical enthusiasts. Backgrounds span engineering, business and the arts. We hold every piece to rigorous standards of research and review.