
OpenAI has introduced GPT-5.3-Codex, a new model that significantly expands the capabilities of its Codex agentic coding assistant. This latest iteration promises to handle complex, long-running tasks involving research, tool use, and execution, effectively acting as a digital colleague that can be directed mid-task without losing context.
A Leap in Agentic Capabilities
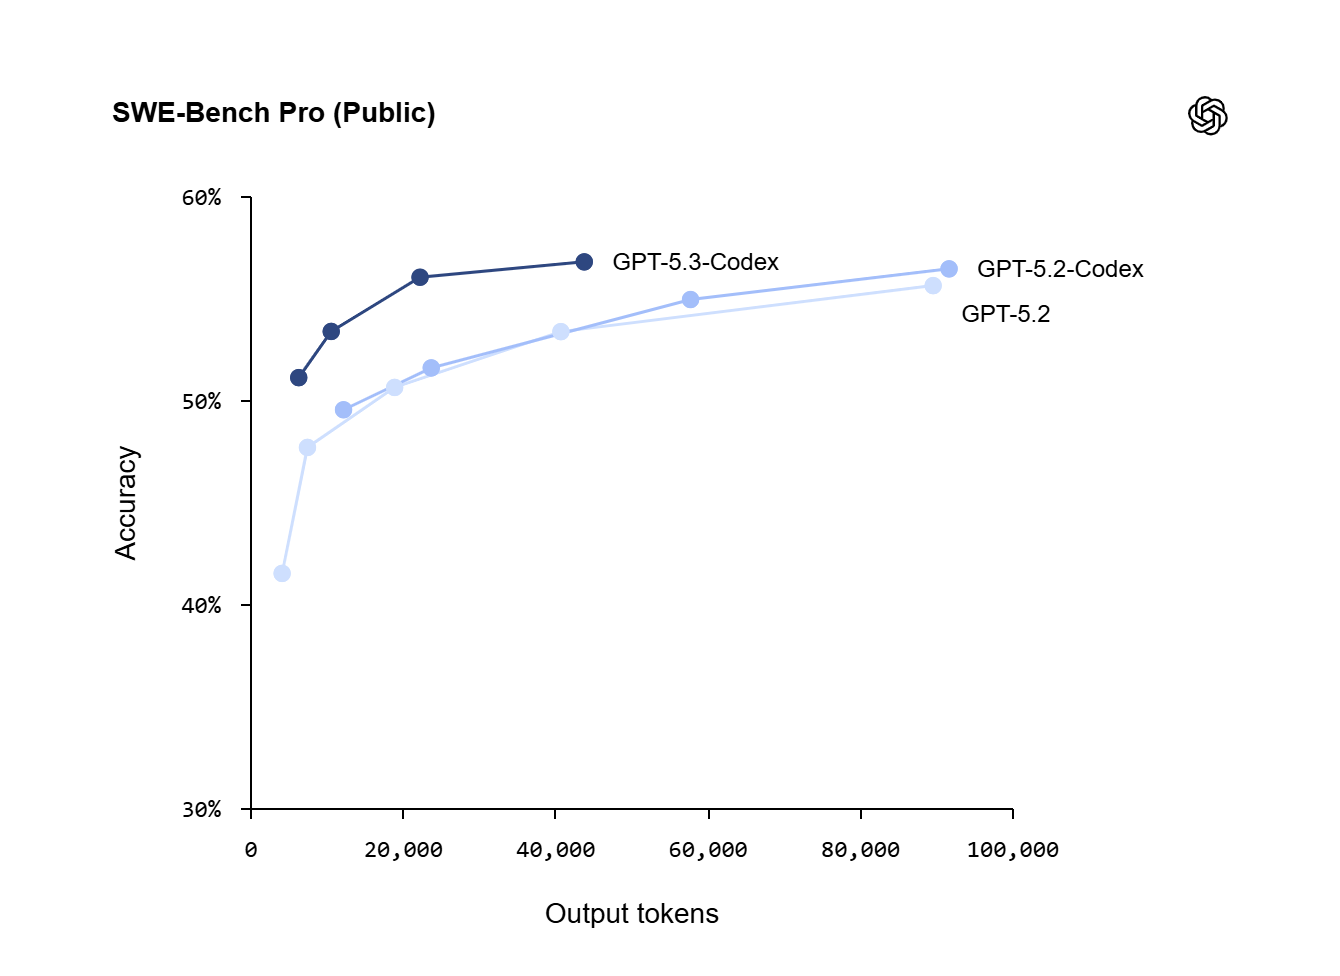
GPT-5.3-Codex merges the cutting-edge coding prowess of GPT-5.2-Codex with the enhanced reasoning and professional knowledge of GPT-5.2. OpenAI claims it's 25% faster, enabling it to tackle more demanding projects. This advancement positions it as the most capable agentic coding model to date, setting new industry benchmarks on evaluations like SWE-Bench Pro and Terminal-Bench.
Self-Improvement and Broader Application
Remarkably, GPT-5.3-Codex was instrumental in its own creation. Early versions were used by the Codex team to debug training processes, manage deployments, and analyze test results, drastically accelerating its development cycle. This self-sufficiency signals a new era where AI agents can actively contribute to their own evolution.
The model's scope now extends far beyond code generation. OpenAI states that GPT-5.3-Codex can perform nearly any task developers and professionals can accomplish on a computer, including debugging, deployment, monitoring, writing product requirement documents, editing copy, and conducting user research.
Performance Benchmarks and Real-World Demos
On SWE-Bench Pro, a rigorous test of real-world software engineering across four languages, GPT-5.3-Codex achieved state-of-the-art performance. It also surpassed previous models on Terminal-Bench 2.0, which assesses essential terminal skills for coding agents. The model achieved these results using fewer tokens, allowing for more extensive user-driven development.
The daily brief
Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.
Join 64,000 other subscribers.
To showcase its abilities, OpenAI tasked GPT-5.3-Codex with building two complex web games from scratch over several days. The resulting racing and diving games demonstrate sophisticated functionality, including multiple maps, in-game items, and resource management. The model iterated autonomously based on prompts like "fix the bug" or "improve the game", showcasing its capacity for long-running agentic tasks.
For everyday web development, GPT-5.3-Codex shows improved intent understanding. Prompts for landing pages now result in more functional and sensible defaults. For instance, a prompt for a landing page for "Quiet KPI" resulted in a design that automatically presented yearly pricing as a discounted monthly rate and included an auto-transitioning testimonial carousel, making the page more complete and production-ready out-of-the-box.
Beyond the Code: Professional Knowledge Work
GPT-5.3-Codex demonstrates strong performance on professional knowledge tasks, matching GPT-5.2 on the GDPval benchmark. This evaluation assesses a model's ability to handle tasks across 44 occupations, such as creating presentations and spreadsheets. Examples of generated work include financial advice slides, retail training documents, NPV analysis spreadsheets, and fashion presentations, all based on detailed prompts and contextual information.
The model also shows significantly improved computer-use capabilities on the OSWorld benchmark, where agents must complete productivity tasks in a visual desktop environment. GPT-5.3-Codex's performance in this area suggests a significant step towards a general-purpose agent capable of executing a wide array of real-world technical work.
An Interactive Collaborator
The Codex app now offers more interactive collaboration with GPT-5.3-Codex. Users receive frequent updates, allowing them to steer the model's work in real time by asking questions and providing feedback. This continuous dialogue ensures users remain informed and can influence the direction of the task from beginning to end.
Cybersecurity Advancements
GPT-5.3-Codex is the first model classified as high capability for cybersecurity tasks under OpenAI's Preparedness Framework, and the first trained to identify software vulnerabilities. OpenAI is implementing a comprehensive safety stack, including training, monitoring, and threat intelligence, to support defensive use while mitigating potential misuse.
To accelerate cyber defense research, OpenAI is launching Trusted Access for Cyber, a pilot program. They are also expanding access to Aardvark, a security research agent, and partnering with open-source projects to offer free codebase scanning. A $10 million commitment in API credits will further support cyber defense efforts.
Availability
GPT-5.3-Codex is available via paid ChatGPT plans. API access is planned for release soon. The model runs 25% faster for Codex users due to infrastructure enhancements, with co-design and service on NVIDIA GB200 NVL72 systems.
With GPT-5.3-Codex, the focus shifts from solely writing code to using it as a tool to operate computers and complete work end-to-end. This evolution positions Codex as a more general collaborator, expanding the possibilities for both creators and the scope of achievable tasks.



