AI Coding Token Reduction: Rajkumar Sakthivel on Local Code Index

Rajkumar Sakthivel from Tesco discusses how a local code index reduced AI coding tokens by 94%, optimizing costs and performance by focusing on context over model improvements.

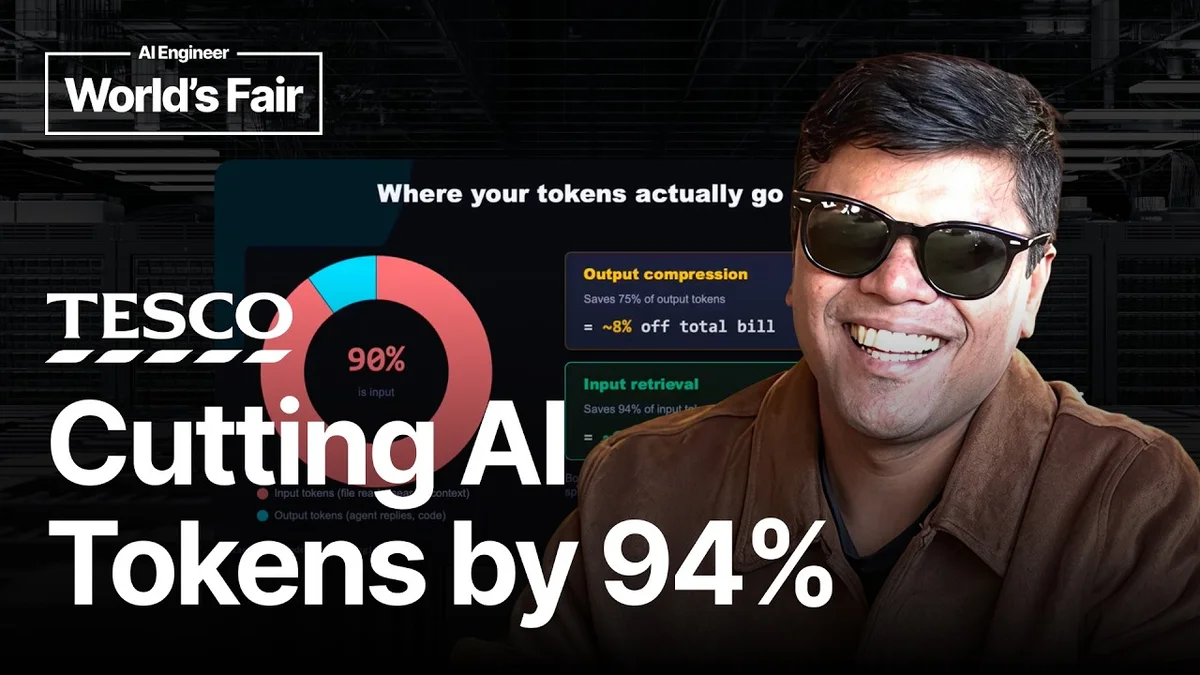
Rajkumar Sakthivel presenting on AI coding token reduction with a local code index.
AI Engineer
Visual TL;DR
Excessive AI ContextDriver
sending ~45,000 tokens, only ~5,000 useful
From the article 3 mentionsSakthivel highlighted a common assumption in AI coding tools: the belief that sending as much context as possible to the model leads to better results.
High Costs & LatencyDriver
From the article 2 mentionsThis inefficiency led to increased costs and latency, prompting a search for a more optimized approach.
Local Code IndexCore
focusing on context optimization, not model improvements
From the article 2 mentionsThe core revelation is that by implementing a local code index, they were able to achieve a remarkable 94% reduction in AI coding tokens, significantly cutting costs and improving performance.
Combined Retrieval MethodsContext
leveraging multiple techniques for better context selection
From the article 2 mentionsBy employing Reciprocal Rank Fusion (RRF), they combined the strengths of both approaches, achieving a recall of 0.90 and covering each method's blind spots.
94% Token ReductionOutcome
achieved remarkable reduction in AI coding tokens
From the article 7 mentionsThis demonstrated a reduction from 83,681 tokens per query in a full-file baseline to just 4,927 tokens after retrieval, and further down to 523 tokens after compression, achieving a 94% saving.
Input OptimizationContext
crucial for efficient and effective AI interactions
From the article 3 mentionsThe data showed that 90% of tokens are typically input (file reads, search, context), while only 10% are output (agent replies, code).
Optimized Costs & PerformanceEffect
From the article 2 mentionsThe core revelation is that by implementing a local code index, they were able to achieve a remarkable 94% reduction in AI coding tokens, significantly cutting costs and improving performance.
Knowing When Retrieval WrongContext
the hard part of identifying incorrect context
Contents(7)

In a presentation at the AI Engineer World's Fair, Rajkumar Sakthivel, representing Tesco, shared a compelling strategy for optimizing AI coding tools. The core revelation is that by implementing a local code index, they were able to achieve a remarkable 94% reduction in AI coding tokens, significantly cutting costs and improving performance.

AI Coding Token Reduction: Rajkumar Sakthivel on Local Code Index - AI Engineer
AI Coding Token Reduction: Rajkumar Sakthivel on Local Code Index, AI Engineer

The Problem with Excessive Context

Sakthivel highlighted a common assumption in AI coding tools: the belief that sending as much context as possible to the model leads to better results. However, their experience revealed that out of approximately 45,000 tokens sent per query, only around 5,000 were actually useful. This inefficiency led to increased costs and latency, prompting a search for a more optimized approach.

The Solution: Local Code Indexing

The team focused on optimizing the context rather than the AI model itself. They explored several avenues, including better prompts, adjusted model settings, and output compression. However, the most impactful solution identified was the introduction of a retrieval layer between the codebase and the AI agent. This layer, running locally, indexes code and retrieves only the relevant chunks, drastically reducing the token count.

The architecture involves several steps:

  • Tree-sitter Chunking: Breaking down code into meaningful AST-aware splits across 10 languages.
  • Hybrid Retrieval: Employing both vector search (for conceptual similarity) and BM25 (for exact keyword matching).
  • Chunk Compression: Compressing the retrieved code chunks, achieving an 89% reduction.
  • Code Graph: Utilizing a code graph to understand relationships and dependencies within the code.
  • Confidence Scoring: Implementing a system to filter results based on confidence levels, ensuring only relevant information is passed to the AI.

Crucially, this entire process runs locally, eliminating cloud dependencies, API calls, and ensuring data privacy. The system stores data in three SQLite files, making it efficient and accessible.

The Power of Combined Retrieval Methods

Sakthivel also discussed the limitations of relying on a single retrieval method. Vector search, while effective for finding conceptually related code even with different naming conventions, can miss exact matches. Conversely, BM25 excels at precise keyword matching but struggles with semantic similarity. By employing Reciprocal Rank Fusion (RRF), they combined the strengths of both approaches, achieving a recall of 0.90 and covering each method's blind spots.

The Importance of Input Optimization

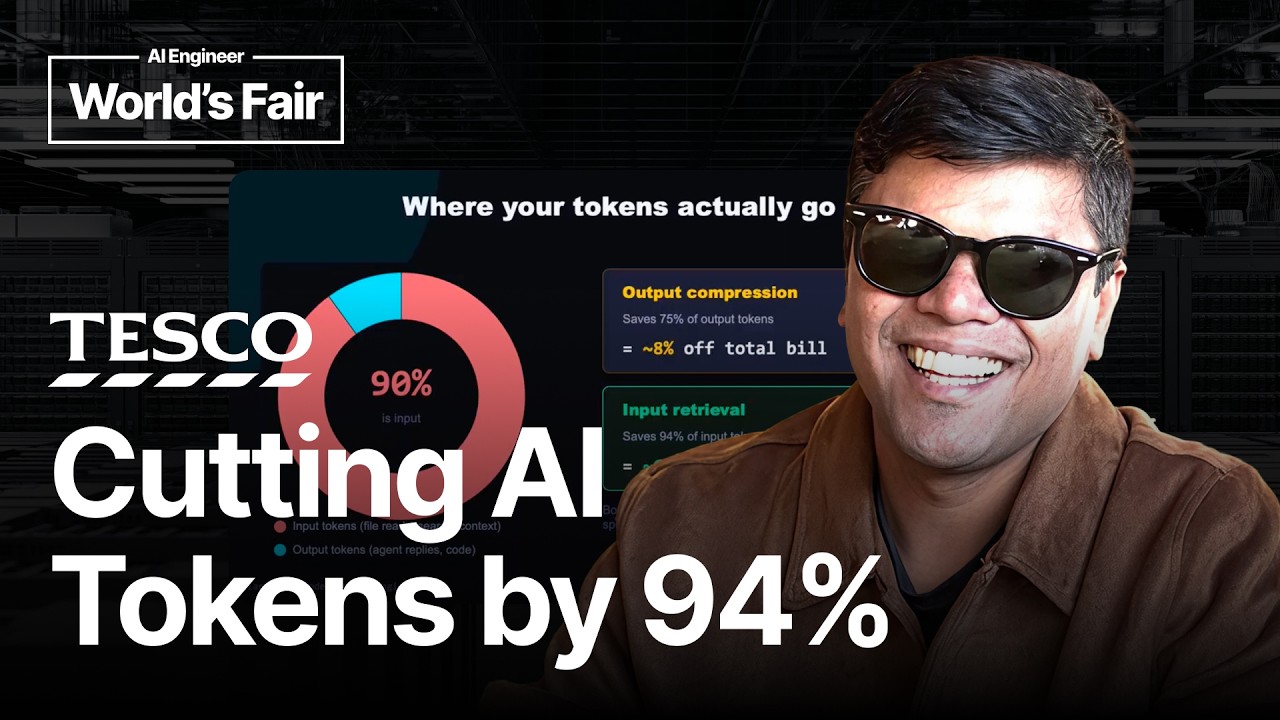
A key takeaway presented was the breakdown of where AI coding tokens are actually used. The data showed that 90% of tokens are typically input (file reads, search, context), while only 10% are output (agent replies, code). This starkly illustrates why optimizing the input side is critical for cost savings. Input retrieval, in particular, was shown to save approximately 61% of the total bill, whereas output compression saved around 8%.

The Hard Part: Knowing When Retrieval is Wrong

Sakthivel emphasized that the most challenging aspect wasn't simply retrieving relevant code, but determining when the retrieval process itself was flawed. They experimented with LLM-based scoring, which was accurate but added latency and cost. Fixed thresholds also proved problematic, as they struggled with short queries and long queries alike. Ultimately, a simpler heuristic approach, using a weighted average of similarity, keywords, and recency, proved most effective, delivering results with low latency and no API calls.

Measurable Impact and Open Source

The presentation included benchmark data from a real project using the FastAPI framework. This demonstrated a reduction from 83,681 tokens per query in a full-file baseline to just 4,927 tokens after retrieval, and further down to 523 tokens after compression, achieving a 94% saving. The recall remained high at 0.90. The project is open-source, with a QR code and GitHub link provided for users to try it themselves and run the benchmarks.

Multi-Agent and Shared Memory

The system is designed for a multi-agent environment, allowing various AI coding tools like Claude Code, Cursor, VS Code Copilot, Codex CLI, Gemini CLI, Tabnine, and OpenCode to utilize a single, shared index. This shared index is per-project, not per-agent, and decisions persist across sessions and tools, creating a unified and efficient coding experience.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.