Your best prompt from last year is now making Claude slower and pricier. Lance Martin, Member of Technical Staff at Anthropic, told AI Engineer that old tricks have become debt teams keep paying for.
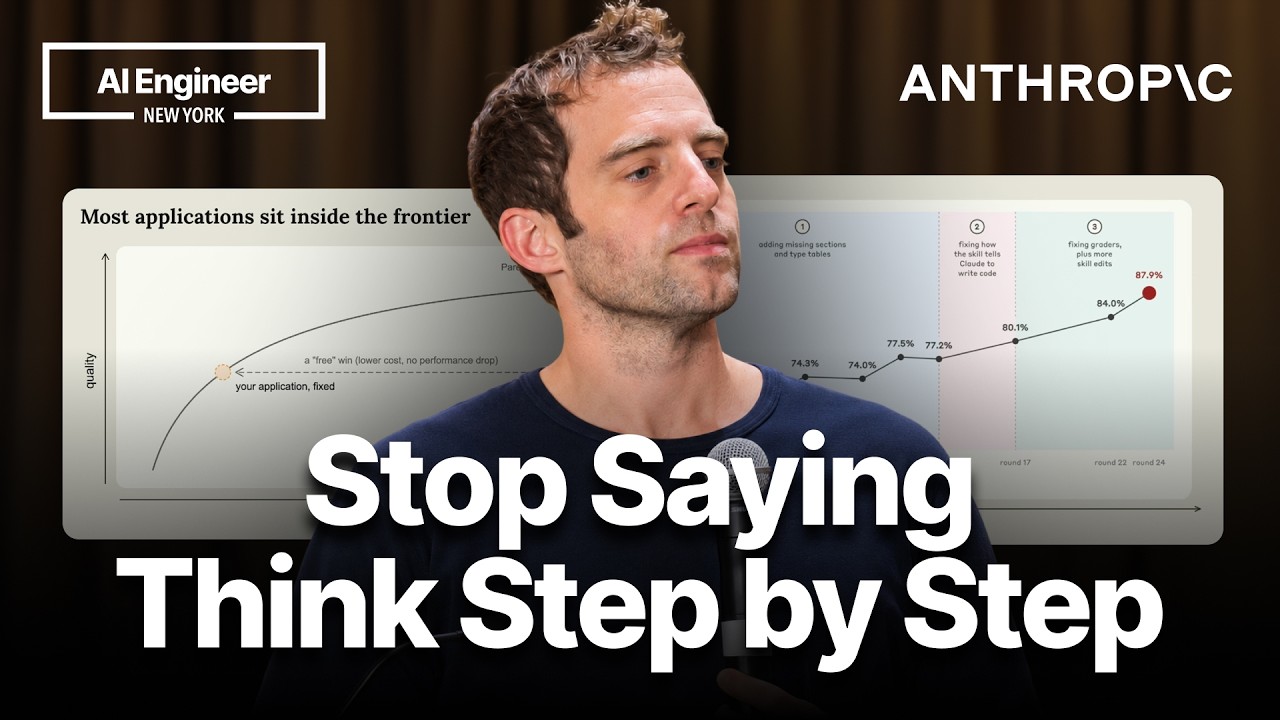
"Prompts accumulate debt just like code," Martin said, and the bill shows in lines like "think step-by-step," "double-check your work" and "be maximally thorough" that frontier models no longer need, according to Martin. Those boosters raise token use and can cut quality because stronger models try to obey contradictory rules instead of ignoring one, Martin said.
The first fix is an audit. Martin demoed Claude API prompt audit and checkup prompt audit commands that flag those anti-patterns across Claude Code and Claude API use. In shipping builds the check surfaces as /doctor prompt-audit, an alias for /checkup prompt-audit, and it scans files like CLAUDE.md, AGENTS.md, rules, skills and subagents without reading settings or .mcp.json, according to operator notes.
Prompt cache, a store that reuses repeated context across calls to cut price and delay, is the second fix. Martin said cache reads run at about a tenth the rate of base tokens, and Claude Code tracks hit rate religiously because it decides the economics. Running cache optimization on internal benchmarks found savings of up to 72% with no meaningful change in performance, according to Martin.
An eval, a scored set of tasks that proves whether a change actually helped, comes next. Martin demoed Claude API build eval to draft the runner, pick cases from traces and enforce binary rubrics with low run-to-run variance. Hill climbing, an automated loop that tests prompt and setting tweaks against that score and keeps winners, then hunts for cheaper configs while guarding against overfitting with train and test splits, Martin said.
The loop can work. Martin cited a 50-ticket support eval where moving from Opus 48 to Opus 55 saved money and lifted quality slightly, then audit added another gain on both axes. A docs skill started at 66% and climbed sharply after rewriting, and one cost hunt found a 90% reduction with better performance, according to Martin. Strip the boosters, fix the cache order, then try a stronger model at low effort. Effort, a setting that tells Claude how hard to think, is often cheaper on Opus 5.5 low than Sonnet high, Martin said.