
AI Research

Bertrand Charpentier on AI Benchmarking Challenges

Bertrand Charpentier of Pruna AI discusses the challenges in AI benchmarking, the limitations of public leaderboards, and the importance of considering both quality and efficiency.

StartupHub.ai Staff

By StartupHub.ai Staff, Editorial team

3 min read

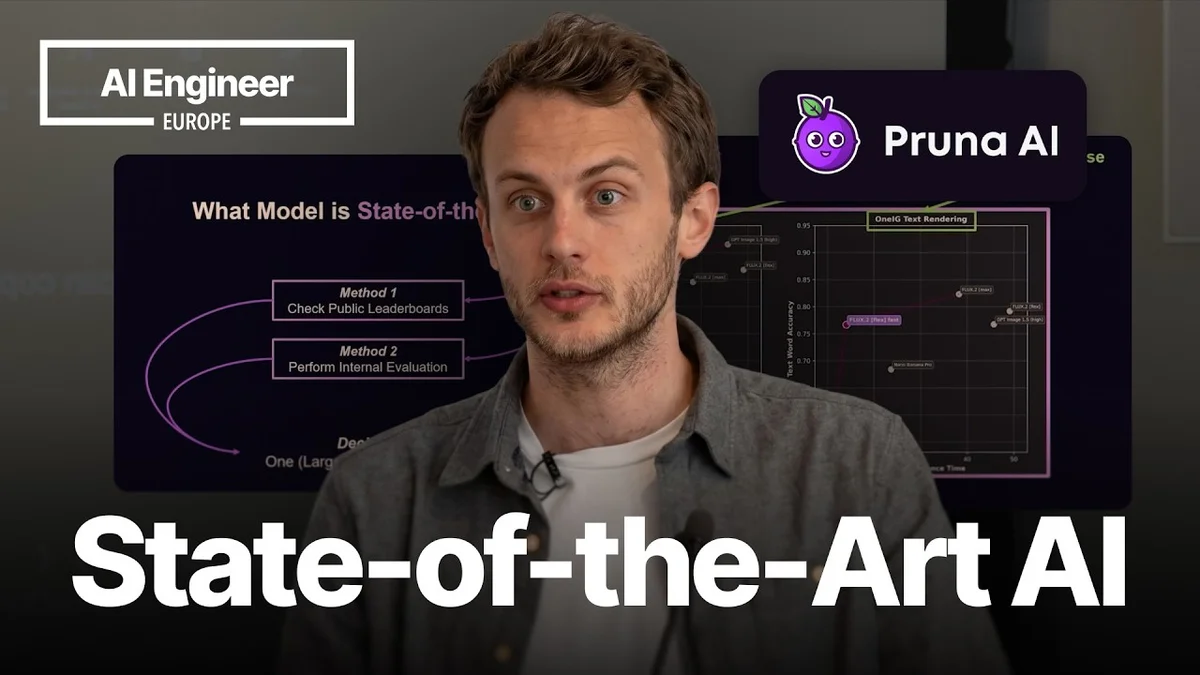
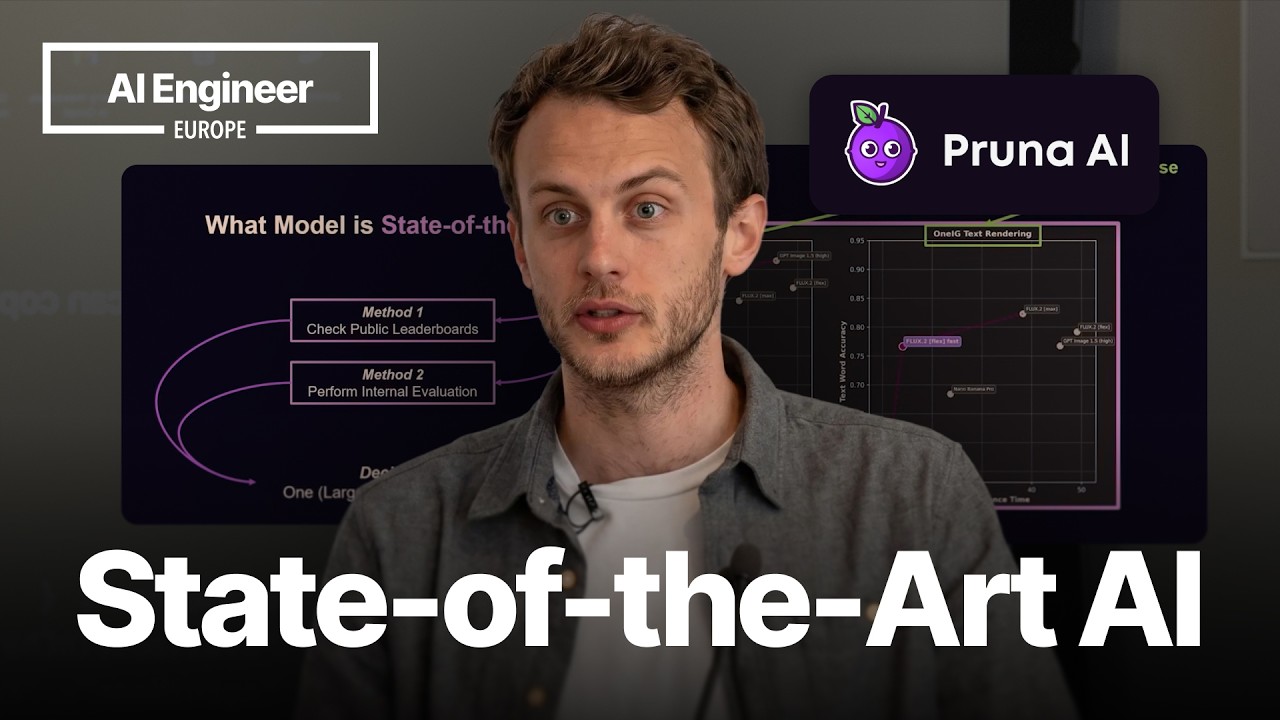
Bertrand Charpentier presenting on AI benchmarking challenges
Bertrand Charpentier, Founder, President & Chief Scientist at Pruna AI, speaking at an AI conference.Credit: AI Engineer
Visual TL;DR
Bertrand CharpentierCore
From the article 9 mentionsBertrand Charpentier, Founder, President & Chief Scientist at Pruna AI, discusses the complexities and challenges of determining what constitutes 'state-of-the-art' in AI models.
AI Benchmarking ChallengesDriver
ambiguity in 'state-of-the-art' interpretation across researchers
From the article 4 mentionsBertrand Charpentier, Founder, President & Chief Scientist at Pruna AI, discusses the complexities and challenges of determining what constitutes 'state-of-the-art' in AI models.
Robust BenchmarkingContext
considering both quality and efficiency for reliable evaluation
From the article 3 mentionsIn his presentation, Charpentier highlights common pitfalls in AI benchmarking and offers insights into more reliable evaluation methods.
Public Leaderboard IssuesDriver
inconsistent rankings for same models across different leaderboards
From the article 3 mentionsThe presentation outlines several key issues associated with using public leaderboards for AI model evaluation.
Future of BenchmarkingEffect
evolving towards more comprehensive and standardized methods
From the article 3 mentionsHe also touches upon the computational cost associated with exhaustive internal benchmarking.
Internal Evaluation LimitsDriver
focus on quality or efficiency, not both simultaneously
From the article 2 mentionsWhile internal evaluation methods offer more control and customization, Charpentier cautions against relying solely on them.
Contents(5)

Bertrand Charpentier, Founder, President & Chief Scientist at Pruna AI, discusses the complexities and challenges of determining what constitutes 'state-of-the-art' in AI models. In his presentation, Charpentier highlights common pitfalls in AI benchmarking and offers insights into more reliable evaluation methods.

Bertrand Charpentier on AI Benchmarking Challenges - AI Engineer
Bertrand Charpentier on AI Benchmarking Challenges, AI Engineer

The Ambiguity of 'State-of-the-Art'

Charpentier begins by addressing the inherent ambiguity in the term 'state-of-the-art' within the AI community. He notes that different researchers and organizations may have varying interpretations, leading to a lack of a universal standard. This ambiguity is further compounded by the common practice of relying on public leaderboards to gauge model performance.

Problems with Public Leaderboards

The presentation outlines several key issues associated with using public leaderboards for AI model evaluation. Firstly, Charpentier points out that each leaderboard often presents a different ranking for the same models. This inconsistency arises from variations in the datasets used, the evaluation metrics employed, and the specific tasks or use cases being tested. For instance, a model that excels in one leaderboard might perform poorly in another due to differences in how 'performance' is quantified.

Furthermore, Charpentier highlights that public leaderboards can suffer from issues like duplicate entries and a lack of statistically significant sample sizes. This can lead to misleading conclusions about a model's true capabilities. He illustrates this with examples of how models can have vastly different rankings across different leaderboards, making it difficult for users to make informed decisions.

The Limitations of Internal Evaluation

While internal evaluation methods offer more control and customization, Charpentier cautions against relying solely on them. He explains that manual inspection, a common internal evaluation technique, can lead to biased results because the evaluator's personal preferences and biases can heavily influence their judgments. This subjective approach may not accurately reflect the model's performance across a broader user base or in real-world application scenarios.

The daily brief

Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.

Join 64,000 other subscribers.

He also touches upon the computational cost associated with exhaustive internal benchmarking. Running extensive tests on numerous models across various tasks can be prohibitively expensive and time-consuming, especially for organizations with limited resources.

Towards More Robust AI Benchmarking

Charpentier advocates for a more nuanced approach to AI model evaluation. He suggests that instead of relying on a single leaderboard or a purely manual assessment, a more comprehensive strategy is needed. This involves:

  • Evaluating on multiple samples: To ensure statistical significance and account for variability in model performance.
  • Considering use-case conditions: Benchmarks should be relevant to the specific applications where the AI model will be deployed.
  • Utilizing multiple benchmarks: Cross-referencing results from various leaderboards and evaluation methods to gain a more holistic view.
  • Assessing model efficiency: Beyond just quality, it's crucial to consider factors like inference time, cost, and energy consumption.

Charpentier presents data showing the significant differences in compute time and cost between different models for the same task, emphasizing the trade-offs between quality and efficiency. For example, he contrasts the compute time and cost of generating images with the ChatGPT Image model versus a P-Image-Edit model, highlighting how optimized models can achieve comparable or superior results with drastically reduced resources.

The Future of Benchmarking

In conclusion, Charpentier stresses that effective AI model selection requires a balanced approach that considers both quality and efficiency, utilizing a combination of reliable benchmarks and tailored evaluations. He suggests that the AI community needs to move towards more standardized and transparent benchmarking practices to ensure accurate and meaningful comparisons of AI models.

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

TopicsBertrand CharpentierPruna AIAI ResearchMachine LearningBenchmarkingAI Models

StartupHub.ai Staff

Written by

StartupHub.ai Staff

Editorial team

The staff writers of StartupHub.ai, ranging from investment analysts to avid AI tool users, early adopters and critical enthusiasts. Backgrounds span engineering, business and the arts. We hold every piece to rigorous standards of research and review.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute, free.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.


