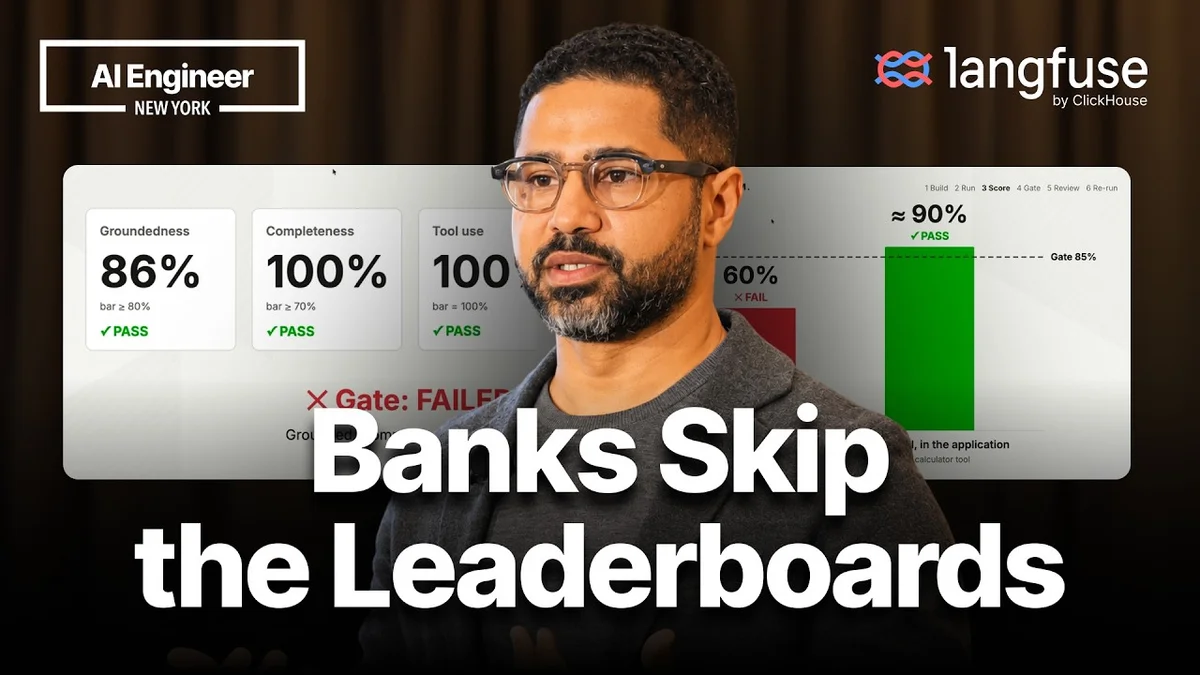
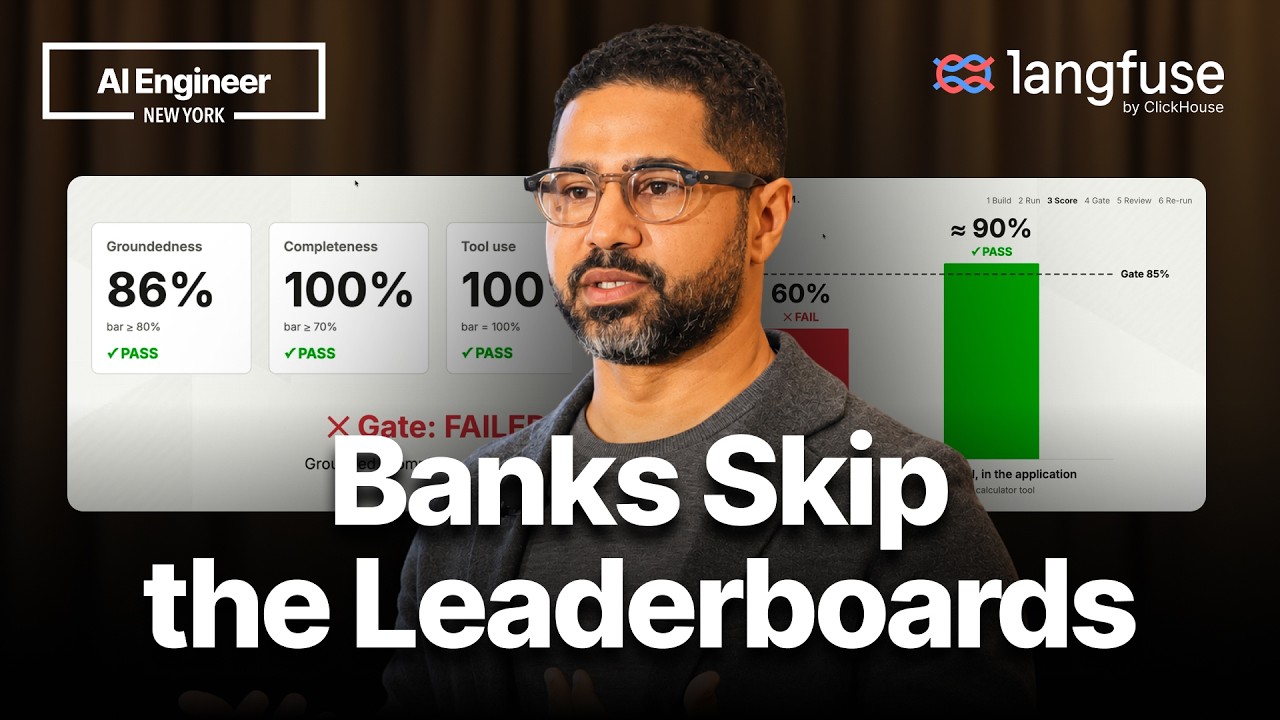
Doneyli De Jesus demoed a bank-grade gate for AI agents on AI Engineer, and the affected system is a 10K analyst agent for investment bankers. The deployment stays local, gated from the internet and air-gapped inside the bank's data centers.
Before this, public benchmarks set the signal. Opus 5 topping leaderboards told teams about model capability, not app readiness. Now the bank ignores that signal and certifies the application instead.
De Jesus said the bank told his team, "We don't certify models here. We certify applications." The anchor is a golden dataset of inputs, expected outputs and metadata. The agent runs, traces become evidence, and scores give pass or fail.
Early runs showed the split. Groundedness hit 97% on internal sources, but numerical accuracy fell to 60%. The team added a deterministic calculate tool and lifted accuracy to 95%, clearing an 85% gate. Regulatory compliance is binary and a zero still blocks promotion even if the average looks strong.
The process then loops through domain experts. Failures curate an annotation queue, experts review traces, and approved examples flow back into the golden dataset. The bank tested sets of 150 and 1,500 questions and cut evaluation from weeks to minutes. Langfuse already visualizes multi-step execution, its Agent Graphs added in November 2025 infer graph structure from observation timings, per DataCamp.
The daily brief
Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.
Join 64,000 other subscribers.
De Jesus said a blend of deterministic checks, path checks and LLM judges is required, and relying only on LLM judges will not cut it. Any change to system prompt, model or tool triggers a new gate run, and the next clearance is scheduled on the next config promotion.