In a recent discussion on the Latent Space podcast, Simon Eskildsen, co-founder and CEO of TurboPuffer, delved into the intricate relationship between artificial intelligence, search, and the foundational role of databases in powering these advancements. The conversation, hosted by Swyx (editor of Latent Space), provided a deep dive into the technical considerations and market trends shaping the future of data infrastructure for AI applications.
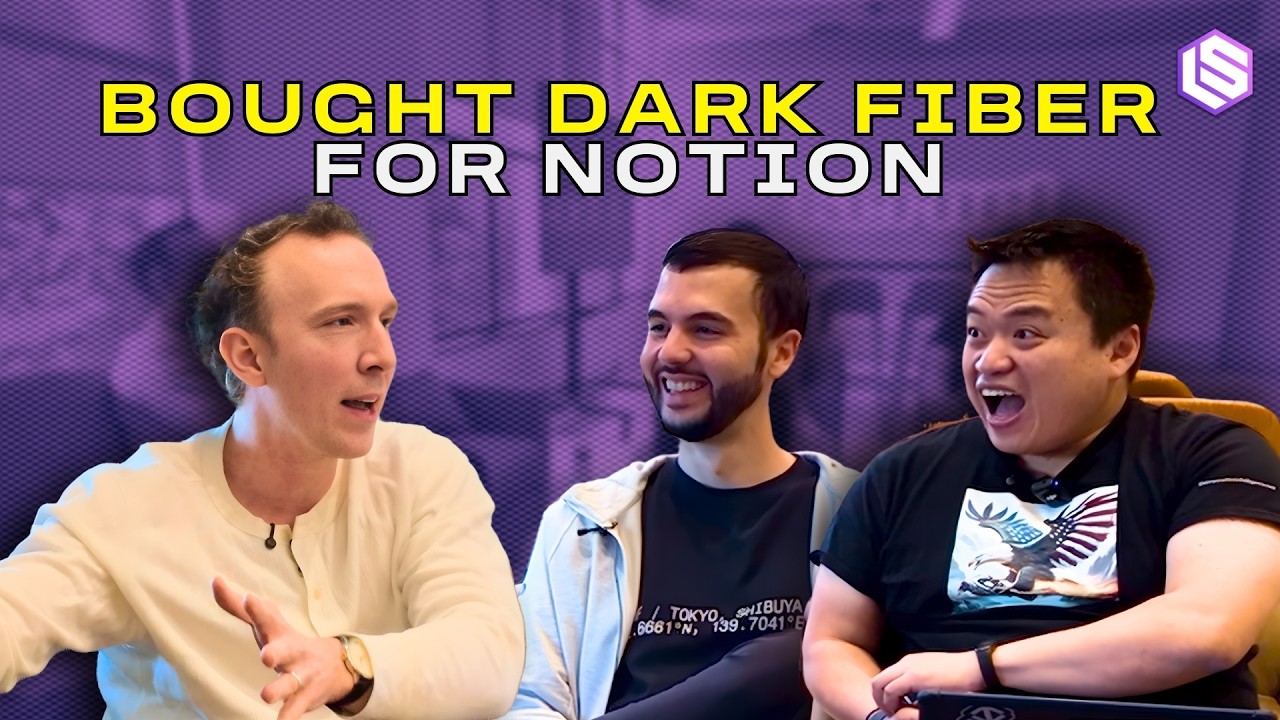
Meet the Experts
Simon Eskildsen brings a wealth of experience from his tenure at Shopify, where he spent a decade working on infrastructure and scaling challenges. His journey from a principal engineer to a key player in the infrastructure team provided him with firsthand insights into the demands of high-throughput, low-latency systems. Eskildsen's background is rooted in navigating the complexities of large-scale data management and the evolution of technology stacks to meet growing user needs. He is also noted for his work in the performance testing space, contributing to tools like k6.
Swyx, the host and editor of Latent Space, is a prominent figure in the tech community, known for his insightful analysis of AI, startups, and emerging technologies. His ability to distill complex technical topics into accessible conversations makes him an ideal guide for exploring the nuances of AI infrastructure.
The Rise of AI Search and Database Demands
The core of the discussion revolved around the increasing demand for sophisticated search capabilities, particularly in the context of unstructured data and the burgeoning field of AI. Eskildsen highlighted that while traditional databases have served well for structured data, the explosion of unstructured data, text, images, audio, and video, requires new approaches to indexing, querying, and retrieval.
Eskildsen articulated a clear thesis: building a successful AI-powered search solution necessitates two key ingredients. Firstly, a significant volume of data, often measured in petabytes, which requires efficient storage and retrieval mechanisms. Secondly, a new category of workload that leverages this data for tasks such as semantic search, recommendation engines, and generative AI applications. He noted that this shift necessitates a re-evaluation of existing database architectures.
The daily brief
Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.
Join 64,000 other subscribers.
The conversation emphasized that traditional databases, while robust for their intended purposes, often struggle to efficiently handle the massive scale and the unique query patterns associated with AI workloads. The sheer volume of unstructured data and the complexity of semantic queries mean that traditional indexing methods can become bottlenecks.
TurboPuffer's Approach: vector databases and Beyond
Eskildsen introduced TurboPuffer as a company focused on addressing these challenges. He explained that TurboPuffer's core offering is built around the concept of vector databases, which are designed to store and query high-dimensional vector embeddings. These embeddings, generated by AI models, capture the semantic meaning of data, enabling more nuanced and effective search capabilities.
He elaborated on the technical underpinnings, explaining that TurboPuffer aims to provide a scalable and performant solution for storing these embeddings. The challenge, he noted, lies not just in storing the data but in efficiently retrieving relevant information based on vector similarity searches. This involves complex algorithms and optimized data structures to ensure low latency and high throughput.
Eskildsen highlighted the shift from keyword-based search to semantic search, where the meaning and context of queries are understood, not just the literal terms. This is where vector embeddings and vector databases play a crucial role. He stated, "We can take all of the world's knowledge, all the exabytes and exabytes of data, and we can compress that into a few terabytes of weights, right? We can compress into a few terabytes of weights, how to reason with the world, how to make sense of the knowledge, but we have to somehow connect that to something external that actually holds that data, right, in full fidelity and in truth."
The "Triple Threat" of Database Innovation
Eskildsen outlined what he termed the "triple threat" for building a successful database company in this new era:
- New Workload: The emergence of AI and its associated workloads, demanding capabilities beyond traditional database operations.
- New Storage Architecture: The need for optimized storage solutions that can handle the scale and structure of vector embeddings and other AI-generated data.
- New Query Paradigm: The shift towards similarity search and complex pattern matching, requiring new query languages and indexing techniques.
He further emphasized that companies like Snowflake and Databricks, while powerful, were built on older paradigms and may struggle to natively accommodate these new requirements without significant adaptation. The fundamental architectural differences, he suggested, create a gap that specialized solutions like TurboPuffer aim to fill.
Challenges and Future Outlook
The conversation also touched upon the inherent challenges in this space, including the cost of infrastructure, the complexity of managing large-scale AI models, and the need for robust data governance. Eskildsen acknowledged that while the potential is immense, the practical implementation requires careful consideration of these factors.
He expressed optimism about the future, highlighting the rapid pace of innovation in the AI and database sectors. The ability to efficiently store, index, and query vast amounts of unstructured data using semantic understanding is a key enabler for a new generation of AI-powered applications. TurboPuffer's focus on providing a specialized, high-performance solution positions them to play a significant role in this evolving ecosystem.
The discussion underscored that the success of AI hinges on the underlying infrastructure, and companies like TurboPuffer are at the forefront of building the next generation of data management systems tailored for the AI era.