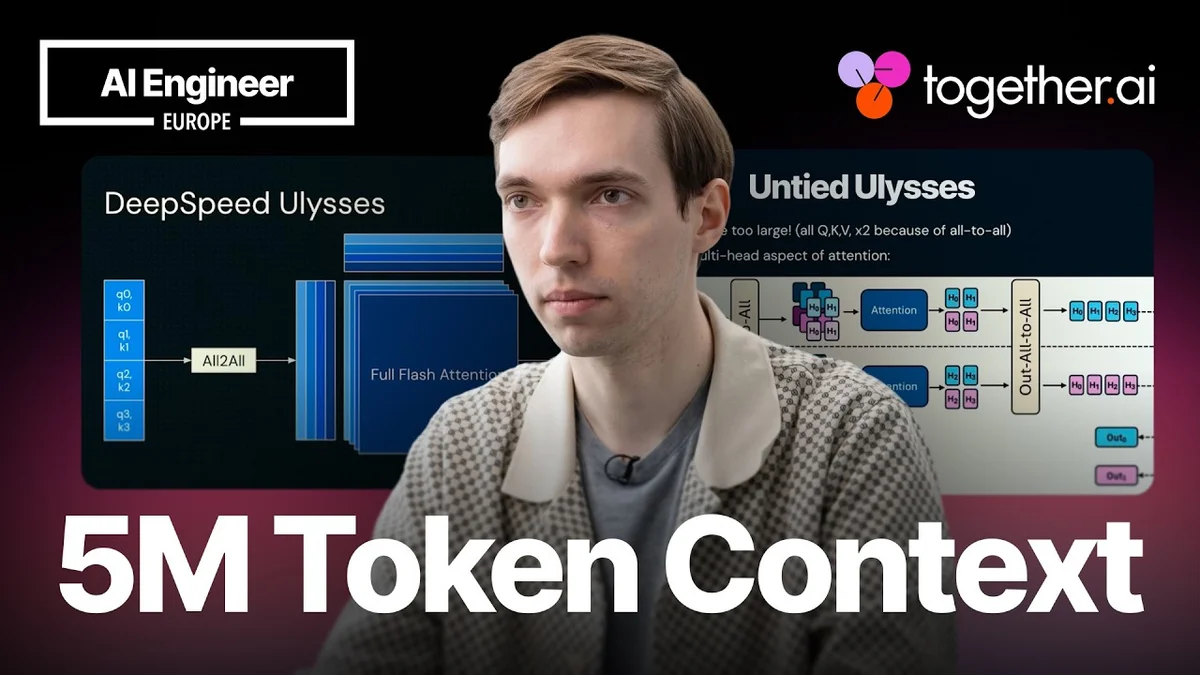
Together AI Pushes LLM Context Limits to 5 Million Tokens

Max Ryabinin from Together AI discusses breaking barriers in LLM training, detailing techniques to achieve 5 million token context lengths and their impact on memory and performance.

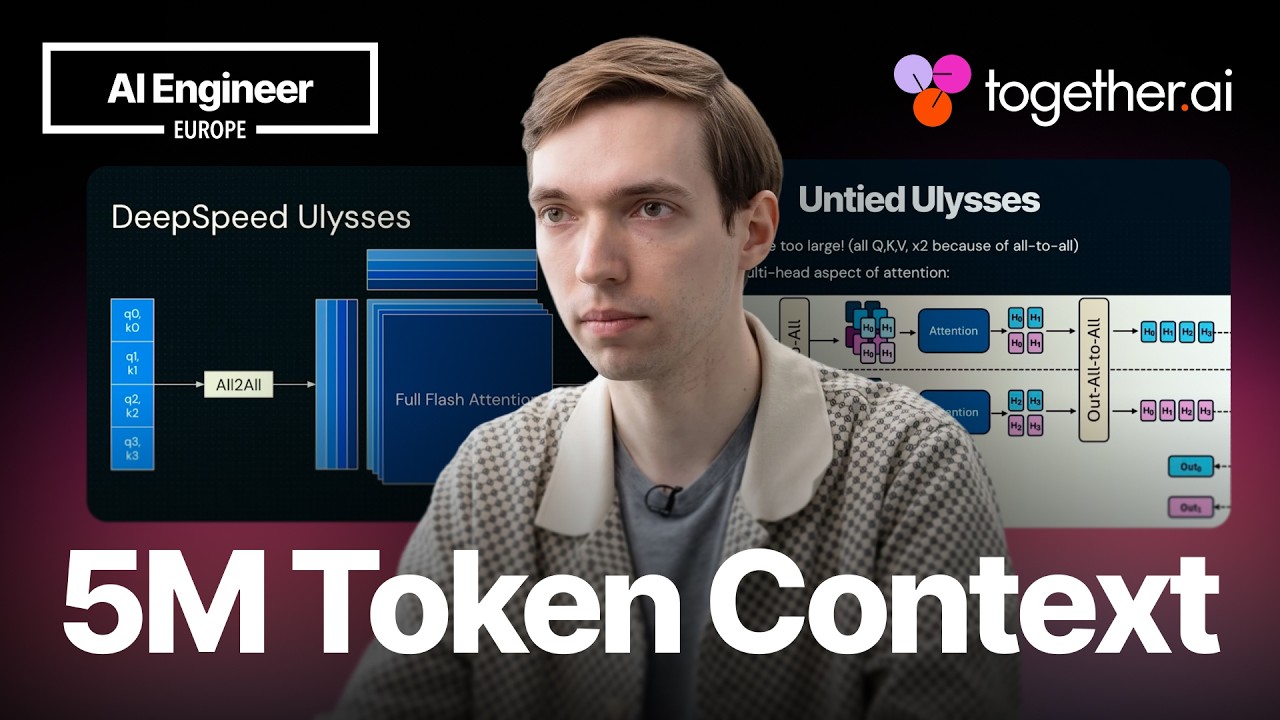
Max Ryabinin presenting on a stage about LLM context length
Max Ryabinin, VP R&D, Model Shaping at Together AI, discusses breaking barriers in long context LLM training.· AI Engineer
Visual TL;DR
Demand for Long ContextDriver
From the article 4 mentionsHe emphasized the growing demand for LLMs that can process and understand vast amounts of text, driving the need for longer context lengths.
Transformer BottlenecksDriver
quadratic computation, linear memory complexity with sequence length
From the article 4 mentionsRyabinin summarized the key takeaways: training models with large context lengths is challenging, bottlenecks can appear unexpectedly, and tools like the PyTorch Memory Profiler are invaluable for debugging.
Together AI's RoleCore
From the article 3 mentionsRyabinin began by outlining Together AI's role as an AI Native Cloud provider, offering services from GPU clusters to model shaping and inference.
New Training TechniquesCore
methods to overcome memory and computational limitations
From the article 9+ mentionsRyabinin highlighted several key techniques employed to overcome these limitations.
Pushing Context LimitsEffect
achieving 5 million token context lengths
Impact on PerformanceOutcome
improved memory and computational efficiency
Future DirectionsContext
further advancements in LLM context capabilities
Contents(4)

Max Ryabinin, VP of R&D and Model Shaping at Together AI, presented "Road to 5 Million Tokens: Breaking Barriers in Long Context Training" at AI Engineer Europe. The talk detailed the challenges and solutions involved in training large language models (LLMs) with extremely long context windows, aiming to push the boundaries beyond current capabilities.

Together AI Pushes LLM Context Limits to 5 Million Tokens - AI Engineer
Together AI Pushes LLM Context Limits to 5 Million Tokens, AI Engineer

Together AI's Approach to Long Context Training

Ryabinin began by outlining Together AI's role as an AI Native Cloud provider, offering services from GPU clusters to model shaping and inference. He emphasized the growing demand for LLMs that can process and understand vast amounts of text, driving the need for longer context lengths.

The primary challenges in training models with long context lengths stem from the inherent computational and memory complexities of transformer architectures. Standard transformers exhibit quadratic complexity in computation and linear complexity in memory with respect to the sequence length. This means that as the context window grows, the resources required for training increase dramatically, often leading to out-of-memory (OOM) errors.

Addressing Memory and Computational Bottlenecks

Ryabinin highlighted several key techniques employed to overcome these limitations. Fully Sharded Data Parallelism (FSDP) is a crucial method for distributing model parameters, gradients, and optimizer states across multiple GPUs, thereby reducing the memory footprint on each individual GPU. This allows for the training of larger models or the use of longer sequences.

The presentation then introduced DeepSpeed Ulysses, a system designed for efficient training of extreme-length transformer models. Ulysses employs a technique where attention computations are untied, allowing for the parallel processing of different attention heads across multiple GPUs. This strategy helps to manage the memory burden associated with processing long sequences.

Activation checkpointing was also discussed as a vital optimization. This technique reduces memory usage by recomputing activations during the backward pass rather than storing them all in memory. While this increases computation time, it significantly alleviates memory constraints, enabling the training of models with much larger context windows.

Pushing Towards 5 Million Tokens

The talk showcased empirical results demonstrating the effectiveness of these methods. Initial experiments with a Llama 3-8B model showed that standard training runs out of memory with 3 million tokens. Applying FSDP alone reduced memory usage but still resulted in OOM errors. The combination of FSDP with Ulysses and activation checkpointing (AC) brought the memory usage down to 15.0 GB, allowing for successful training.

Further experiments with a larger Qwen 32B model and 5 million tokens illustrated the cumulative benefits of these techniques. By stacking FSDP, Ulysses, activation checkpointing, and a custom approach called "UPIPE" (which involves tiling large matrix multiplications along the sequence axis), Together AI achieved significant memory savings. The UPIPE approach, in particular, allowed for the reuse of intermediate buffers across different stages of computation, further optimizing memory usage.

The results presented clearly indicated that training with larger chunk sizes in these memory-efficient methods leads to both reduced memory consumption and increased throughput, demonstrating the scalability of these approaches.

Key Takeaways and Future Directions

Ryabinin summarized the key takeaways: training models with large context lengths is challenging, bottlenecks can appear unexpectedly, and tools like the PyTorch Memory Profiler are invaluable for debugging. He also pointed to their research paper for further details on their methods, including "untied Ulysses" and "UPIPE," which allow for more efficient parallelization of attention computations across multiple heads and GPUs.

The presentation concluded by highlighting the potential for these advancements to unlock new possibilities in LLM applications, enabling models to process and understand much larger documents, codebases, and datasets.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.