AI Research

Engram's Jack Morris on Scaling AI Compute on Context

Engram's Jack Morris discusses the AI challenge of scaling compute on personal context, moving beyond public data to achieve deeper model understanding and personalized capabilities.

StartupHub.ai Staff

By StartupHub.ai Staff, reviewed by Daniel Singer, Editor

3 min read

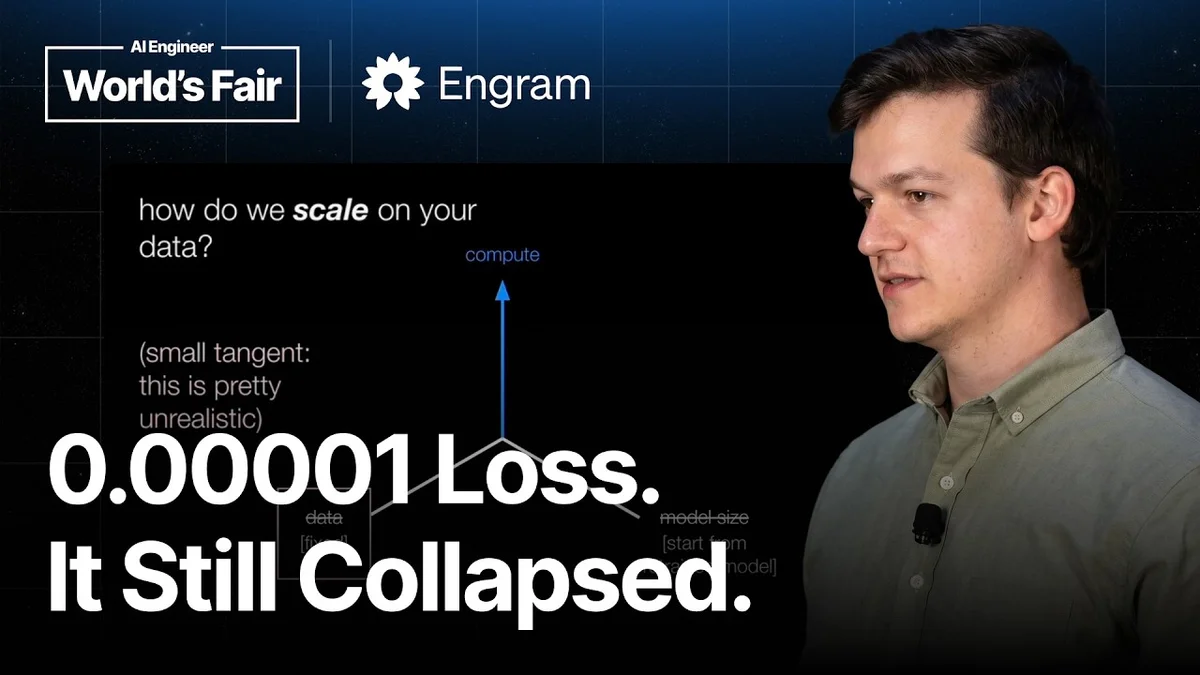
Jack Morris presenting on scaling compute on context at AI Engineer World's Fair
Credit: AI Engineer
Visual TL;DR
AI Public Data LimitsDriver
models have breadth from vast public datasets but lack personalized understanding
From the articleHowever, he stressed that this scaling has historically been confined to public data.
Missing Deep IntuitionDriver
AI connects concepts but misses nuanced intuition of human experts
Scaling Compute on ContextContext
critical challenge to imbue AI with deeper understanding of specific domains
From the article 4 mentionsHe believes this recursive self-improvement is crucial for achieving the desired scaling of compute on context, leading to models that can continuously refine their internal representations and provide increasingly valuable assistance.
Engram's GoalCore
startup aims to bridge the gap between broad knowledge and deep personal context
From the article 4 mentionsThis gap, Morris explained, is precisely what Engram aims to bridge.
Beyond Public DataContext
moving past general information to specialized experience or proprietary data
From the articleHowever, he stressed that this scaling has historically been confined to public data.
Deeper Model UnderstandingEffect
AI gains specialized knowledge and intuition from specific user contexts
From the articleHe articulated the problem of scaling compute on context, noting that while many terms exist for this area, including continual learning, neural memory, and amortized inference, the core goal is to imbue AI with a deeper understanding of specific domains and personal information.
Personalized AI CapabilitiesEffect
achieving deeper model understanding and personalized capabilities for users
From the articleThe most pressing issue, however, is the inability of current models to learn from private, personalized data, such as a user's emails, personal preferences, or company-specific information.
Contents(3)

Jack Morris, a researcher at the recently launched startup Engram, delivered a thought-provoking presentation on the critical challenge of "scaling compute on context." He highlighted a fundamental limitation in current AI: while models possess incredible breadth of knowledge from vast public datasets, they often lack the depth and personalized understanding that comes from specialized experience or proprietary data.

Engram's Jack Morris on Scaling AI Compute on Context - AI Engineer
Engram's Jack Morris on Scaling AI Compute on Context, AI Engineer

Morris began by drawing a parallel to the famed mathematician Terence Tao, who notes that AI can connect disparate mathematical concepts due to its extensive reading but may miss the nuanced intuition a human expert develops over years of focused practice. This gap, Morris explained, is precisely what Engram aims to bridge. He articulated the problem of scaling compute on context, noting that while many terms exist for this area, including continual learning, neural memory, and amortized inference, the core goal is to imbue AI with a deeper understanding of specific domains and personal information.

The Limits of Public Data

Morris pointed out that even the most advanced large language models have a knowledge cutoff, meaning they are unaware of events or information that occurred after their training data was collected. He also highlighted that models struggle with acquiring knowledge that is rare in training datasets, using AMD GPU kernel optimization as an example. The most pressing issue, however, is the inability of current models to learn from private, personalized data, such as a user's emails, personal preferences, or company-specific information. This is because models like ChatGPT are trained on publicly available data, which by definition excludes such private details.

The Three Axes of Scaling and the Missing Piece

Morris outlined the three primary axes for scaling AI models: increasing the amount of data, extending training time or compute, and growing model capacity. He acknowledged that scaling along these axes has driven significant progress, making models proficient in areas like coding and mathematics based on public repositories and textbooks. However, he stressed that this scaling has historically been confined to public data. The missing element, he argued, is applying this scaling power to private, personal data.

The Path Forward: Compute on Context

The core challenge, Morris posited, lies in the "fixed data budget" when dealing with private datasets. The goal is to scale compute on this context to create better models that truly "know" the data. He briefly touched upon several approaches, including naive training (which he found to be largely ineffective due to generalization issues), data compaction, and synthetic data generation. He also referenced techniques like on-policy distillation and self-study, noting their promise but also their inherent limitations.

Morris then introduced the concept of "self-improvement" in AI, drawing parallels to systems like AlphaGo that generate increasingly difficult training problems as they improve. He believes this recursive self-improvement is crucial for achieving the desired scaling of compute on context, leading to models that can continuously refine their internal representations and provide increasingly valuable assistance. He concluded by inviting interested individuals to explore career opportunities at Engram.

Mentioned in this story

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

TopicsJack MorrisEngramAI ResearchContinual LearningLarge Language ModelsMachine LearningArtificial Intelligence

StartupHub.ai Staff

Written by

StartupHub.ai StaffEditorial team

The staff writers of StartupHub.ai, ranging from investment analysts to avid AI tool users, early adopters and critical enthusiasts. Backgrounds span engineering, business and the arts. We hold every piece to rigorous standards of research and review.

Daniel Singer

Reviewed by

Daniel Singer is an AI expert who has been writing about, covering and building AI technology since 2018.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.