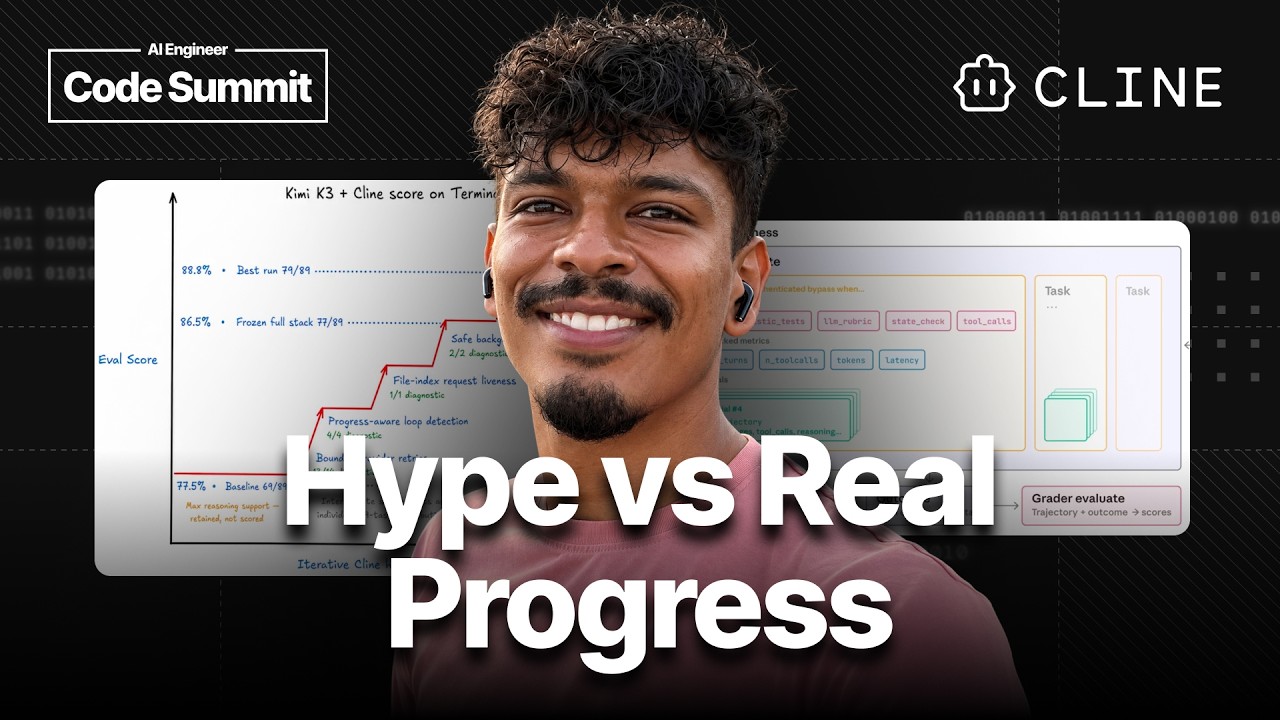
Ara Khan, engineer at Cline, demoed a local harness that rewrites itself to lift Terminal-Bench 2.1 scores, in a session carried by AI Engineer. It started at 77.5% with Kimi K3 against 85% claimed in its release paper, Khan said.
The gap was the job.
Khan said GPT-5.6 acted as meta agent for 17 hours while Kimi K3 ran scoring, starting from 27% and testing across 89 parallel containers. The system bucketed failures and patched loop detection, background process handling and file indexing without human edits.
Khan cited an OpenAI post where GPT-5.6 rewrote production kernels for a 20% end-to-end serving cost cut and 15% higher token throughput. Those figures lack public eval details and hardware baselines, so savings may not transfer outside OpenAI stacks.
Cline also ships a desktop application for coding and session management, which frames the harness work as backend tuning rather than user feature. A fixed harness version with rerun scores would change the read on generality.
Do self-made gains from 27% hold on new tasks, or do they fade when the next base model ships?