#Terminal-Bench
8 articles with this tag
Cline Engineer Shows Agents That Fix Themselves
Cline's Ara Khan demoed a harness that rewrites itself after a 77.5% vs 85% gap, plus a 17-hour run from 27%.
DeepSeek V4.1 Flash is cheap, fast and visual
DeepSeek V4.1 Flash 1017 brings native vision and CED architecture with 8B/16B active parameters and 1M context at $0.10/$0.50.
Z.ai pushes GLM-5.2 open weights near frontier
Zhipu pitches GLM-5.2 as open weights near Opus 4.7 to 4.8 on agentic benchmarks, pushing on-premise and fine-tune adoption.
GPT-6 Astra is powerful, pricey and still gated
OpenAI's GPT-6 Astra promises best-in-class computer use at $10/$50 per million tokens, but long-context surcharges and gated enterprise controls temper the hype.
AI Coding Benchmark Scores Skewed by Infrastructure
Infrastructure configuration, not just AI model prowess, can significantly skew benchmark results, complicating deployment decisions.

AI Agents Leveled Up by Harness Engineering
LangChain's harness engineering approach dramatically improved an AI coding agent's performance by refining its surrounding system, not the core model.
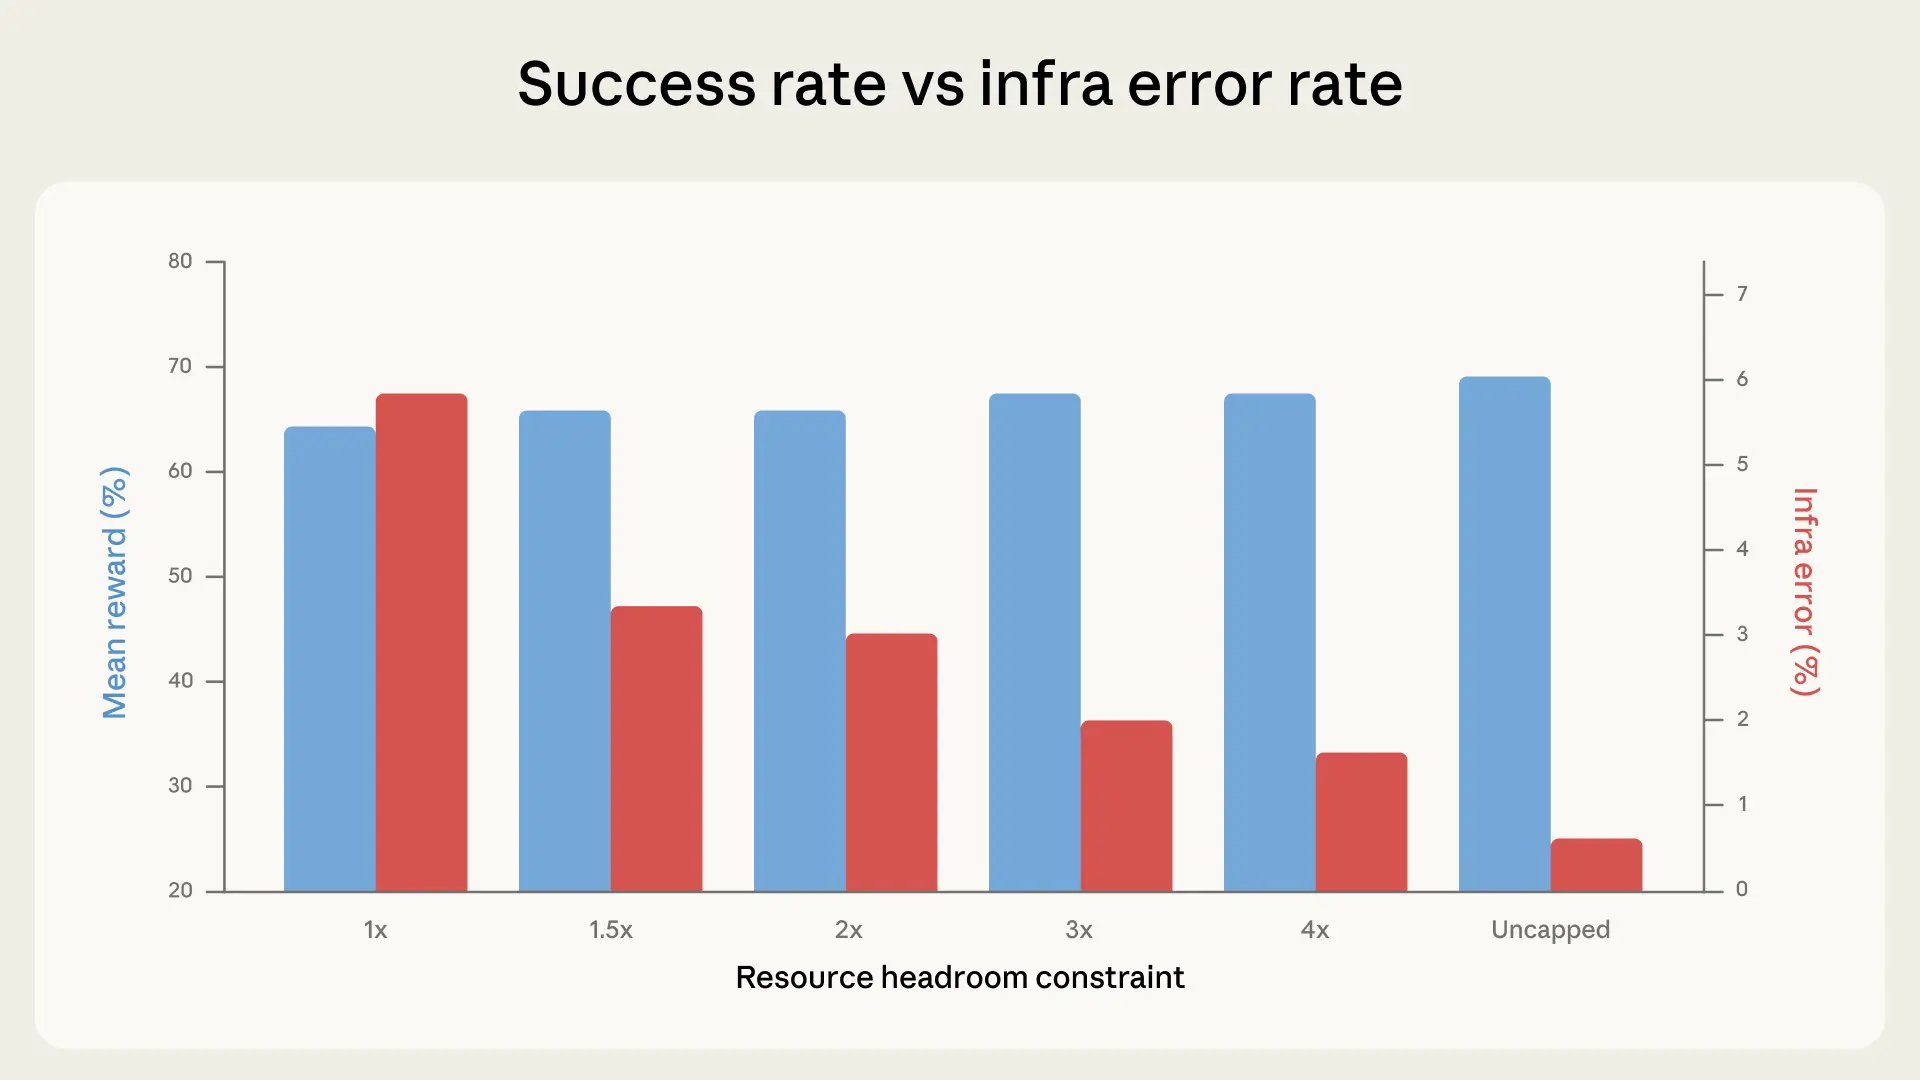
AI Coding Tests Flawed by Infrastructure Noise
The infrastructure powering AI coding tests can significantly inflate or deflate model scores, potentially masking true capabilities and misleading deployment decisions.