
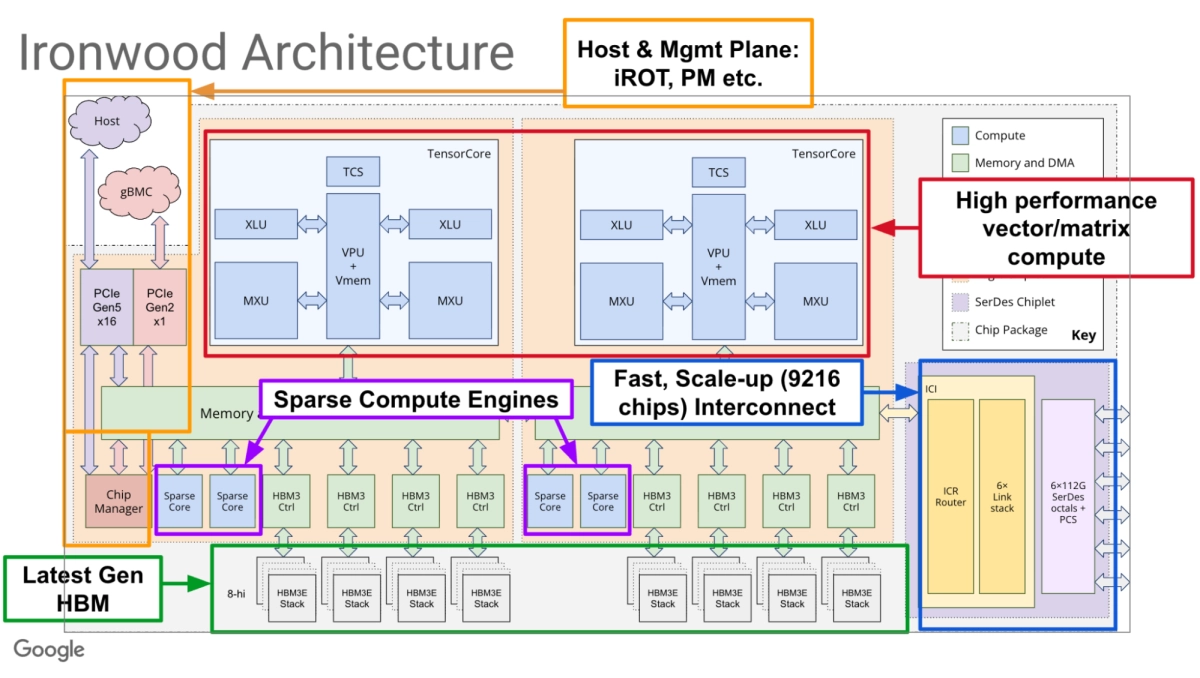
As AI models balloon in complexity and parameter count, the era of general-purpose computing for cutting-edge machine learning is rapidly fading. Google is doubling down on specialized, co-designed hardware and software with its latest Tensor Processing Unit (TPU), Ironwood. Detailed by Distinguished Engineer Diwakar Gupta and Principal Engineer Manoj Krishnan, the Ironwood AI stack isn't just a new chip; it's a holistic supercomputing architecture built from the silicon up to power models like Gemini and Nano Banana.
The core philosophy behind Ironwood is treating an entire TPU pod as a single, cohesive supercomputer, not merely a collection of accelerators. This starts with custom interconnects enabling massive-scale Remote Direct Memory Access (RDMA), allowing thousands of chips to exchange data directly at high bandwidth and low latency. Each Ironwood chip packs 192 GiB of HBM3E, contributing to a staggering 1.77 PB of directly accessible HBM capacity across a superpod. The hardware itself is an Application-Specific Integrated Circuit (ASIC), featuring a dense Matrix Multiply Unit (MXU) for core operations, a Vector Processing Unit (VPU) for element-wise tasks, and SparseCores for embedding lookups, collectively delivering 42.5 Exaflops of FP8 compute.
Scaling this power is equally intricate. Ironwood chips form "cubes" via a 3D Torus Inter-Chip Interconnect (ICI), then connect into larger "pods" and "superpods" using a dynamic Optical Circuit Switch (OCS) network. This OCS isn't just for scale; it's a critical fault-tolerance mechanism, dynamically reconfiguring to bypass unhealthy units. Google claims Ironwood delivers twice the performance per watt compared to its predecessor, Trillium, and is nearly 30 times more power-efficient than its first Cloud TPU from 2018.
The Software Glue: JAX, PyTorch, and Custom Kernels
Hardware is only half the story. The Ironwood AI stack is explicitly targeted by the Accelerated Linear Algebra (XLA) compiler, which provides broad "out of the box" optimization by fusing operations. For developers, Google offers dual-pronged support: the JAX ecosystem for maximum performance and flexibility, and a new, native PyTorch experience. The PyTorch integration aims for a familiar eager mode, leveraging `torch.distributed` and `torch.compile` with XLA as its backend, minimizing code changes for existing PyTorch users.
Beyond general optimization, cutting-edge research often demands custom algorithms. This is where Pallas, a JAX-native kernel programming language embedded directly in Python, comes in. Pallas allows developers to explicitly manage the accelerator's memory hierarchy, defining how data moves from HBM to on-chip SRAM, with the Mosaic compiler backend translating these definitions into optimized TPU machine code. This unified, Python-first approach for custom kernels is a significant differentiator, avoiding the fragmented workflows often seen on other platforms.
The daily brief
Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.
Join 64,000 other subscribers.
From pre-training massive Mixture-of-Experts models with MaxText to fine-tuning with complex Reinforcement Learning workflows, and serving high-throughput inference via vLLM TPU, the Ironwood AI stack is designed to optimize every phase of the AI lifecycle. This deep co-design, from silicon to software, positions Ironwood as a critical piece of infrastructure for the next generation of AI development, making supercomputing-scale AI more accessible and efficient for a broader developer base.




