

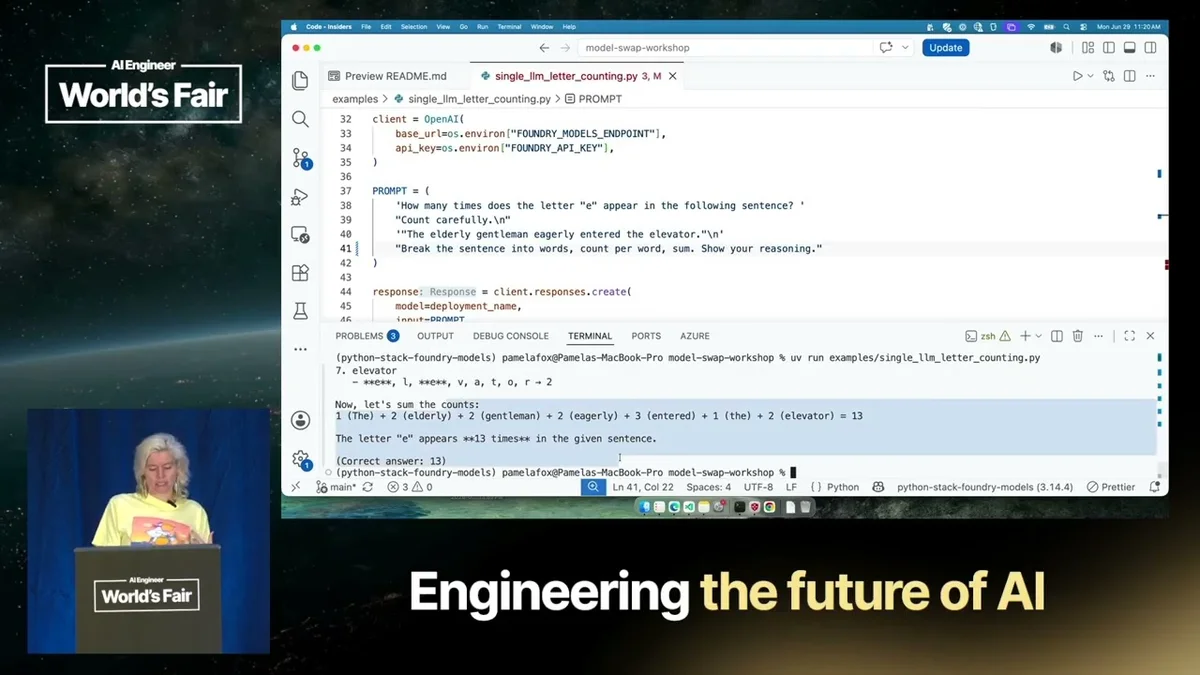
Swap test shows GPT-5.5 and Kimi ace count

AI Engineer swapped GPT-5.5, Kimi K2.6, DeepSeek V4 and Mistral Large 3; only two passed a 13-E test, grounding and vision split harder.

Workshop presenter comparing four AI models on screen
Live model swap workshop· AI Engineer

AI Engineer pitted GPT-5.5 and three challengers against a 13-E counting trap and only two cleared it on the first pass according to the workshop.
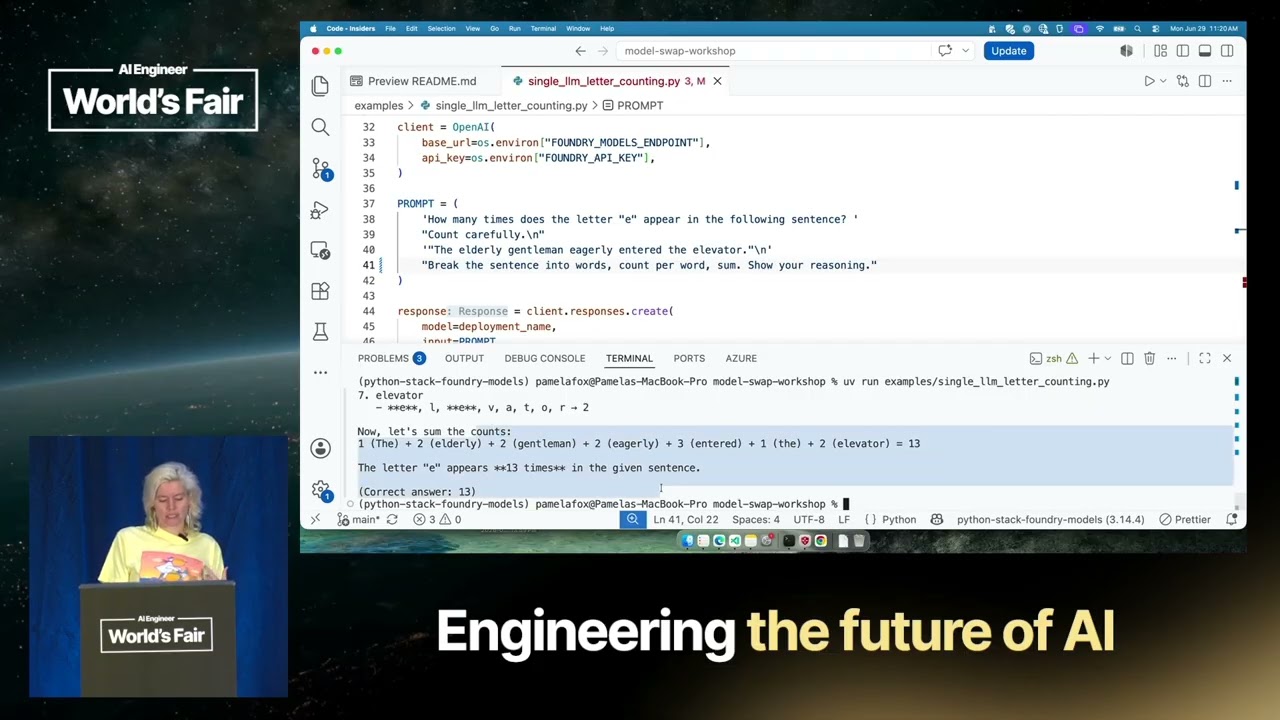
Swap test shows GPT-5.5 and Kimi ace count - AI Engineer
Swap test shows GPT-5.5 and Kimi ace count, AI Engineer

The host ran the four models on a shared Microsoft Foundry project with env-based routing and warned the token capacity could trigger 429 rate-limit errors during the live swap, so alternative deployments were staged and colleague Cedric was on hand to troubleshoot.

On RAG grounding with a carpenter-bee-only corpus, GPT-5.5 correctly said the sources lacked honey-bee nest details, DeepSeek V4 Flash did the same, and Mistral Large 3 answered from weights and still leaked honey-bee details after a stricter cite-or-say-no-source prompt according to AI Engineer.

For multimodal images GPT-5.5 and Kimi K2.6 correctly called the horned animal an aurochs not a unicorn, identified crocodiles by snout, and found the 58-cent cheapest plant, while Mistral Large 3 mislabeled the crocodiles as alligators and picked a 2 dollars 30 cents plant and DeepSeek V4 Flash was excluded as text-only according to the workshop.

Tool calling widened the gap as GPT-5.5 produced clean calendar-event arguments and solved a shop total in one calculator call, while DeepSeek and Mistral added the requester as an attendee or malformed the location, and price matters here because DeepSeek Flash drops from 0 point 30 dollars to 0 point 006 dollars per million tokens on a cache hit at peak rates per Layer3Labs, a cost axis the demos did not benchmark.

The workshop proves prompt engineering can rescue weaker models but its single-run anecdotes do not show latency, price per task or repeatability, a controlled eval with error bars would change the read, and the open question is whether teams should pay for precision or prompt around it.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.