
Artificial Intelligence

Hugging Face Scales Infrastructure to Serve 3 Million Models

Arek Borucki from Hugging Face discusses how the platform scaled its infrastructure to serve millions of AI models and users, detailing architectural decisions and database optimizations.

StartupHub.ai Staff

By StartupHub.ai Staff, reviewed by Daniel Singer, Editor

4 min read

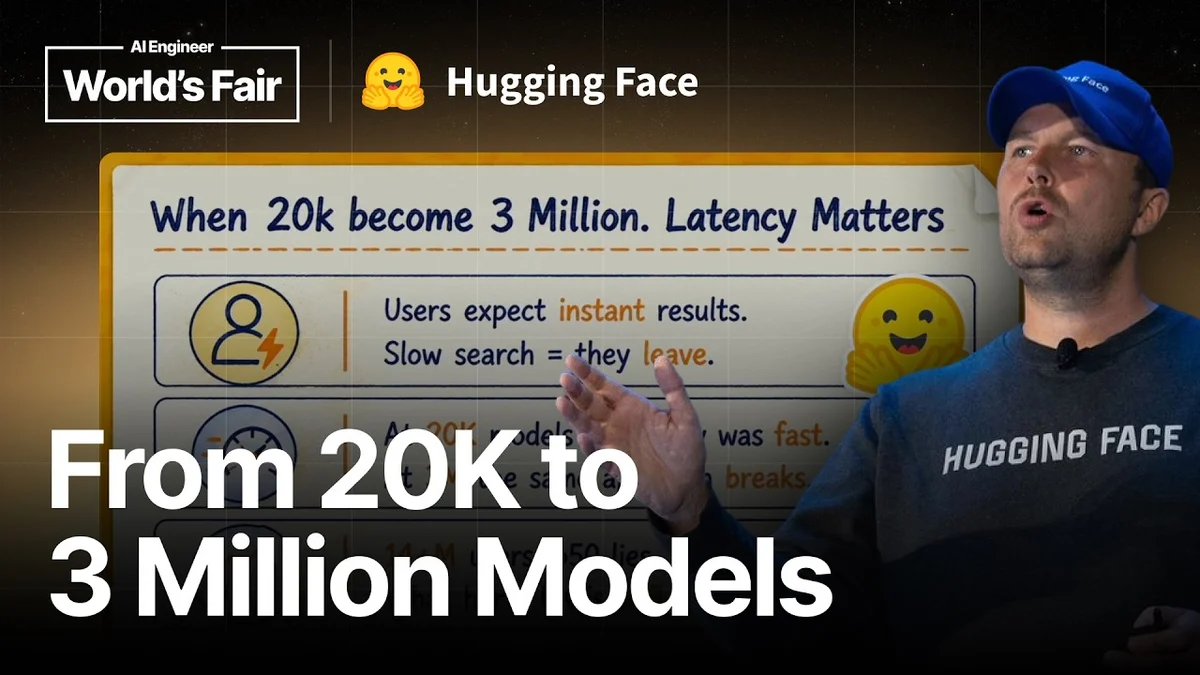
Arek Borucki from Hugging Face presenting on scaling the AI model hub.
Credit: AI Engineer
Visual TL;DR
Exponential Model GrowthDriver
3 million models now hosted, a 150x increase from a few years ago
From the article 3 mentionsHugging Face has experienced exponential growth, now boasting over 14 million users, 3 million public models, and 1 million datasets, with more than 30% of Fortune 500 companies utilizing the platform.
Serve Millions UsersDriver
scaling infrastructure to support 14 million users and 50,000 organizations globally
From the article 2 mentionsMongoDB Atlas serves as the source of truth for all metadata, including user repositories, models, datasets, and billing information.
Architectural DecisionsCore
core infrastructure built on specific architectural choices for high scalability
Leverage MongoDBCore
optimizing database performance and scalability using MongoDB for model metadata
From the article 5 mentionsCrucially, MongoDB does not store the actual model artifacts or tokenizer files, which are kept separately in cloud object storage like AWS S3.
Kubernetes & BeyondCore
scaling infrastructure with Kubernetes for container orchestration and resource management
From the article 3 mentionsThe core of Hugging Face's infrastructure runs on Kubernetes, utilizing Horizontal Pod Autoscaler (HPA) to automatically adjust the number of pods based on CPU and memory utilization.
Optimized SearchEffect
efficiently searching across 3 million models for developers to discover resources
From the article 6 mentionsTo address this, Hugging Face implemented several strategies: pre-computing tokens at insert time, using a denormalized collection optimized for reads, and leveraging MongoDB's Atlas Search, which is powered by Apache Lucene.
Robust Scalable PlatformOutcome
Hugging Face provides a robust and scalable platform for AI development
From the articleThis rapid expansion, fueled by major model releases like Llama and DeepSeek, necessitates a robust and scalable infrastructure.
Contents(6)

In a presentation at the AI Engineer World's Fair, Arek Borucki, ML Platform and Database Engineer at Hugging Face, detailed the infrastructure scaling challenges and solutions behind serving millions of AI models to developers globally. Hugging Face has experienced exponential growth, now boasting over 14 million users, 3 million public models, and 1 million datasets, with more than 30% of Fortune 500 companies utilizing the platform.

Hugging Face Scales Infrastructure to Serve 3 Million Models - AI Engineer
Hugging Face Scales Infrastructure to Serve 3 Million Models, AI Engineer

The Scale of Hugging Face

Borucki highlighted the dramatic increase in models hosted on the Hugging Face hub, from 20,000 a few years ago to 3 million today, representing a 150x growth. This rapid expansion, fueled by major model releases like Llama and DeepSeek, necessitates a robust and scalable infrastructure. The platform also manages over 1 million datasets and supports 50,000 organizations, demonstrating its central role in the AI development community.

Architectural Decisions for Scalability

The core of Hugging Face's infrastructure runs on Kubernetes, utilizing Horizontal Pod Autoscaler (HPA) to automatically adjust the number of pods based on CPU and memory utilization. This ensures the hub remains healthy during traffic spikes without manual intervention. MongoDB Atlas serves as the source of truth for all metadata, including user repositories, models, datasets, and billing information. Crucially, MongoDB does not store the actual model artifacts or tokenizer files, which are kept separately in cloud object storage like AWS S3. This separation allows for independent scaling of metadata, binary storage, and compute resources.

Optimizing Search for 3 Million Models

With the massive growth in models, the need for efficient search became paramount. Borucki explained that at 20,000 models, simple query methods sufficed, but at 3 million models, this approach breaks. Users expect instant search results, and slow performance leads to churn. To address this, Hugging Face implemented several strategies: pre-computing tokens at insert time, using a denormalized collection optimized for reads, and leveraging MongoDB's Atlas Search, which is powered by Apache Lucene. This allows for instant autocomplete functionality and faster matching of models.

Leveraging MongoDB for Performance

Borucki elaborated on the specific techniques used within MongoDB. A dedicated, denormalized read collection stores pre-computed search tokens in an array within each model document. This allows queries to efficiently search these tokens. Previously, the platform used a regex operator, which proved to be a bottleneck as the dataset grew. The switch to Atlas Search, utilizing the '$search' operator in aggregation pipelines, has resolved latency issues. The infrastructure also employs a seven-node MongoDB cluster with multiple machines to distribute read load and prevent single-node bottlenecks. A hidden analytic node is used for heavy queries and reporting, isolated from production traffic.

Scaling the Infrastructure with Kubernetes and Beyond

The Hugging Face hub's Kubernetes deployment can scale horizontally from 10 to 500 pods using HPA. To handle situations where HPA needs to add more pods but no free nodes are available, a second layer of scaling is implemented using Cast AI for node autoscaling. This ensures that infrastructure can be provisioned on demand. The team is also migrating from HPA to Kubernetes Event-Driven Autoscaling (KEDA), which allows scaling based on real application metrics like requests per second or event loop utilization, rather than just CPU and memory.

The Future of Scaling

Borucki concluded by emphasizing that while current scaling strategies are effective, the next step for handling even greater growth will involve database sharding. Sharding allows for horizontal scaling by dividing data into smaller pieces, each managed by its own replica set. This approach will scale CPU, memory, storage, reads, and writes horizontally, ensuring the continued health and performance of the Hugging Face hub as it grows.

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

TopicsArek BoruckiHugging FaceKubernetesMongoDBAtlas SearchApache LuceneKEDAAI

StartupHub.ai Staff

Written by

StartupHub.ai StaffEditorial team

The staff writers of StartupHub.ai, ranging from investment analysts to avid AI tool users, early adopters and critical enthusiasts. Backgrounds span engineering, business and the arts. We hold every piece to rigorous standards of research and review.

Daniel Singer

Reviewed by

Daniel Singer is an AI expert who has been writing about, covering and building AI technology since 2018.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

