


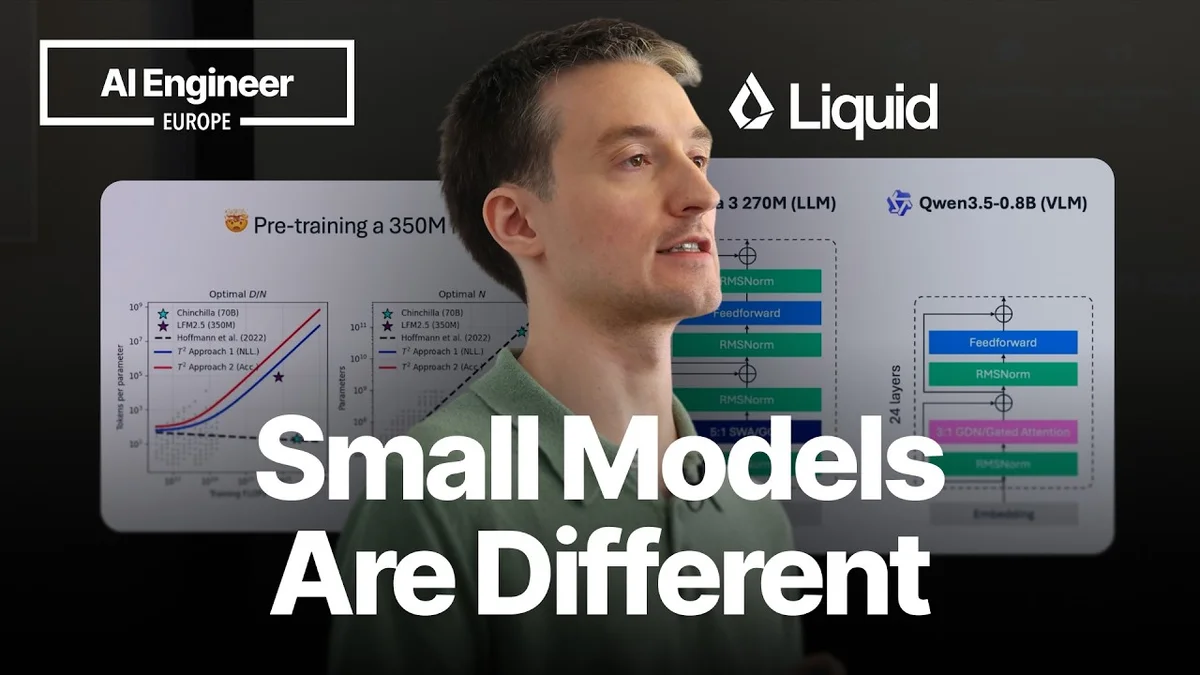
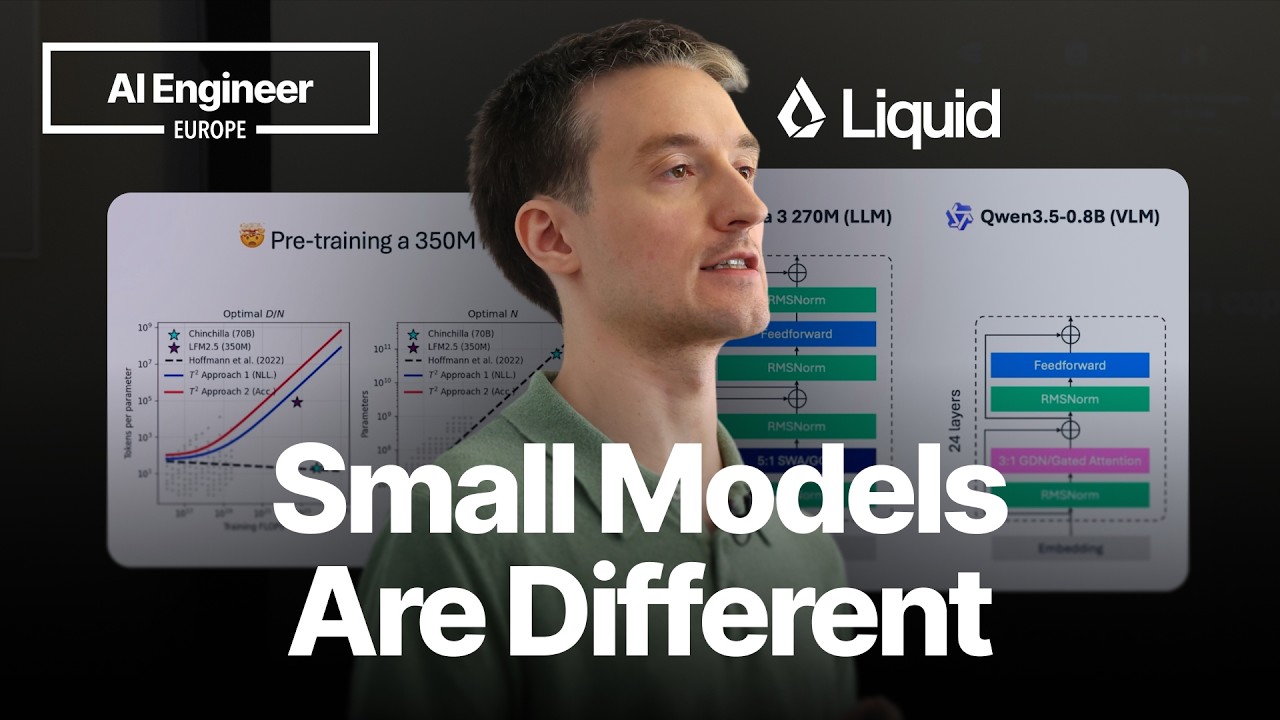
Maxime Labonne, head of pre-training at Liquid AI, recently shared insights into the development and deployment of small AI models, emphasizing their unique characteristics and the challenges they present. In his presentation, titled "Everything I Learned Training Frontier Small Models," Labonne detailed how these models, ranging from 350 million to 24 billion parameters, are optimized for edge AI applications, focusing on text, vision, and audio processing.
Understanding Edge Model Characteristics
Labonne highlighted three key characteristics that define edge models. Firstly, they are memory-bound, typically operating with less than 3 billion parameters, making them suitable for resource-constrained environments like smartphones and cars. Secondly, these models are task-specific, designed to excel at a particular function rather than general-purpose tasks like large language models such as ChatGPT. This specialization allows them to perform tasks like summarization or reasoning very effectively within their defined scope. Thirdly, edge models are latency-sensitive, requiring fast inference throughput to deliver real-time responses.
A crucial point Labonne emphasized is that edge models are not merely scaled-down versions of larger models. They possess unique challenges and require tailored approaches. For instance, the architecture of models like Google's Gemma 3 (270M LLM) and Qwen 3.5 (0.8B VLM) showcases a hybrid approach with features like sliding window attention and gated attention mechanisms. However, the significant portion of parameters dedicated to embedding layers in Gemma 3 (63%) and Qwen 3.5 (29%) indicates potential inefficiencies, as these layers do not contribute as directly to reasoning or knowledge capacity.
Architectural Innovations for Efficiency
Labonne discussed the LFM2.5 architecture, which incorporates short convolutions and gated convolutions, offering a more efficient parameter distribution. This architecture demonstrated better performance and reduced memory usage compared to other models. The team at Liquid AI conducted on-device profiling to validate these architectural choices, testing models on hardware like the AMD Ryzen AI Max 395 and the Samsung Galaxy S25 Ultra. The results showed that the short convolution approach significantly boosted speed and reduced memory footprint, particularly crucial for latency-sensitive applications.
The Importance of Pre-training and Fine-tuning
The presentation also touched upon the training methodology, which involves pre-training on vast datasets (28 trillion tokens for LFM2.5) followed by supervised fine-tuning, preference alignment, and reinforcement learning. Labonne referenced research suggesting that pre-training small models on more tokens, even beyond current optimal scaling laws, can yield better performance. This is particularly advantageous given the lower cost and computational resources required for training smaller models compared to their larger counterparts.