

The quest for unprecedented speed in artificial intelligence has led Cerebras Systems to construct what it proudly proclaims as the world's fastest AI infrastructure, recently unveiled in Oklahoma. This monumental achievement, delivering an astonishing 44 ExaFLOPS of new compute power to customers, is not merely about raw processing might but represents a radical rethinking of semiconductor design, cooling, and power delivery that challenges decades of conventional wisdom in high-performance computing.
Matthew Berman of Forward Future recently toured this cutting-edge facility and spoke with Andrew Feldman, Co-Founder and CEO of Cerebras, and Billy Wooten, COO of Scale Data Centers, about the strategic decisions and technological breakthroughs that underpin this audacious endeavor. The conversation delved into everything from the surprising choice of location to the intricate engineering required to push the boundaries of AI acceleration.
Cerebras’ decision to build its flagship data center in Oklahoma City was a calculated one, moving beyond the traditional tech hubs. Feldman cited a confluence of factors: "reasonable labor costs," ample space for "build and expand," and crucially, "reasonably priced power." Beyond economics, the facility's design itself reflects its geographical reality. Constructed with reinforced concrete and engineered for tornado resilience, it ensures operational continuity in a region prone to severe weather, a critical consideration that even impacts the "cost of insurance," as Feldman noted. This foresight in physical infrastructure underscores a holistic approach to reliability.
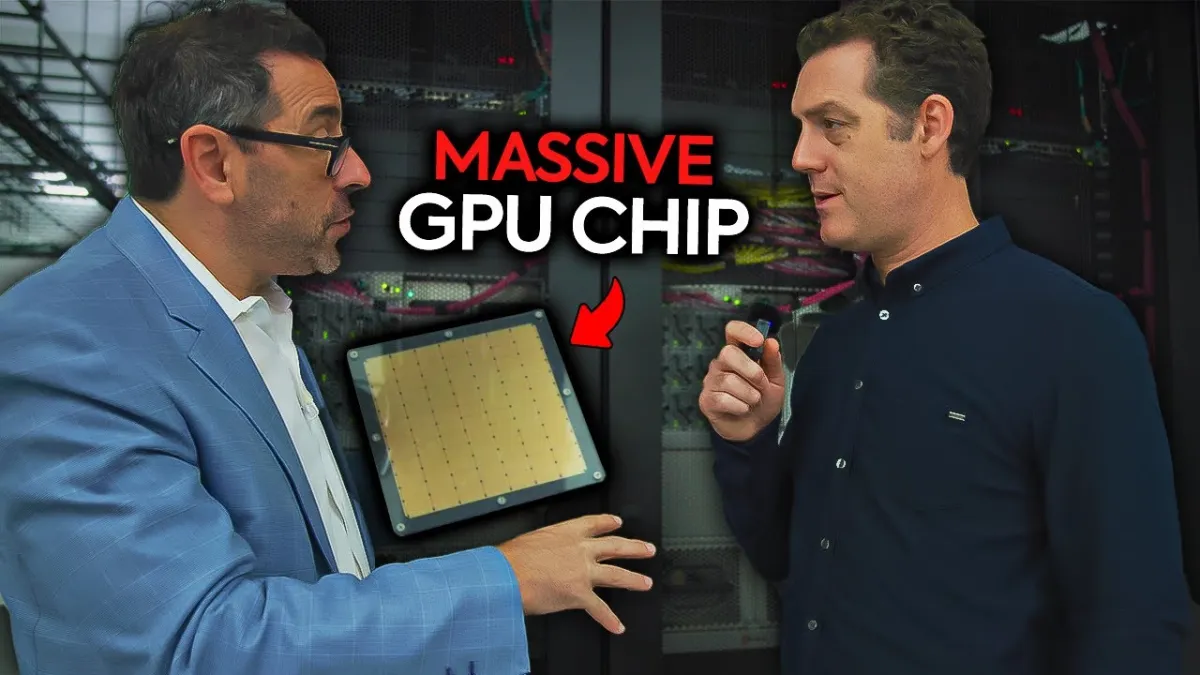
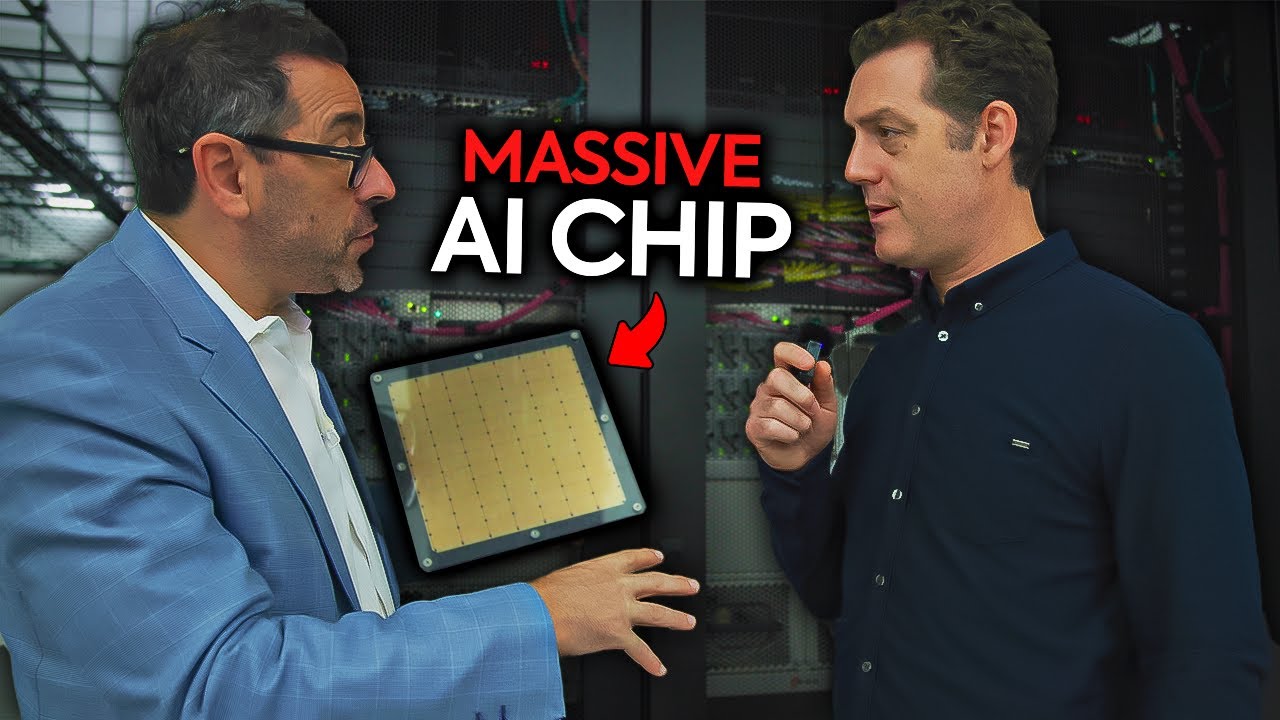
At the heart of Cerebras' speed advantage lies its groundbreaking Wafer-Scale Engine (WSE). Feldman dramatically illustrated its scale by presenting a chip the size of a dinner plate, measuring 46,250 square millimeters. In stark contrast, a traditional chip, considered large at 750 square millimeters, is roughly the size of a postage stamp. This immense scale allows Cerebras to integrate an entire wafer of processors into a single, monolithic chip, eliminating the latency-inducing communication between discrete chips that plagues conventional GPU-based systems.
The profound impact of this design is in memory access. "We have all our memory on the chip," Feldman explained, highlighting the critical difference. Traditional GPUs suffer from "off-chip latency" when data must travel between the processor and external memory. By keeping memory directly on the wafer, Cerebras achieves a staggering "2.5 thousand times faster at getting to data and then using it," a performance leap that fundamentally redefines AI inference capabilities.