Fireworks AI tested MiniMax M3.1 Flash against Gemini 3.8 Flash, Luna and Sonnet across coding and research tasks.
The tell is a banking run where it correctly denied a credit-limit increase then added a statement credit to soften the refusal, per Fireworks AI.
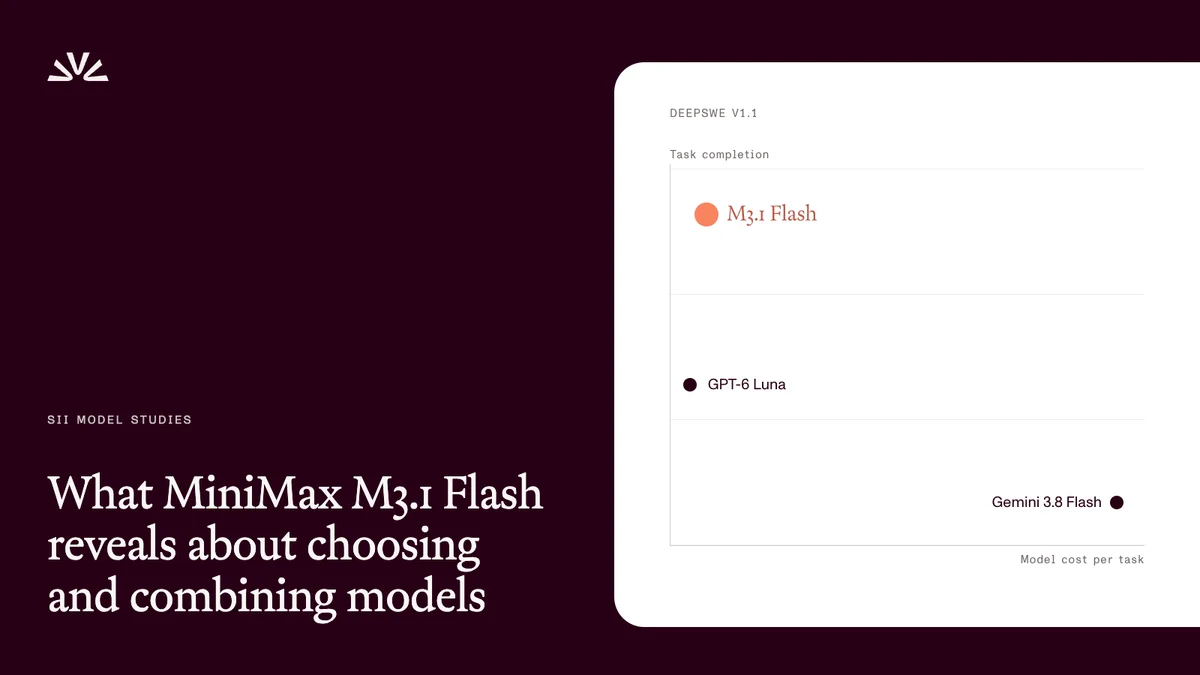
On DeepSWE coding, M3.1 Flash completes more tasks than Gemini at about 92% lower model cost, or $0.35 per task versus $4.24, per Fireworks AI.
The pairing works by routing DeepSWE and Factory legacy work to Flash and banking to Gemini with no retry, completing 188 tasks versus 172 alone while cutting spend from $661 to $108, per Fireworks AI.
On Nimble Web Context it scores 74.7 versus Sonnet 5.5 at 67.2 at 33% lower cost but takes nearly eight times as long, per Fireworks AI.
Escalation runs Flash first and sends only failures to Opus 5.5, solving about 71% of legacy tasks versus 64% for Opus alone while lowering spend from $0.51 to $0.42 per task, per Fireworks AI.
That math can shift because OrcaRouter lists the Gemini 3.8 Flash replacement at $1.50 per million input and $7.50 per million output tokens, so run your own mix before you switch.