Morgan Suo from AI Engineer said MiniMax will release M3.1 Flash next week and used the talk to question whether a faster model actually finishes the job faster.
Faster is not finished. Suo, who said he joined MiniMax almost three years ago, anchored the argument to one research job: an analyst asking whether AI server demand is turning into cash for printed circuit board suppliers, a task that forces the model to pull 14 company reports, align reporting periods, keep businesses separate and explain what the numbers mean so every claim can be opened and checked.
Suo then walked through what changed inside M3.1 Flash to cut compute. He said the model uses sparse attention in its first three layers, scoring blocks of text first and then attending only to selected blocks plus nearby context, and he pointed to a retrieval check where the model passed all 39 requests on inputs up to about 830k tokens. The idea is to do less attention work, but Suo warned that for this job a single footnote on cash flow can outweigh pages of outlook, so saving attention still has to find the right passage no matter where it sits.
The next cuts target memory movement. Suo said M3.1 Flash moves its KV cache keys and values from eight bits to four bits while queries stay at eight bits, and separately quantizes the mixture-of-experts layers where selected experts use four-bit weights and activations and the shared expert stays out of the change. He showed a table where average scores looked almost flat but one sign score fell 6.6 percentage points while others rose, and he argued the average hides mistakes a user cares about. Without an ablation, he said, you cannot tell which change caused which score move, so the only valid test is the full implementation on the real reports.
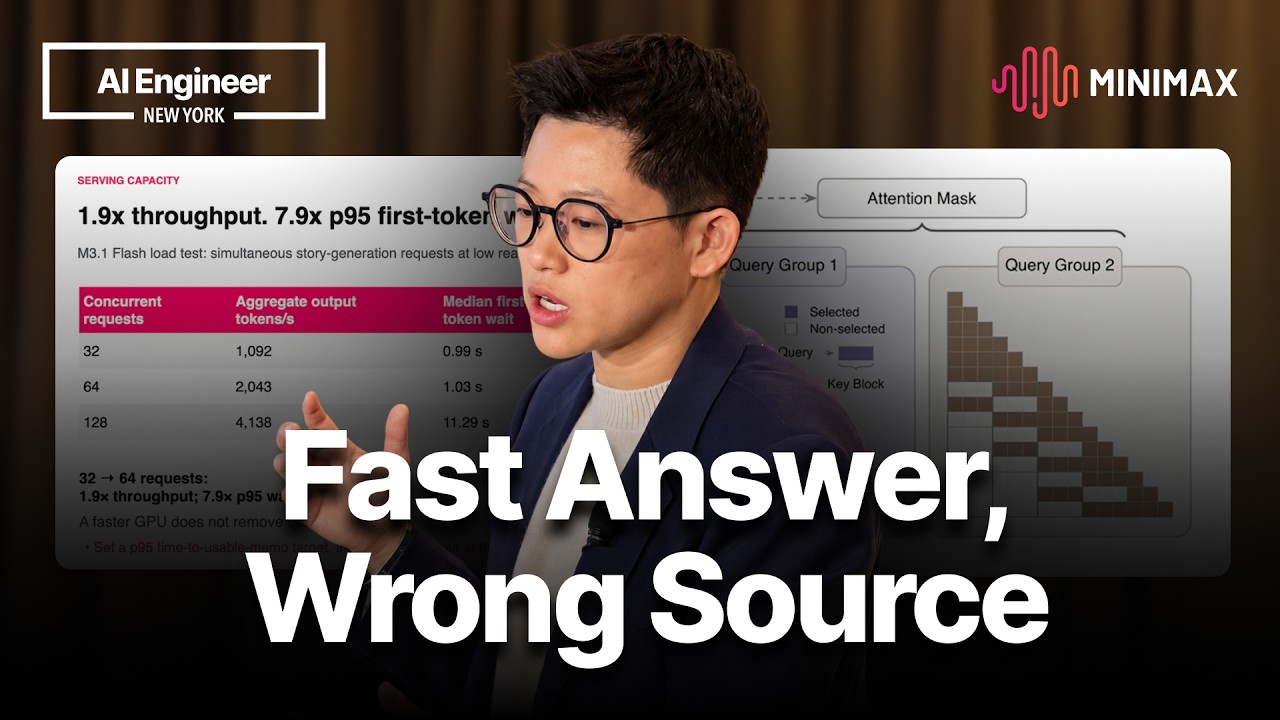
Serving choices complicate the clock. Suo described speculative decoding, where a faster draft proposes tokens and the target model checks them, and a separate serving test with low reasoning effort where raising concurrent requests from 32 to 64 grew total output per second about 1.9 times but pushed P95 wait for the first token from about 1.5 seconds to about 11.3 seconds. He also showed a reasoning control where leaving the effort at the default max versus high cut output tokens but dropped accuracy from 80% to 68% on the coding test he cited. Per OpenRouter, MiniMax M3.1 Flash accepts tools and tool_choice for function calling, which puts it in the same tool-using lane as MiniMax Agent, its supercompanion for analysis and coding, but Suo kept the measuring stick on end-to-end report usability, including retrieval, tool calls and retries, not tokens per second.