AI Research

Google DeepMind Tackles AI Evaluation Challenges

Google DeepMind's Nicholas Kang and Michael Aaron discuss the challenges in current AI evaluation and Kaggle's innovative solutions like Hackathons, Agent Exams, and Game Arena.

Daniel Singer

By Daniel Singer, Editor, StartupHub.ai

4 min read

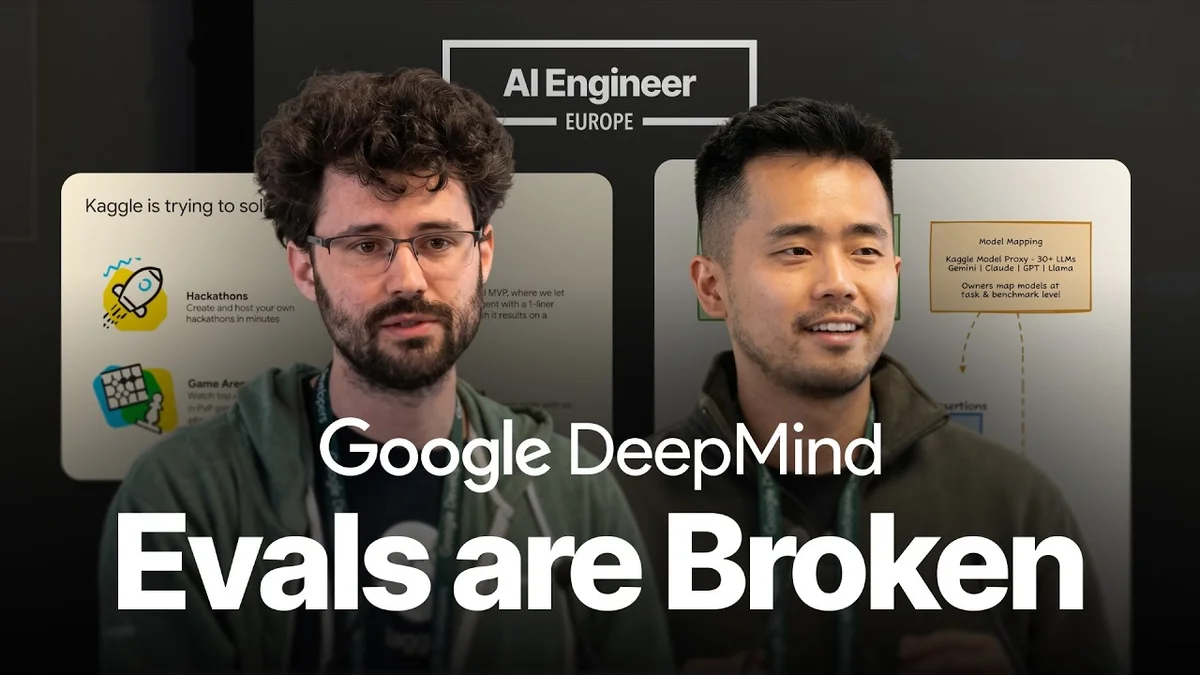
Nicholas Kang and Michael Aaron from Google DeepMind presenting on AI evaluations at scale.
Nicholas Kang and Michael Aaron of Google DeepMind discussing agentic evaluations.Credit: AI Engineer
Visual TL;DR
AI Evaluation ChallengesDriver
rapid AI development outpaced reliable evaluation and comparison
From the article 9+ mentionsNicholas Kang and Michael Aaron from Google DeepMind recently discussed the critical need for robust and scalable AI evaluations, highlighting the current challenges and Kaggle's initiatives to address them.
Fragmented BenchmarksDriver
scattered across GitHub, arXiv, and internal lab servers
From the article 8 mentionsKang and Aaron began by detailing the fragmented nature of current AI evaluations.
Kaggle's SolutionsCore
innovative initiatives to address evaluation challenges
From the article 7 mentionsTo tackle these challenges, Kaggle is actively developing new platforms and initiatives.
Stale LeaderboardsDriver
From the article 2 mentionsA significant issue they highlighted is that once leaderboards are published, they often do not get updated by the original publishers, leading to stale and irrelevant comparisons.
Hackathons, Exams, ArenaContext
specific Kaggle tools for robust AI assessment
Scalable AI EvaluationEffect
enabling robust and comparable AI model assessment
From the article 9 mentionsNicholas Kang and Michael Aaron from Google DeepMind recently discussed the critical need for robust and scalable AI evaluations, highlighting the current challenges and Kaggle's initiatives to address them.
For EverybodyOutcome
making advanced AI evaluation accessible to all
From the articleIn a presentation titled "Agentic Evaluations at Scale, For Everybody," Kang and Aaron outlined how the rapid pace of AI development has outpaced the ability to reliably evaluate and compare different models.
Contents(3)

Nicholas Kang and Michael Aaron from Google DeepMind recently discussed the critical need for robust and scalable AI evaluations, highlighting the current challenges and Kaggle's initiatives to address them. In a presentation titled "Agentic Evaluations at Scale, For Everybody," Kang and Aaron outlined how the rapid pace of AI development has outpaced the ability to reliably evaluate and compare different models.

Google DeepMind Tackles AI Evaluation Challenges - AI Engineer
Google DeepMind Tackles AI Evaluation Challenges, AI Engineer

The Problem with Current AI Evaluations

Kang and Aaron began by detailing the fragmented nature of current AI evaluations. They explained that most benchmarks are scattered across platforms like GitHub repositories, arXiv papers, and internal AI lab servers. This decentralization makes it a time-consuming task for researchers and enthusiasts to keep track of the latest advancements and ensure the reliability of the data. A significant issue they highlighted is that once leaderboards are published, they often do not get updated by the original publishers, leading to stale and irrelevant comparisons.

Furthermore, they pointed out that AI evaluations are not always transparent, accessible, or verifiable. When labs report results, it's often difficult to understand the setup of the benchmarks, the specific configurations used, or what the benchmarks are truly testing. This lack of transparency can lead to ambiguity and make it challenging to reproduce results or trust the reported performance metrics. They also noted instances where different labs might publish conflicting results for the same benchmarks, further complicating the evaluation process.

A third major challenge identified is that most benchmarks are created by AI researchers, who represent a small fraction of the global technical expertise. While AI researchers are crucial for developing cutting-edge models, their specific domain knowledge might not always align with the broader applications of AI. This can lead to benchmarks that are not representative of real-world use cases or that fail to capture the full spectrum of an agent's capabilities.

Kaggle's Solutions: Hackathons, Agent Exams, and Game Arena

To tackle these challenges, Kaggle is actively developing new platforms and initiatives. Kang and Aaron highlighted several key areas:

The daily brief

Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.

Join 64,000 other subscribers.

  • Hackathons: Kaggle is providing a platform to channel the community's energy and expertise into solving specific problems. By setting clear problem statements and providing guardrails, hackathons can inspire innovation and ensure that results are open-sourced for the benefit of everyone. This approach aims to democratize the evaluation process and leverage a wider pool of talent.
  • Standardized Agent Exams (SAEs): Kaggle is introducing SAEs as an experimental feature where users can submit their agents to take a standardized test with a single-line prompt. This provides a quick baseline to see how an agent performs and allows for direct comparison on a leaderboard. The platform is also exploring safety-focused exams and other competitions to extend the utility of SAEs.
  • Game Arena: This is a benchmarking platform where top models from AI labs compete in head-to-head matchups. These competitions run on Kaggle's evaluation infrastructure and allow for a more dynamic assessment of agent capabilities, as seen in games like chess and poker.
  • Benchmarks: Kaggle allows anyone to build, run, and share their own evaluations in an open and verifiable way, fostering transparency and reproducibility.

Kang emphasized the importance of these initiatives, stating, "We want to democratize the process of taking AI evaluations, and give everybody a chance to contribute." He also highlighted the challenges in running these platforms, such as the difficulty in producing clear problem statements and evaluation rubrics, enabling participants to use the right tools, and the need for human expertise in judging. However, the goal is to create a more accessible and reliable system for AI evaluation.

The Path Forward

The presentation concluded with a call to action, inviting the community to contribute to solving these challenges. Kang and Aaron stressed that while inspiration and incentivization are key, ensuring the validity and reproducibility of benchmarks requires ongoing effort and collaboration. By providing open and verifiable platforms, Kaggle aims to accelerate progress in AI safety and development, ensuring that AI benefits all of humanity.

Mentioned in this story

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

TopicsNicholas KangMichael AaronGoogle DeepMindKaggleAI EvaluationAI BenchmarkingArtificial IntelligenceMachine Learning

Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute, free.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.