General Reasoning Founders on Scaling AI Models to Long Horizons

Ross and Chengxi Taylor of General Reasoning discuss Galactica, RLHF, KellyBench, and the infrastructure needed to scale AI models to long horizons.

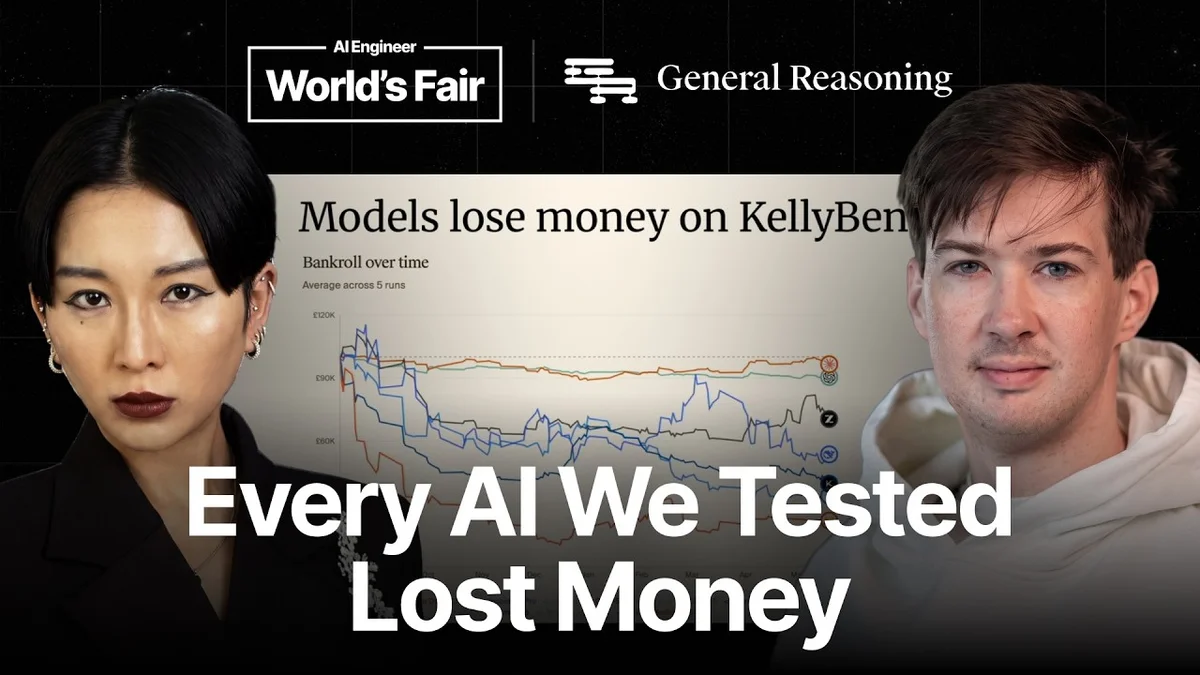
Ross Taylor presenting at AI Engineer World's Fair on scaling AI models to long horizons
General Reasoning founders present technical challenges in long-horizon AI scaling.· AI Engineer
Visual TL;DR
General Reasoning FoundersCore
From the article 6 mentionsAt the AI Engineer World's Fair, Ross Taylor and Chengxi Taylor, co-founders of London-based research lab General Reasoning, delivered a joint keynote on expanding machine intelligence beyond short text generations.
Early Reasoning FailuresDriver
initial reasoning recipes struggled to scale effectively for complex, extended tasks
KellyBenchDriver
today's frontier models fail at real-world strategy, highlighting current limitations
From the articleTo evaluate current frontier models on extended real-world strategy, General Reasoning created KellyBench.
Compute ConstraintsDriver
infrastructure and ecosystem limitations hinder the development of advanced AI models
From the article 4 mentionsChengxi Taylor is the co-founder and president of General Reasoning, focusing on agent environments, credit assignment, and compute optimization for extended reasoning trajectories.
Scaling AI ModelsContext
expanding machine intelligence beyond short text generations to complex, multi-week objectives
From the article 9+ mentionsDrawing from their past research on Meta's Galactica and Llama models, the pair mapped out the algorithmic, environment, and compute infrastructure necessary for scaling AI agents to complex, multi-week objectives.
Galactica LessonDriver
base models alone are insufficient for long-horizon reasoning, needing more than just text
From the article 6 mentionsTaylor noted that the missing ingredient was a pure application of the bitter lesson.
Long Horizon ChallengesDriver
algorithmic, environment, and compute infrastructure needed for scaling AI agents
From the articleTaking over the presentation, Chengxi Taylor defined long horizon tasks not merely as engineering hurdles, but as a long-term mindset required to tackle civilization-scale problems like drug discovery or mathematical proofs.
Future AI AgentsEffect
developing robust AI agents capable of complex, multi-week objectives and real-world strategy
From the article 5 mentionsWithout larger context windows, stronger base models, and massive reinforcement learning compute scaling, agents could not develop emergent backtracking mechanisms.
Contents(6)

At the AI Engineer World's Fair, Ross Taylor and Chengxi Taylor, co-founders of London-based research lab General Reasoning, delivered a joint keynote on expanding machine intelligence beyond short text generations. Drawing from their past research on Meta's Galactica and Llama models, the pair mapped out the algorithmic, environment, and compute infrastructure necessary for scaling AI agents to complex, multi-week objectives.

Who Are Ross Taylor and Chengxi Taylor

Ross Taylor is the CEO of General Reasoning and previously served as the reasoning lead at Meta AI, where he led post-training initiatives for Llama 2 and Llama 3 and spearheaded the Galactica model. His entry into Meta came via the acquisition of Papers With Code in 2019. Chengxi Taylor is the co-founder and president of General Reasoning, focusing on agent environments, credit assignment, and compute optimization for extended reasoning trajectories.

The Lesson of Galactica: Why Base Models Are Not Enough

Ross Taylor reflected on the high-stakes launch of Galactica in mid-November 2022, released just two weeks prior to ChatGPT. While Galactica was a state-of-the-art base model that outperformed Google's PaLM and DeepMind's Chinchilla on scientific and mathematical benchmarks, it lacked a reinforcement learning from human feedback (RLHF) pipeline. Consequently, public user prompts triggered notorious base model hallucinations, such as generating fake research on eating crushed glass.

"A good base model is not enough. RLHF made LLMs products for the first time by crossing the Rubicon from a research toy to something used by billions." - Ross Taylor

Despite its public stumble, Galactica introduced key structural techniques now central to reasoning models. It demonstrated high data efficiency using a curated 105 billion token corpus, formalized multi-epoch training, and introduced internal thinking tokens inside dedicated work tags. This mechanism forced the model to expend inference compute on internal scratchpad steps before emitting an output.

Why Early Reasoning Recipes Failed to Scale

In 2023, Taylor's Meta team built an unpublished internal reasoning model that combined continued pre-training on mathematical corpora with Proximal Policy Optimization (PPO) and verifiable reward models. While the system achieved top scores on the MATH benchmark and surpassed GPT-4 in raw accuracy, it failed to produce the reflective, self-correcting behaviors seen in modern systems like DeepSeek-R1 or OpenAI o1.

Taylor noted that the missing ingredient was a pure application of the bitter lesson. Without larger context windows, stronger base models, and massive reinforcement learning compute scaling, agents could not develop emergent backtracking mechanisms.

The Mindset and Algorithmic Challenges of Long Horizon Reasoning

Taking over the presentation, Chengxi Taylor defined long horizon tasks not merely as engineering hurdles, but as a long-term mindset required to tackle civilization-scale problems like drug discovery or mathematical proofs. She highlighted that historical achievements, such as solving Fermat's Last Theorem, required years of scratchpad iteration equivalent to tens or hundreds of billions of tokens. Current context limits of 1 million tokens force researchers to rethink context management.

General Reasoning utilizes context compaction policies trained via reinforcement learning alongside task execution. However, long trajectories introduce severe optimization barriers, including high gradient variance, sparse rewards, and unstable credit assignment across variable rollout lengths. To mitigate these issues, the team employs value critics that estimate intermediate reward expectations before an episode terminates.

KellyBench: Why Today's Frontier Models Fail at Real-World Strategy

To evaluate current frontier models on extended real-world strategy, General Reasoning created KellyBench. The benchmark tasks AI agents with building machine learning models to trade in English Premier League sports betting markets over a full one-year season, initialized with a $100,000 bankroll.

The results were stark: every major frontier model lost money over the simulated year. Chengxi Taylor attributed this performance gap to an industry-wide overemphasis on procedural coding tasks with single clear solutions, leaving models ill-equipped for open-ended, non-deterministic environments involving competing human agents.

Compute Constraints and the Frontier Ecosystem

Managing GPU infrastructure during extended reasoning trajectories presents major bottlenecks. While pipeline reinforcement learning allows models to run inflight weight updates during rollout generation, trajectories lasting days or weeks exceed standard off-policy boundaries. Without bootstrapping via value models, expensive GPU clusters sit idle awaiting rollout completion.

To accelerate multi-step research, General Reasoning released OpenReward, an infrastructure platform offering over 350 RL environments through a unified API endpoint for internal research and external labs.

StartupHub.ai data shows intense market competition across search and reasoning domains, where OpenAI leads with a rating score of 84/100, while tech giants like Alphabet Inc. (NASDAQ:GOOGL) score 73/100. Meanwhile, AI search engine provider You holds a score of 71/100 with $80M in Series A funding, and open-weight model architectures like Llama maintain a score of 52/100 as labs compete to overcome long-horizon context boundaries.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.