
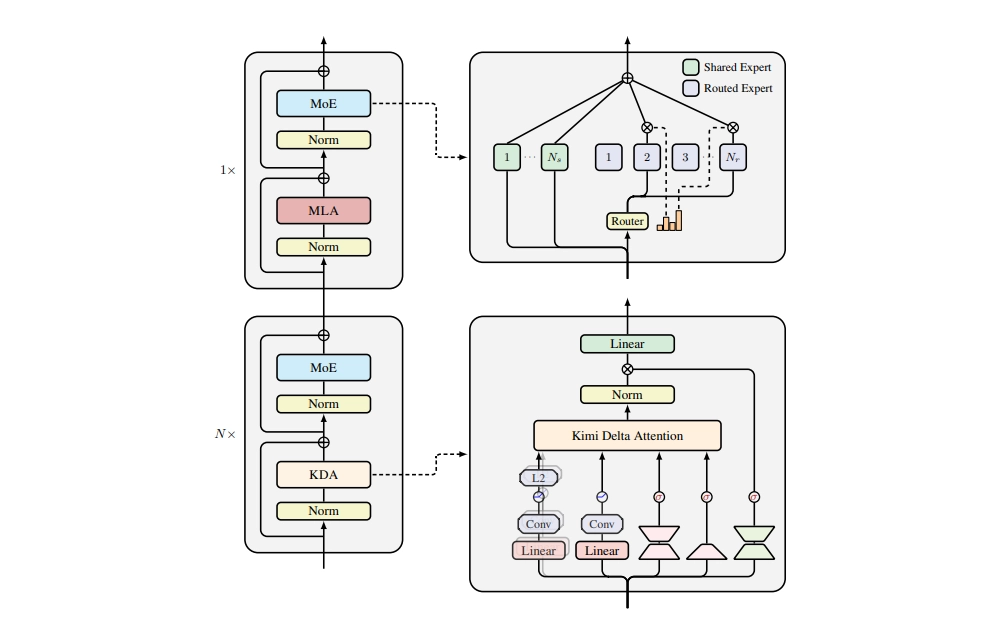
Moonshot AI has released Kimi Linear, a new large language model built on a hybrid attention architecture that it claims is both more efficient and more powerful than traditional transformer models. The open-source release, detailed in a new technical report, is already stirring debate in the AI community about its performance and practicality.
At its core, Kimi Linear uses a mix of attention mechanisms. For every three layers of its novel Kimi Delta Attention (KDA), a type of efficient linear attention, it includes one layer of standard Multi-Head Latent Attention (MLA). This 3:1 hybrid design, according to the Kimi Team, is the key to its success. The company reports that Kimi Linear outperforms comparable full-attention models across short-context, long-context, and reinforcement learning tasks, all while cutting KV cache usage by up to 75% and boosting decoding throughput by up to 6x for million-token contexts.
The Community Weighs In
While the efficiency claims are impressive, the reception has been cautiously optimistic. Users are excited about the potential for linear attention models to bring massive context windows to consumer hardware, but they also point to some immediate hurdles. The model’s architecture is based on Gated DeltaNet, a complex structure that isn’t yet fully implemented or optimized in popular inference frameworks like llama.cpp.
Benchmark scores have also been a point of contention. Some community-generated charts show Kimi Linear trailing competitors like Qwen3, though others argue this is impressive given Kimi was trained on significantly less data. Several developers claim that in their own internal tests, particularly for coding tasks, Kimi Linear is "way superior" to its rivals, suggesting that standard benchmarks may not tell the whole story.
Moonshot AI has released the model checkpoints and KDA kernel code, positioning Kimi Linear as a drop-in replacement for full-attention transformers.
The daily brief
Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.
Join 64,000 other subscribers.
For now, it represents a compelling architectural experiment, but its true impact will depend on how quickly the open-source community can build the tools to run it efficiently.





