

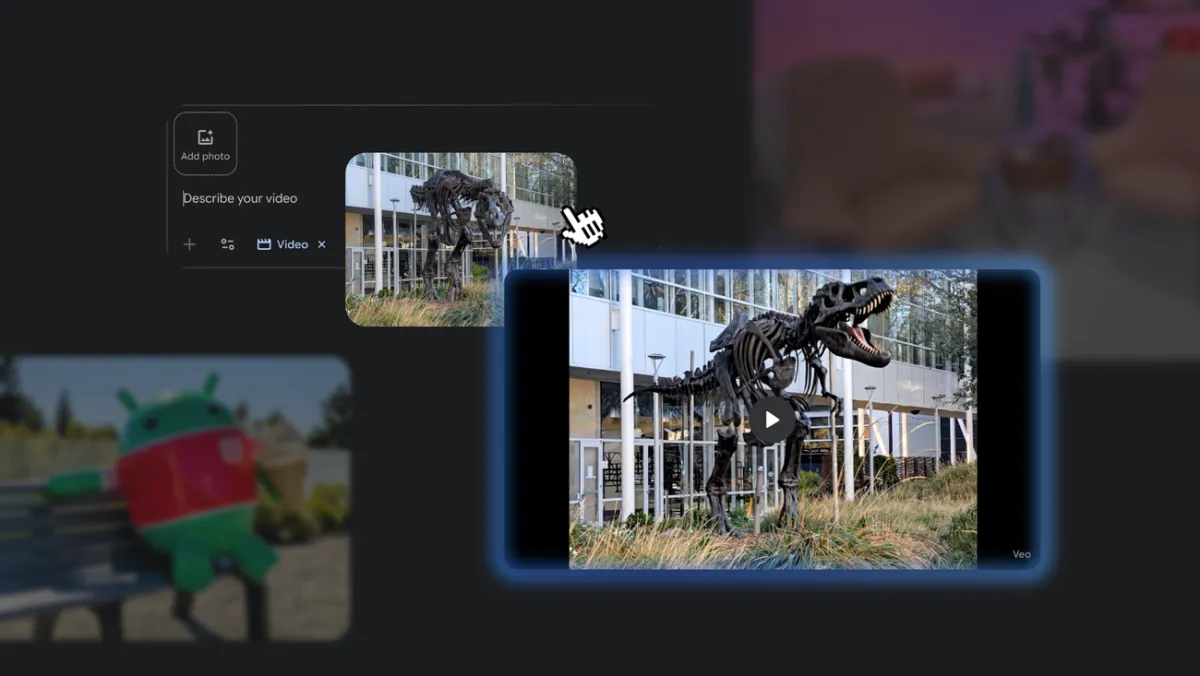
Google's Gemini AI is stepping up its multimodal game, introducing new photo-to-video capabilities that promise to transform how users create dynamic content. This move democratizes video production, putting powerful animation tools into the hands of everyday creators and challenging the existing landscape of generative AI.
Google Gemini is pushing further into multimodal AI, now offering users the ability to transform static images into dynamic video clips. This isn't just a party trick; it's a significant step in democratizing video creation, placing sophisticated animation tools directly into the hands of everyday users and content creators. The integration of advanced photo-to-video features within Gemini signals Google's intent to remain a frontrunner in the generative AI race, particularly as the lines between image and video generation continue to blur.
For years, animating still photos or crafting short video sequences required specialized software, a steep learning curve, or a significant budget. Gemini aims to dismantle these barriers. According to the announcement, the new capabilities allow users to breathe life into their images in several intuitive ways. Imagine taking a cherished photograph and, with a few prompts, seeing a gentle breeze rustle leaves in the background, or a subtle camera pan adding cinematic flair. This isn't about creating Hollywood blockbusters, but rather about making short, engaging, and personalized video content accessible to everyone.
The core functionality revolves around three distinct approaches to Google Gemini photo video. First, users can animate a single still image, adding subtle, localized movements. Think of a person's hair gently blowing in the wind, water rippling realistically in a pond, or smoke curling from a distant chimney, transforming a static moment into a living scene with specific elements brought to life. Second, Gemini can generate short, cohesive video clips from a series of related photographs. This allows for the creation of mini-montages, automated slideshows with smooth transitions, or time-lapse effects, effectively weaving a narrative from multiple stills without manual interpolation. Third, the AI can introduce dynamic camera movements, pans, zooms, or tilts, to a static scene. This gives the impression of a professional videographer at work, simulating cinematic camera work over a single still photo, adding depth and engagement without altering the image content itself. These features are designed to be user-friendly, requiring minimal technical expertise, which is crucial for broad adoption.
This move isn't happening in a vacuum. The generative AI landscape is fiercely competitive, with players like RunwayML, Pika Labs, and even OpenAI's Sora pushing the boundaries of what's possible in video generation. Google's entry with Google Gemini photo video capabilities is a clear statement: they are not just observers but active participants shaping the future of digital content. By integrating these tools directly into Gemini, Google leverages its vast user base and existing ecosystem, potentially accelerating the mainstream adoption of AI-powered video creation and setting a new standard for multimodal interaction.