

#Mixture-of-Experts
18 articles with this tag
Mistral says Large 4 leads Europe, proof thin
Arthur Mensch pitched Mistral Large 4 on France Inter as an hours-long agentic model, but benchmarks, scores and broad access remain undisclosed.
MoE Models Tackle LLM Hallucinations
InnerExpert leverages MoE architecture's internal signals for per-token hallucination detection, achieving state-of-the-art results with high efficiency.
llamafile v0.10.5 Ships With Big Local Models
Llamafile v0.10.5 adds support for two large local AI models, Ternary Bonsai 27B and Laguna-S-2.1, by updating its core llama.cpp integration.
Thinking Machines Lab cuts costs with Inkling-Small
Thinking Machines Lab launches Inkling-Small, a 276B parameter model that delivers comparable performance to its larger predecessor at a fraction of the cost.
Together AI partners with Moonshot AI
Together AI partners with Moonshot AI to offer Kimi K3 and future models, providing developers with day-zero access to large-scale open-source AI.

Mira Murati Ships Inkling: 975B-Parameter Open Model Backed by Nvidia
Thinking Machines Lab released Inkling on July 15, a 975-billion-parameter open-weight mixture-of-experts model trained from scratch on 45 trillion tokens, 22 months after Mira Murati left OpenAI.
Together AI adds Inkling multimodal model
Together AI integrates Inkling, a new multimodal AI model from Thinking Machines Lab, offering text, image, and audio processing with controllable reasoning.
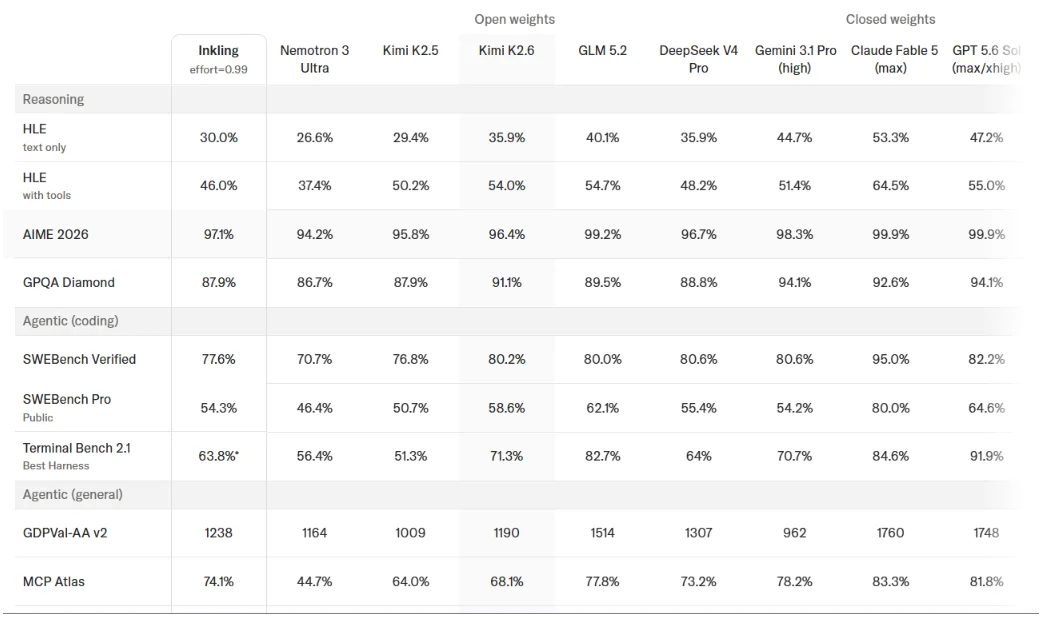
Inkling AI Model: Open-Weights Multimodality
Thinking Machines unveils Inkling, an open-weights, multimodal AI model with 975B parameters, designed for customization and efficient, controllable thinking.
Mira Murati's Interaction Model: Full-Duplex AI at 0.4 Seconds
Thinking Machines Lab's TML-Interaction-Small processes audio and video in 200ms chunks, responds in 0.4 seconds, and runs full-duplex without a VAD harness. Here is how the architecture works and what Murati said at Bloomberg Tech.

MobileMoE LLMs Redefine On-Device AI
MobileMoE LLMs redefine on-device AI, setting new performance and efficiency benchmarks for sub-billion parameter models on smartphones.
AI at Graduations & Claude's Blackmail Tactics
IBM experts discuss AI's evolving role, from college graduations to ethical dilemmas like LLM data corruption and potential 'blackmail' scenarios.

Shodh-MoE: Unlocking Universal SciML
Shodh-MoE's sparse activation architecture resolves multi-physics interference in SciML, enabling universal foundation models with guaranteed physical properties.
Google DeepMind Unveils Gemma 4 AI Models
Google DeepMind releases Gemma 4, a new family of open-source AI models featuring advanced architectures, multimodal capabilities, and improved performance.
AI in Science: Faster Discovery, New Insights
AI is revolutionizing scientific research, from data analysis to hypothesis generation. Experts discuss how AI tools like LLMs are accelerating discovery while highlighting the continued importance of human expertise.

Bayesian Uncertainty for Foundation Models
Variational Mixture-of-Experts Routing (VMoER) offers a scalable Bayesian approach to uncertainty quantification in foundation models, achieving significant improvements with minimal computational overhead.
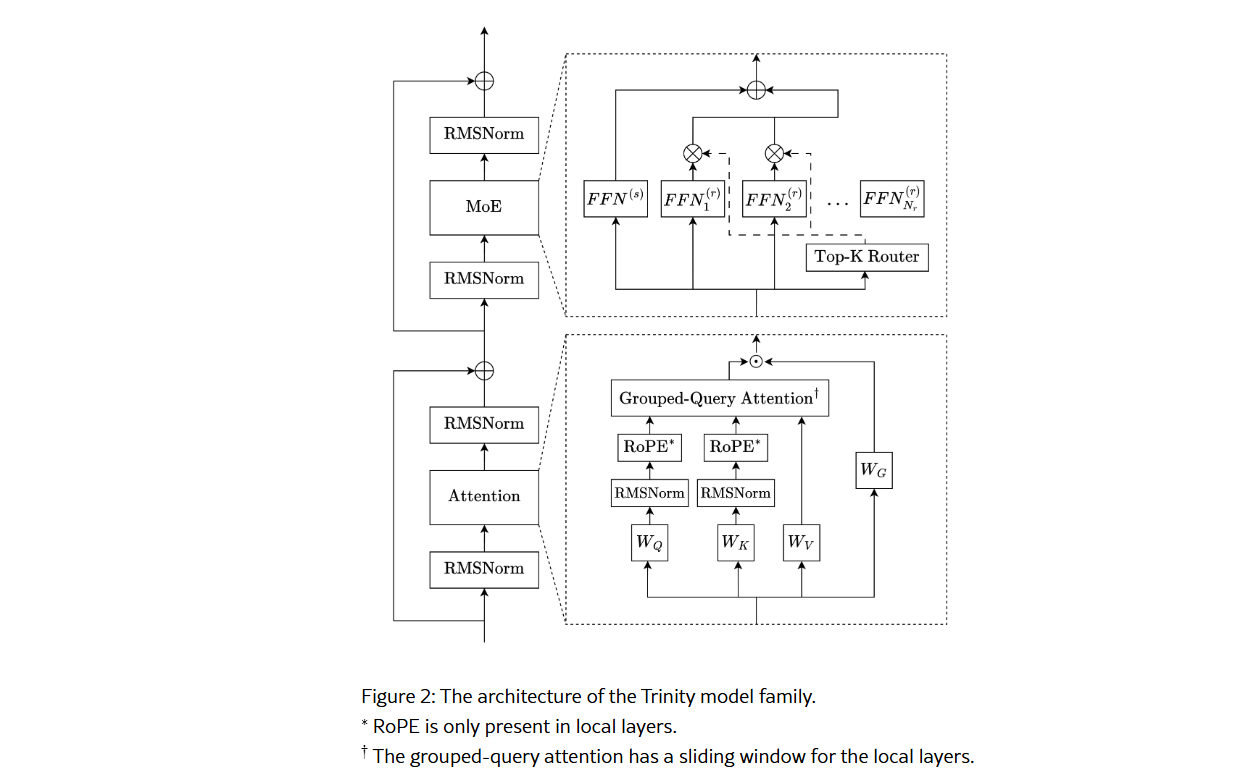
Arcee Trinity Large Breaks Cover
Arcee.ai unveils Trinity Large, a 400B-parameter Mixture-of-Experts model engineered for inference efficiency and enterprise long-context use, alongside smaller variants.
GPT-OSS-Puzzle-88B: Faster AI, Same Brains
GPT-OSS-Puzzle-88B offers substantial inference speedups for large language models without sacrificing accuracy, utilizing techniques like MoE pruning and window attention.
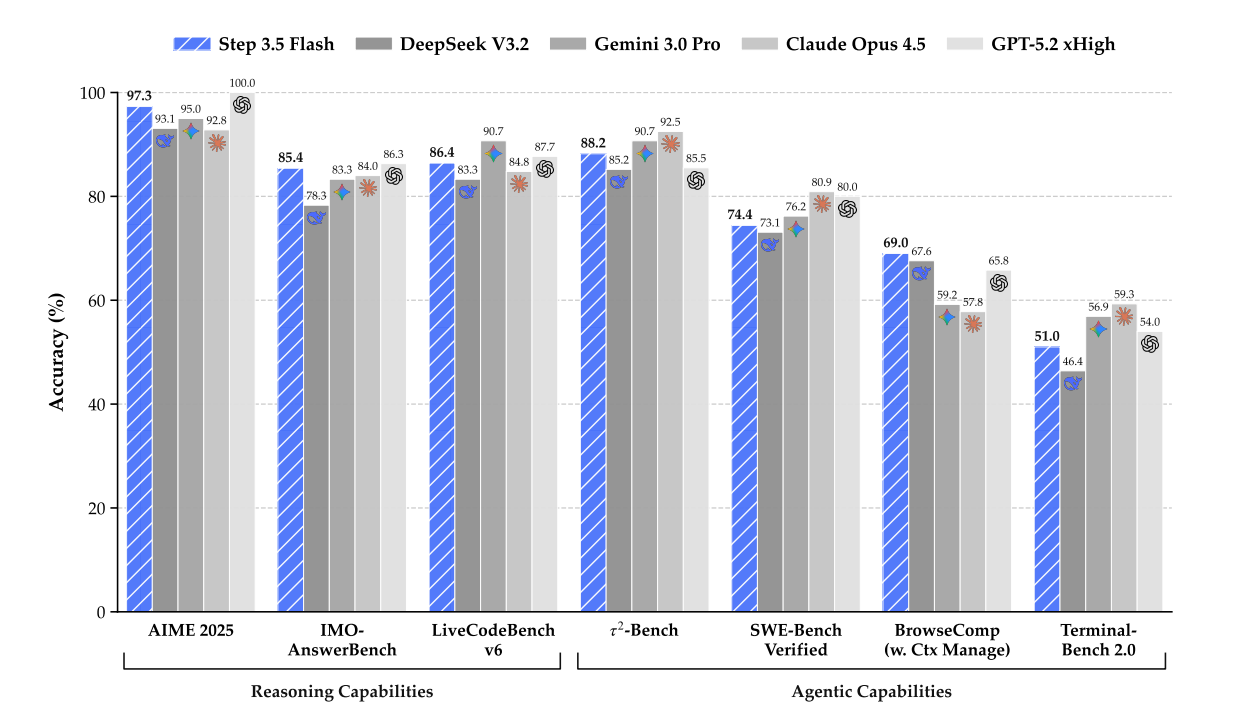
Step 3.5 Flash: AI's New Efficiency Standard
Step 3.5 Flash AI model revolutionizes AI efficiency with a 196B parameter foundation and 11B active parameters, offering competitive performance with lower latency.