

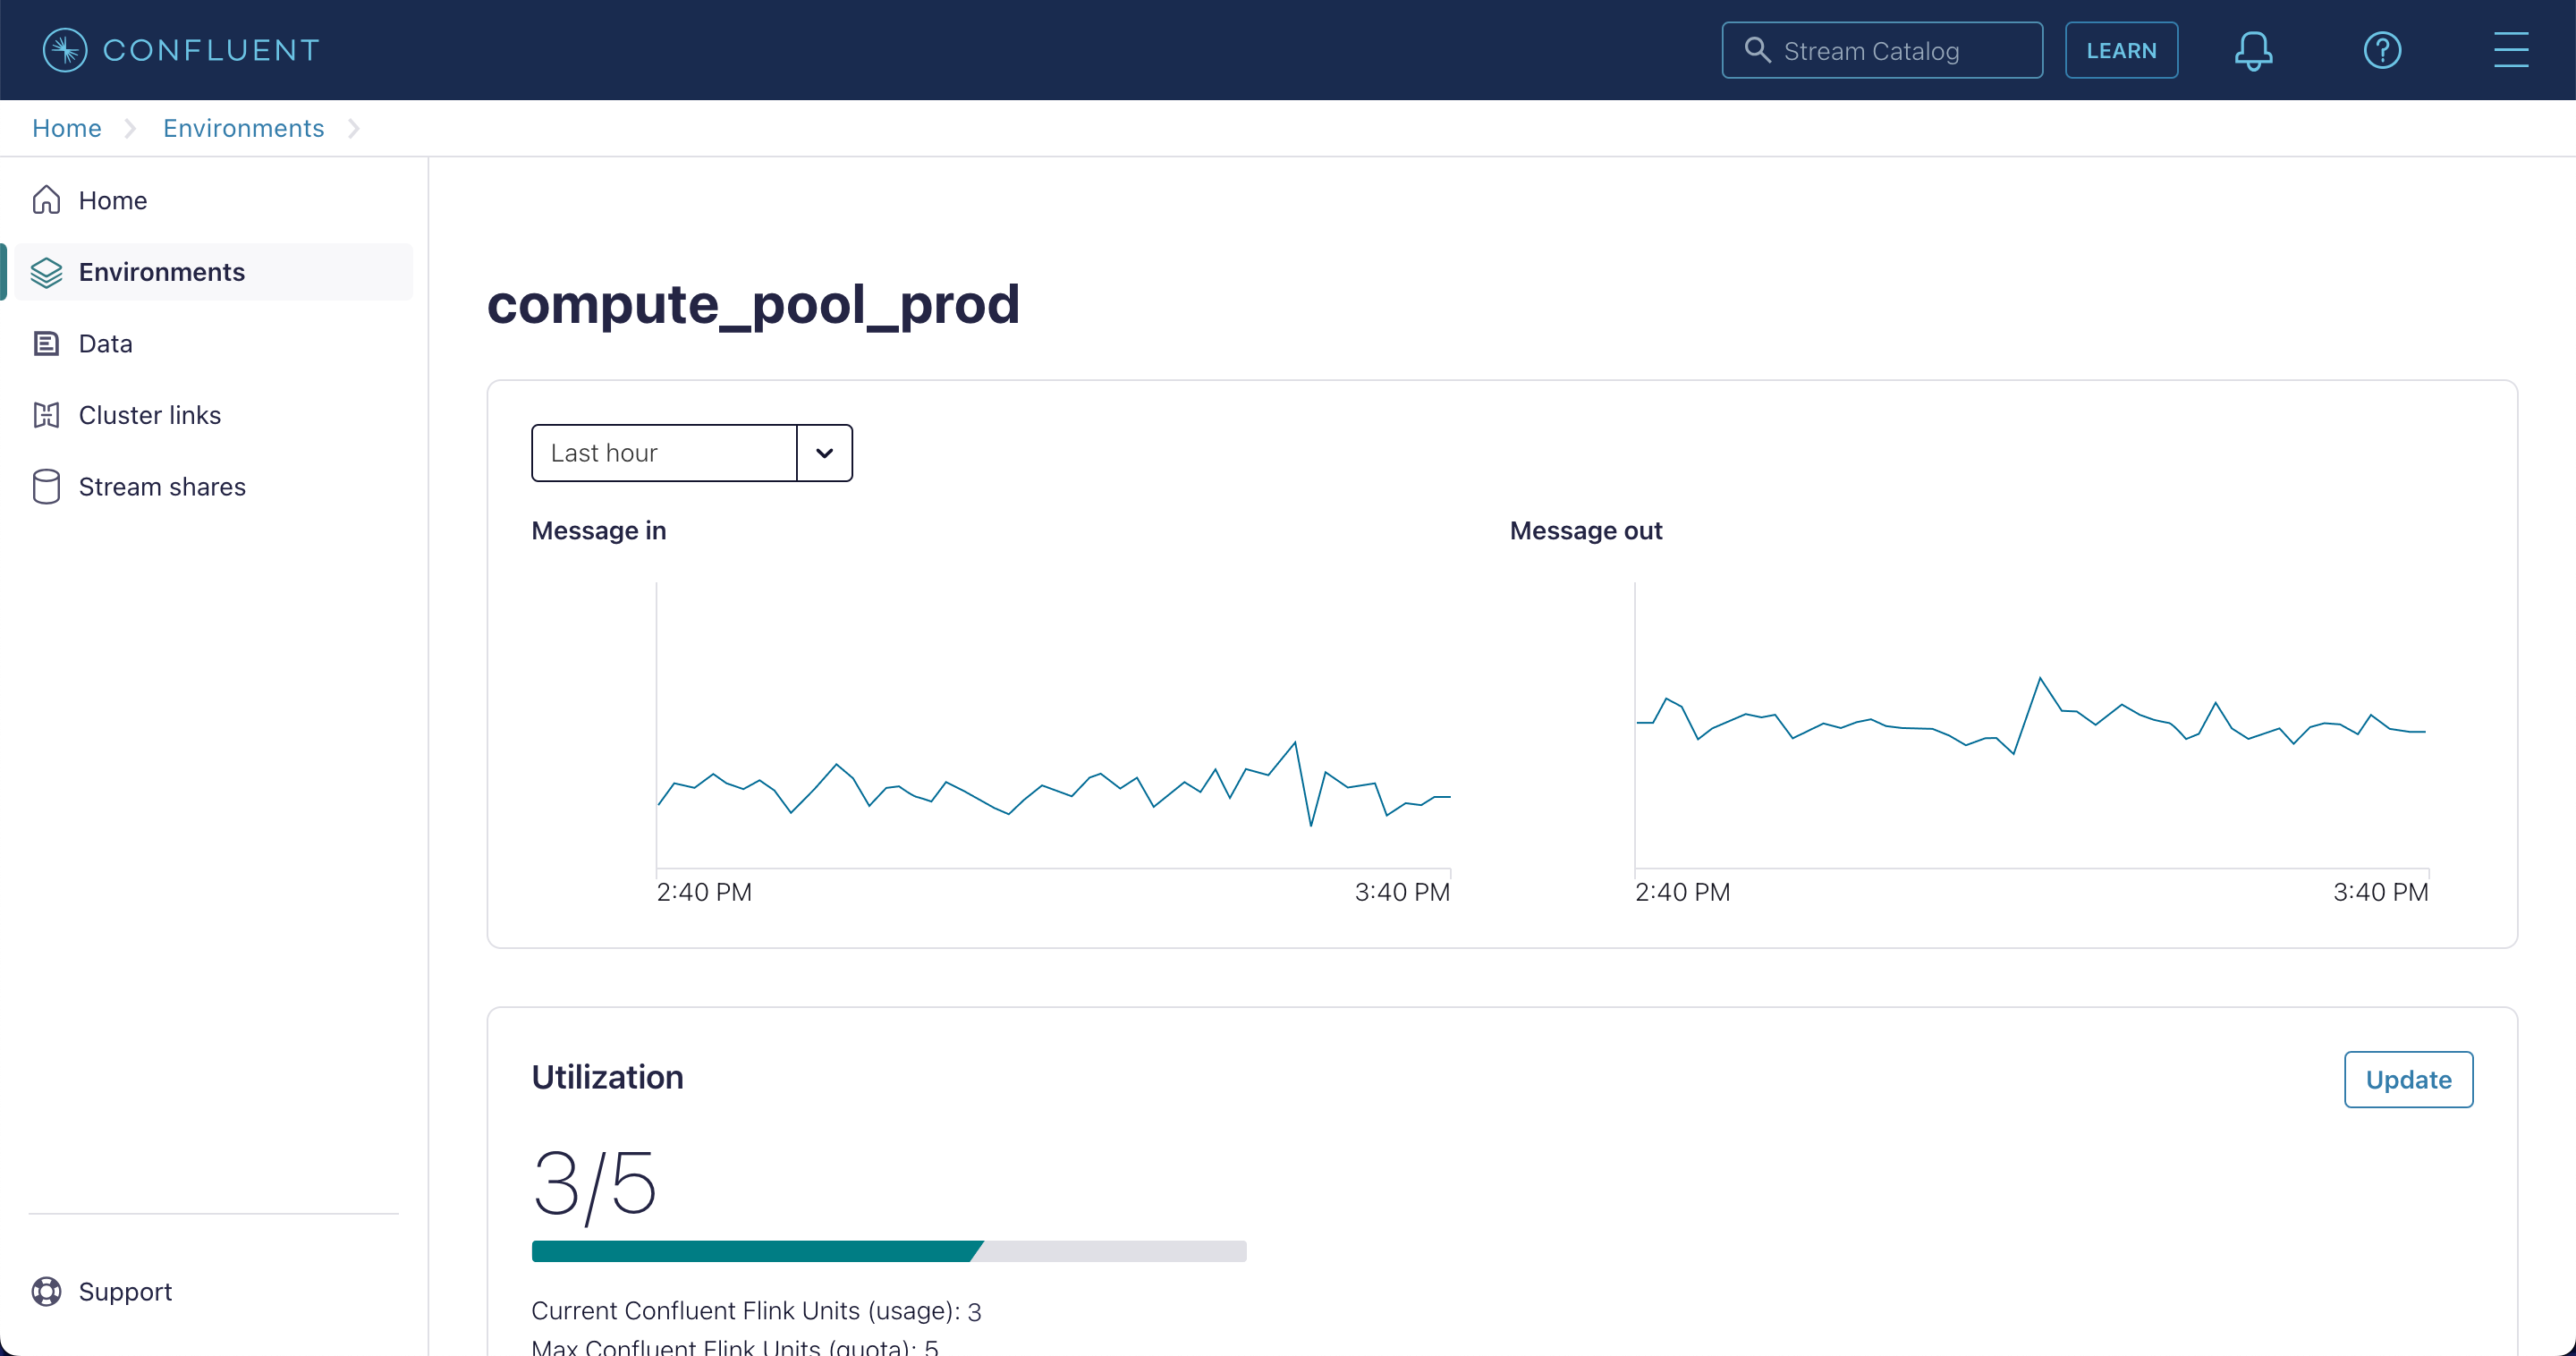
Confluent unveiled their open preview of Apache Flink on Confluent Cloud, a new managed service for companies aiming to optimize the building of real-time applications via stream processing on a unified platform. The new service emerges as a singular solution in the industry, being both serverless and cloud-native, focusing on facilitating the construction of high-quality, reusable data streams. The data streaming giant also announced Data Portal, enabling team to discover all of their real-time data streams and to reduce Apache Kafka costs, as well as storage costs on Confluent Cloud.
Apache Flink, a project under the Apache Software Foundation, has evolved as a universally accepted standard for stream processing due to its robust features, high performance, and extensive developer community. It is predominantly used in conjunction with Apache Kafka, the de facto technology for data streaming, to support crucial company workloads.
The Data Portal feature ensures that teams can easily discover and utilize all the real-time data streams within their organization. The Data Portal’s innovative interface assists teams in efficiently accessing and applying real-time data streams, promoting the accelerated development of real-time applications and products.
With the new Confluent Cloud Enterprise offering, costs related to private networking and storage for Apache Kafka are significantly lowered. This includes a 20% reduction in storage costs effective from October 1, 2023, which allows teams to retain all real-time and historical events without restrictions, enabling more extensive use of streaming applications.
While Flink is pivotal for companies from various sectors, including ride-sharing, banking, and social media, self-managing this technology is fraught with challenges, including operational complexity and high costs related to infrastructure and management. Confluent’s service mitigates these issues by simplifying stream processing and accelerating application development.