
Updating the brains of a massive AI model used to be a sluggish affair, often taking minutes to sync new knowledge from a training cluster to a live inference cluster. Now, a new technique for fast GPU weight transfer has slashed that time to a mere 1.3 seconds for a trillion-parameter model, a critical breakthrough for real-time reinforcement learning (RL).
The achievement, detailed by the engineering team behind the Kimi-K2 model, addresses a fundamental bottleneck in modern AI. In asynchronous RL, models are constantly learning on one set of GPUs while serving users on another. The delay in transferring these learned "weights" means the inference model is always working with stale information. Existing frameworks that funnel all data through a single GPU create a traffic jam, limited by one machine's bandwidth.
The RDMA Advantage
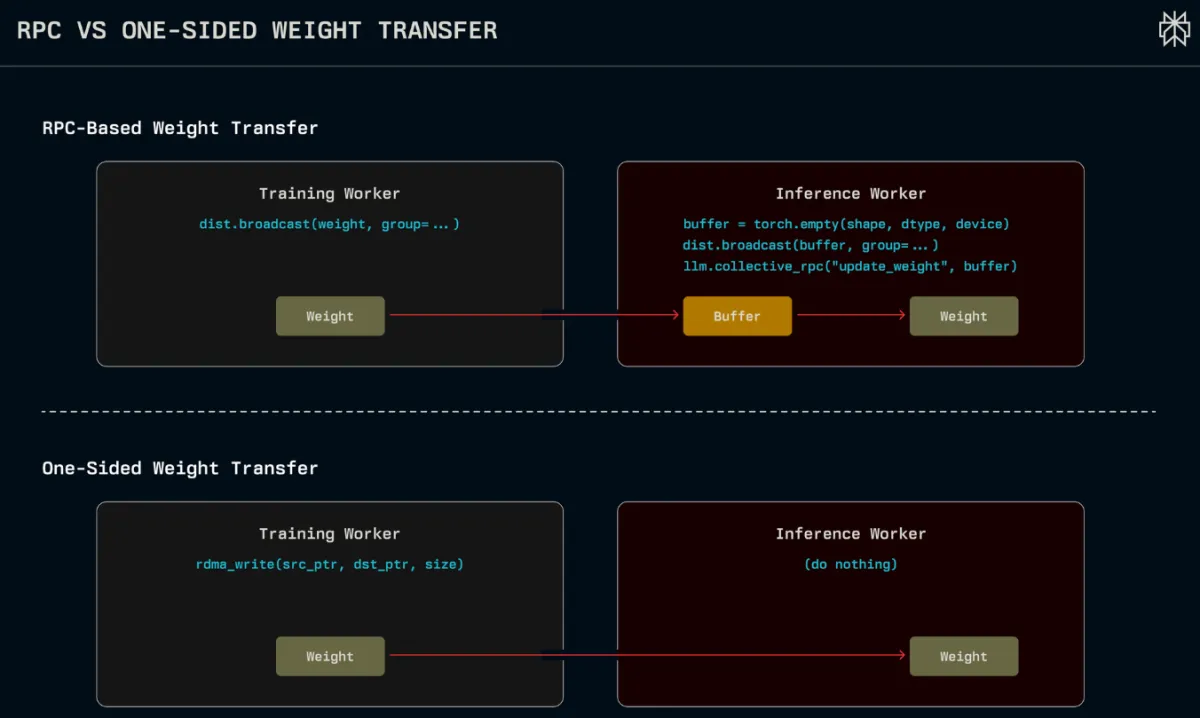
The new system sidesteps this bottleneck by using RDMA (Remote Direct Memory Access) WRITE, a one-sided communication primitive. Instead of a complex, multi-step process, a training GPU can now write data directly into the memory of a remote inference GPU. The destination GPU isn't even notified; the update just appears. This zero-copy, point-to-point approach allows every training GPU to communicate with every inference GPU simultaneously, saturating the entire network fabric instead of a single link.
This is paired with a static transfer schedule computed once at initialization. After each training step, a controller simply gives a "go" signal, and all GPUs execute their pre-planned, pipelined tasks. The process is broken into stages, like data prep, quantization, and the RDMA transfer itself, which overlap to maximize the use of every piece of hardware.
By eliminating the central choke point and the overhead of traditional communication protocols, this method for fast GPU weight transfer doesn't just speed things up; it simplifies the entire process. It requires no intrusive changes to the inference engine and results in a system that is easier to maintain and debug. For the AI industry, it's a significant step toward building larger, more responsive models that can learn and adapt in near real-time.





