Ryan Stevens told AI Engineer that Ramp spent four to six months building end-to-end evals before launching Stacks, its AI bookkeeping agent.
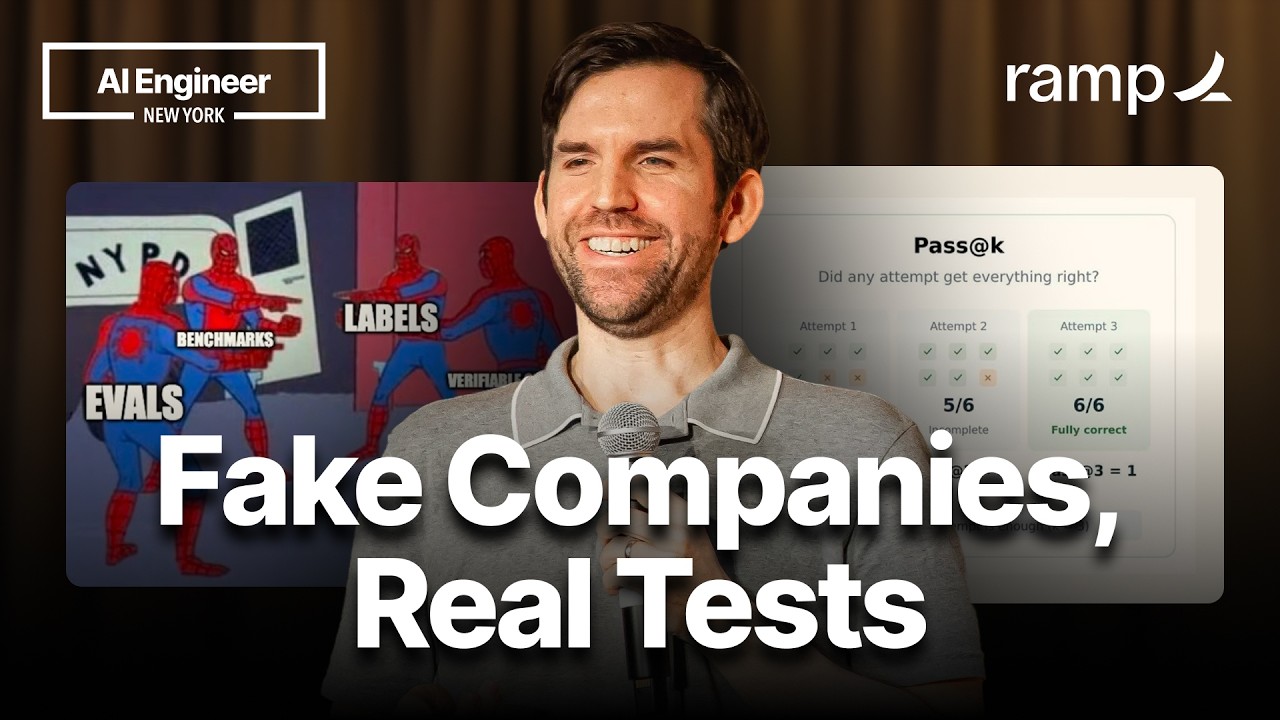
They grade only the final ledger, not the path.
To do it without live customers, Stevens said Ramp and Mercor built synthetic businesses with full ERPs, vendor lists and payables, then ran each reconciliation, data entry, variance and accruals task against 10 to 20 pass-fail criteria for accuracy and pass-at-K.
The failures were reasoning, not data gathering, Stevens said, which is why frontier models scored high on accuracy but collapsed on pass-at-one and why auto-tuning skills in the style of Andrej Karpathy's tuning posts failed while skill ablation and trajectory-distilled memories delivered the biggest gains.
Separate Ramp spend data shared on the All In podcast puts Google behind in agentic usage per EconLab, matching Stevens picking Opus.
Now Stacks evals run on schedule and ping Slack on regressions because Stevens said CI gating breaks at 70 to 80 percent pass rates.