
No prediction venue prices Fieldguide's assurance pattern, so there are no current odds, no volume and nothing moved. The limitation is liquidity does not exist for this kind of infrastructure claim. Not financial advice. Markets move fast.
The obvious reading is Fieldguide solved audit agents with four controls. I do not buy it. Anirudh Veeraragavan, lead security engineer at Fieldguide, told AI Engineer that in audit the opinion is the product and the opinion is only as good as the basis behind it.
His test case was bank reconciliation. A fictional client held around $2.9 million at the bank against $2.7 million on its books, he said, with the gap explained by 41 reconciling items. He invoked Peregrine Financial Group, which claimed over $200 million on paper while only $5 million sat at the bank, to argue that being right is not enough when fraud can erase $200 million.
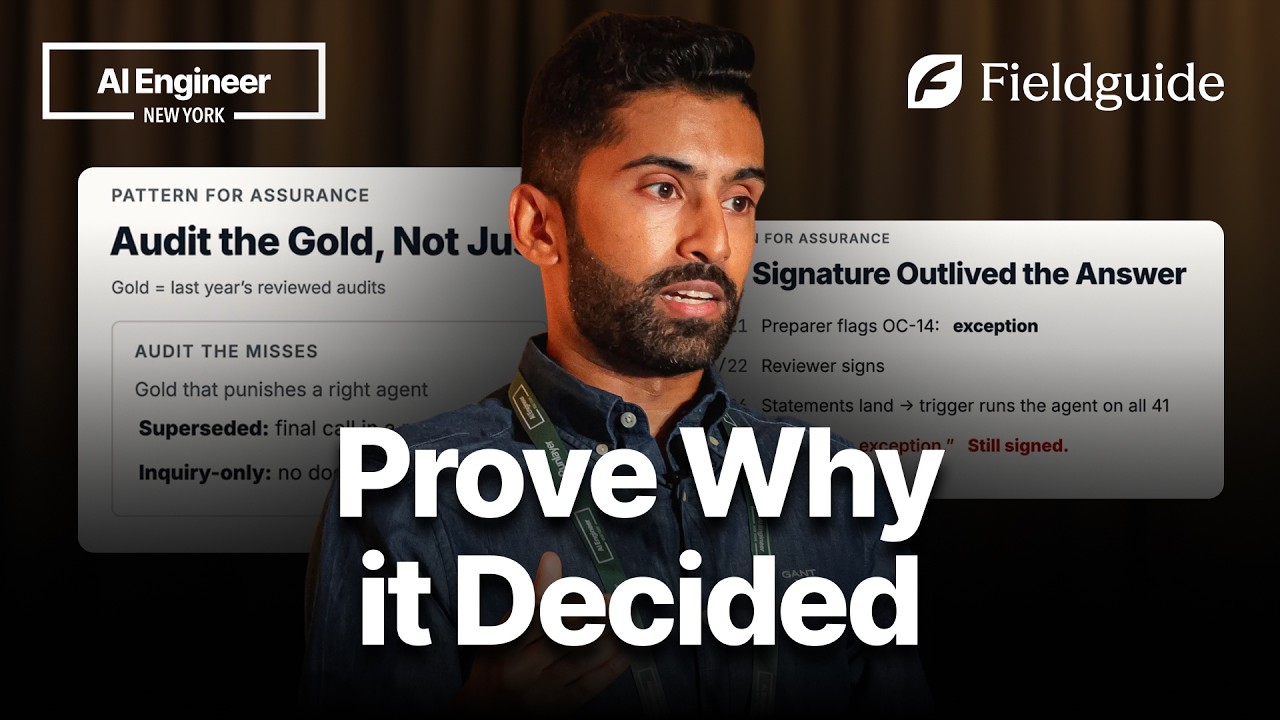
Veeraragavan's answer is decision assurance with four controls that must all hold. Authorization means an agent can draft unreviewed rows but cannot overwrite human-reviewed work, he said. Execution control means a chain of recorded steps with IDs for inputs and outputs, so single steps can be rerun. Evidence provenance means a citation is identity with document ID, version and content hash, he said, not a filename string. Evaluation integrity means auditing the gold set itself because his 97% headline score hid four cases where the eval was wrong and 12 where Veeraragavan said methodology changes made old labels wrong.
That last point is his strongest evidence and also the hole in the pitch. What would have to be true for the obvious reading to hold is versioned evidence on every run, deterministic replay years later, clean evals despite shifting rules, and reviewers who resist automation bias when the agent handles 80% of cases and flags 20% for humans, according to Veeraragavan. He does not price that work. The incumbent push is real, with KPMG saying its KPMG Clara platform uses governed agents to support continuous analysis and data-intensive procedures.
To his credit, Veeraragavan states the claim fairly before testing it. Defensibility is an AND, he said, and the same questions apply to credit approvals and anti-money laundering alerts. If you cannot rerun the decision step by step and name the evidence version, do not ship it as autonomous.





