Don't trust agents. Test them like scientists.

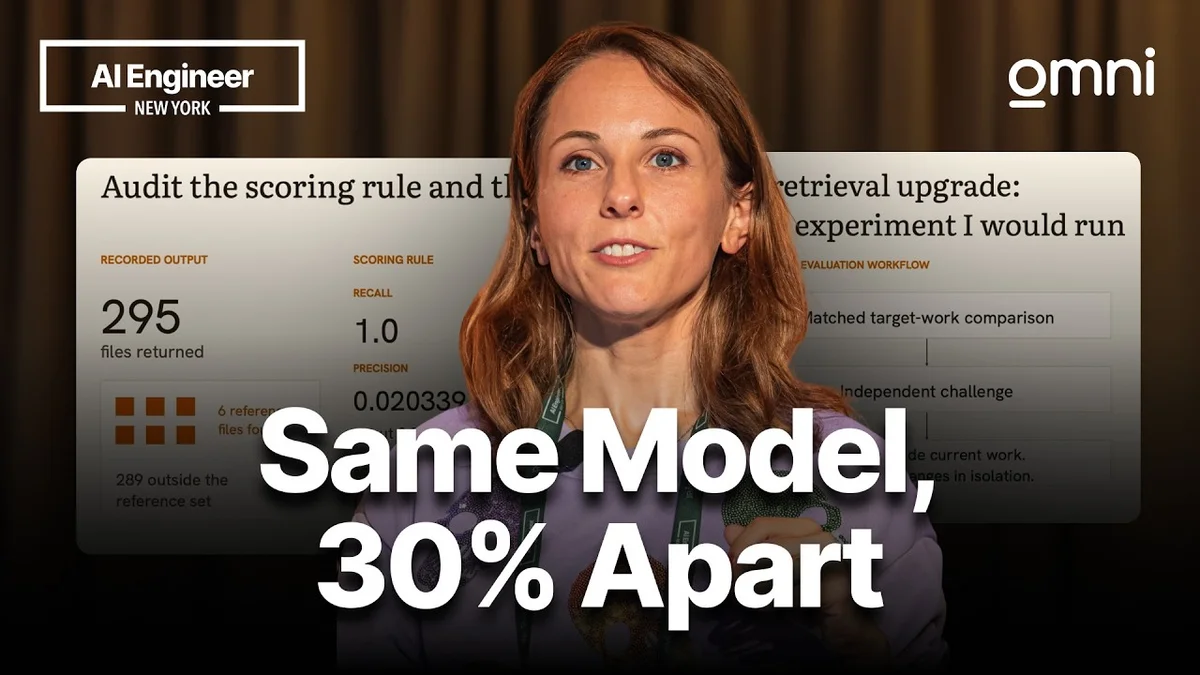
Stephanie Jarmak told AI Engineer teams must test AI agents like scientists after a 28% cheaper run still failed to use its tool.

Stephanie Jarmak presenting agent evaluation results on stage
AI Engineer

Stephanie Jarmak told AI Engineer to stop trusting AI agents and test them like scientists, citing a 28% cost drop that masked a complete tool-use failure.
Don't trust agents. Test them like scientists. - AI Engineer
Don't trust agents. Test them like scientists., AI Engineer

She showed 63 Turbo Bench 4 tasks where swapping only the harness flipped results by more than 30% between Opus 5 and Astra.

Jarmak, an AI engineer at Omni Analytics and former Sourcegraph evaluation lead who built Code Scale Bench, said teams must "relentlessly question everything" and keep full traces to diagnose why agents ignore tools.

She measured Claude returning 295 files when 6 were needed with grep, a case where optimizing for recall hides poor precision and inflates F1.

She warned traces themselves can lie, noting a hash check passed despite injected security issues until an independent record comparison detected every change.

Her software factory relies on approval queues and audits, but a 1% false alarm rate would still force 10,000 human reviews with no clear capacity model.

Public coding benchmarks like SWE-Bench Pro now average 107.4 lines across 4.1 files per Scale, yet Jarmak said production is truth and teams must measure in shadow before granting autonomy, pointing to a GitHub repo and 300-page archive teams can use now.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.

