AI

Agentic AI's Cost Problem

Agentic AI's insatiable token appetite demands a new cost calculus beyond GPU hours. Crusoe and NVIDIA highlight cost per token and goodput.

Daniel Singer

By Daniel Singer, Editor, StartupHub.ai

4 min read

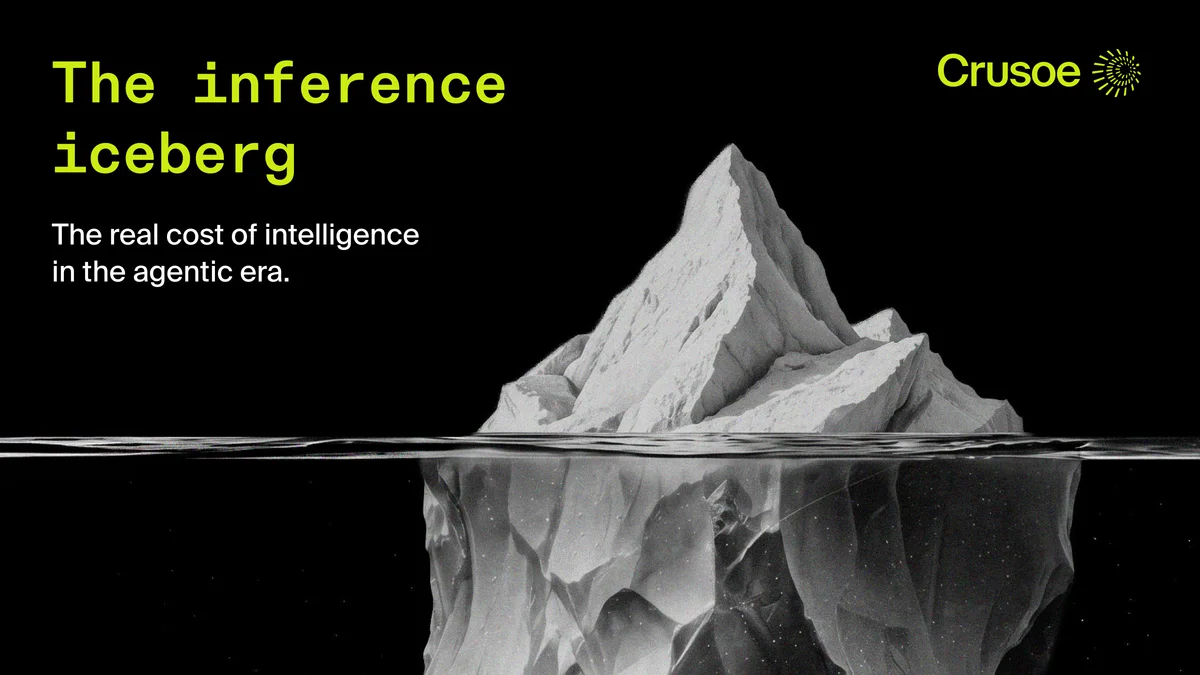
Infographic showing the AI inference iceberg with visible GPU/hour metrics and hidden cost per token factors.
Credit: Crusoe Blog
Visual TL;DR
Agentic AI EmergesDriver
sophisticated multi-step reasoning and tool usage, adapting on the fly when steps fail
From the article 5 mentionsAgentic AI, which involves sophisticated multi-step reasoning and tool usage, can gobble up 10 to 100 times more tokens per task than a typical single-turn chat.
Open-Source StackCore
plays a role in shaping the economic equation for running AI
From the article 2 mentionsComplementing the physical layer is the open-source AI stack.
High Token AppetiteDriver
gobbles 10 to 100 times more tokens per task than single-turn chat
From the article 2 mentionsThis high volume of token processing, coupled with demands for low latency and consistent performance, strains existing infrastructure and budgets.
GPU-Hour InsufficientDriver
simple request-response model pricing no longer predicts inference expenses
From the articleThe economic equation for running AI is fundamentally changing, and simple GPU-hour pricing simply won't cut it anymore.
Physical FoundationContext
infrastructure built for simple request-response, now needs new tokenomics
From the article 3 mentionsBeneath the software and silicon lies the often-overlooked physical infrastructure.
New Cost MetricsCore
Crusoe and NVIDIA pushing cost per token and goodput for inference
From the article 9+ mentionsThis explosion in token throughput demands a new way of thinking about inference costs, moving beyond raw compute metrics to a deeper understanding of tokenomics.
Goodput: Actual ValueContext
measures the actual value delivered by the AI system, not just raw compute
Cost ProblemOutcome
economic equation for running AI is fundamentally changing, demanding new calculus
From the article 7 mentionsThe ultimate measure of inference efficiency, as highlighted by Crusoe and NVIDIA, is cost per token.
Contents(6)

The economic equation for running AI is fundamentally changing, and simple GPU-hour pricing simply won't cut it anymore. Agentic AI, which involves sophisticated multi-step reasoning and tool usage, can gobble up 10 to 100 times more tokens per task than a typical single-turn chat. This explosion in token throughput demands a new way of thinking about inference costs, moving beyond raw compute metrics to a deeper understanding of tokenomics. Crusoe and NVIDIA are pushing this conversation forward, highlighting metrics that truly predict inference expenses in this new era.

The Agentic Shift

AI inference infrastructure was largely built for a simple request-response model: send a prompt, get a completion. Agentic AI systems, however, operate differently. They execute complex plans, maintain state across numerous inference calls, interact with external tools, and adapt on the fly when steps fail. Consider a customer support agent tackling a complex enterprise issue. It might initiate over a dozen tool calls, perform multiple searches, summarize documents, and then generate a final response. While the end output might be 800 tokens, the underlying process could easily process 50,000 tokens or more. This high volume of token processing, coupled with demands for low latency and consistent performance, strains existing infrastructure and budgets.

Beyond GPU/Hour: New Metrics Emerge

For years, the industry relied on easily visible metrics like GPU hours and FLOPS per dollar. These tell you how much compute power you can rent, but not necessarily how much value you're getting out of it. NVIDIA has previously used the metaphor of an "inference iceberg" to illustrate this point, with GPU/hour and FLOPS being the visible tip. Beneath the surface lie the critical factors that determine real-world token output. The ultimate measure of inference efficiency, as highlighted by Crusoe and NVIDIA, is cost per token. This metric reflects the actual expense of producing each delivered token under production conditions. However, a complete picture requires looking at tokens per watt, cost per completed task, and goodput, the measure of useful work done within acceptable latency.
The Physical Foundation Matters

Beneath the software and silicon lies the often-overlooked physical infrastructure. How an AI factory is powered, cooled, and networked sets the ceiling for sustained throughput and energy efficiency. For agentic workloads demanding continuous high utilization, efficient power distribution and advanced cooling solutions become paramount. Crusoe, for instance, emphasizes its approach to securing power, often below market rates, and designing AI factories for long-term efficiency using diverse energy sources. Their use of direct liquid cooling, for example, improves facility efficiency and directs more power towards token production rather than overhead. This vertically integrated approach, controlling everything from energy sourcing to data center development, allows for structural advantages in delivering the sustained, high-throughput inference that agents require.

The Open-Source Stack's Role

Complementing the physical layer is the open-source AI stack. Open models increasingly offer frontier-level reasoning capabilities at a fraction of the cost of proprietary alternatives. NVIDIA's Nemotron 3 Ultra, for example, combined with frameworks like LangChain's Deep Agents harness, demonstrates that optimized inference environments can match top closed models. Crusoe is an early adopter of NVIDIA's DSX platform, integrating it into their AI factories to boost performance and efficiency. Furthermore, Crusoe contributes to the open-source community, developing tools like fastokens, which significantly speeds up tokenization for agentic workloads running on NVIDIA Dynamo, a key serving framework. This collaborative approach, where infrastructure and software are co-designed, is key to achieving low cost per token.

The daily brief

Get the free daily brief with the day's AI news, new AI startups and funding rounds every morning.

Join 64,000 other subscribers.

Goodput: Measuring Actual Value

While throughput measures total tokens generated, goodput measures the tokens that actually advance a task to completion within acceptable latency. For agentic systems, this distinction is critical. If a multi-step agent fails at step eight due to timeouts or bottlenecks, all the tokens generated in the preceding steps are wasted. High throughput with low goodput leads to a high cost per task, regardless of how cheap individual tokens are. Crusoe's inference engine, powered by MemoryAlloy TM technology, focuses on cluster-wide KV caching and context-aware routing to minimize redundant computations and maximize goodput, ensuring that infrastructure spend translates into completed work.

StartupHub Observation

This focus on granular tokenomics and physical infrastructure efficiency by companies like Crusoe is a critical signal for founders building the next generation of AI agents. While OpenAI and Anthropic might push the boundaries of model capability, startups that can deliver agents with sustainable unit economics on efficient infrastructure will capture significant market share. Investors are increasingly scrutinizing not just model performance but the operational costs of deploying AI at scale, making infrastructure efficiency a key differentiator.

Mentioned in this story

Sources

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

TopicsCrusoeNvidiaNVIDIA DSX PlatformNVIDIA Nemotron 3 UltraLangChainMemoryAlloy TMfastokensNVIDIA Dynamo

Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute, free.

Watch

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.