

#vLLM
4 articles with this tag
AI Research
DeepSeek ships faster Flash with shorter outputs
DeepSeek's V4.1-Flash-1017 claims faster agentic execution with shorter outputs and drops the Jinja chat template for a new encoding toolkit.
about 2 hours ago
Artificial Intelligence
70% Automated Means Nothing Without a Boundary
Soukaïna Abelhad told AI Engineer that 70% automated claims fail unless they survive arithmetic, definition and quality checks.
3 days ago
Technology
Qwen 3.5 122B Kernel Gains Hide Validation Risk
Databricks’ Proteus hit 1.8, 5.2x on Qwen 3.5 122B kernels by specializing for runtime shapes, but only after fixing reward-hacking in validation.
about 1 month ago
Technology
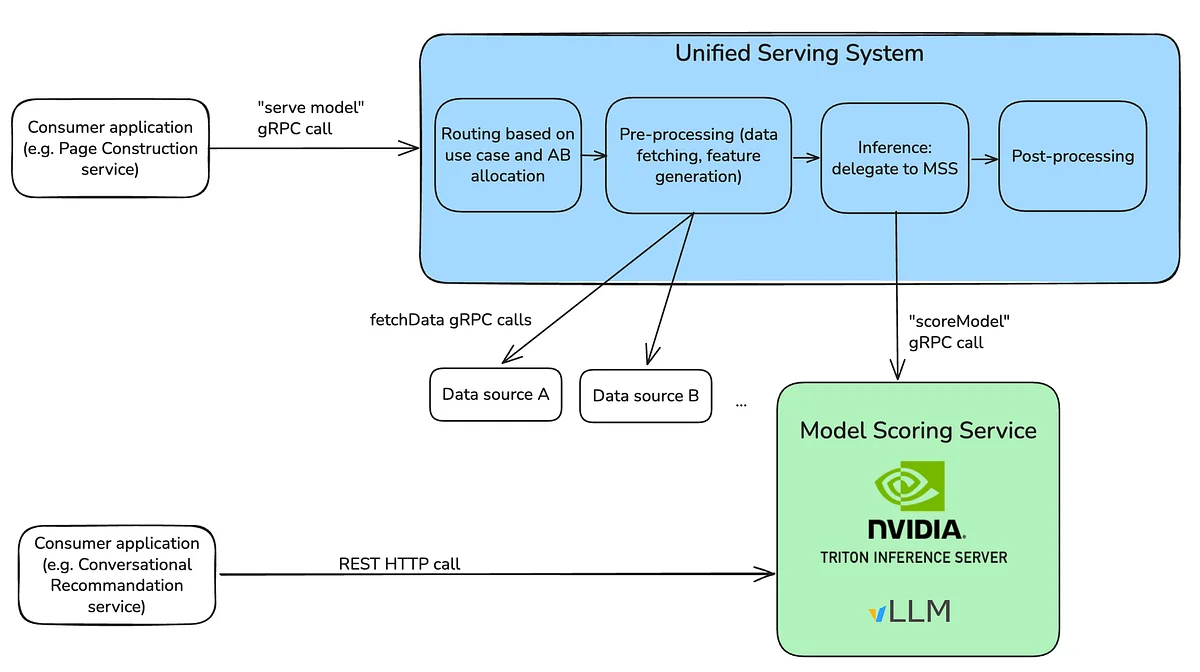
Netflix's LLM Engine Revealed
Netflix reveals its custom LLM serving infrastructure built on vLLM and NVIDIA Triton, enabling flexibility and performance within its production environment.
3 months ago