Alex Shaw: "Everything Is a Rollout" in AI Agent Evaluation

Alex Shaw from Lode Institute explains the Harbor framework, highlighting how agent development mirrors ML and requires empirical evaluation. Discover the tools and use cases for building and testing AI agents.

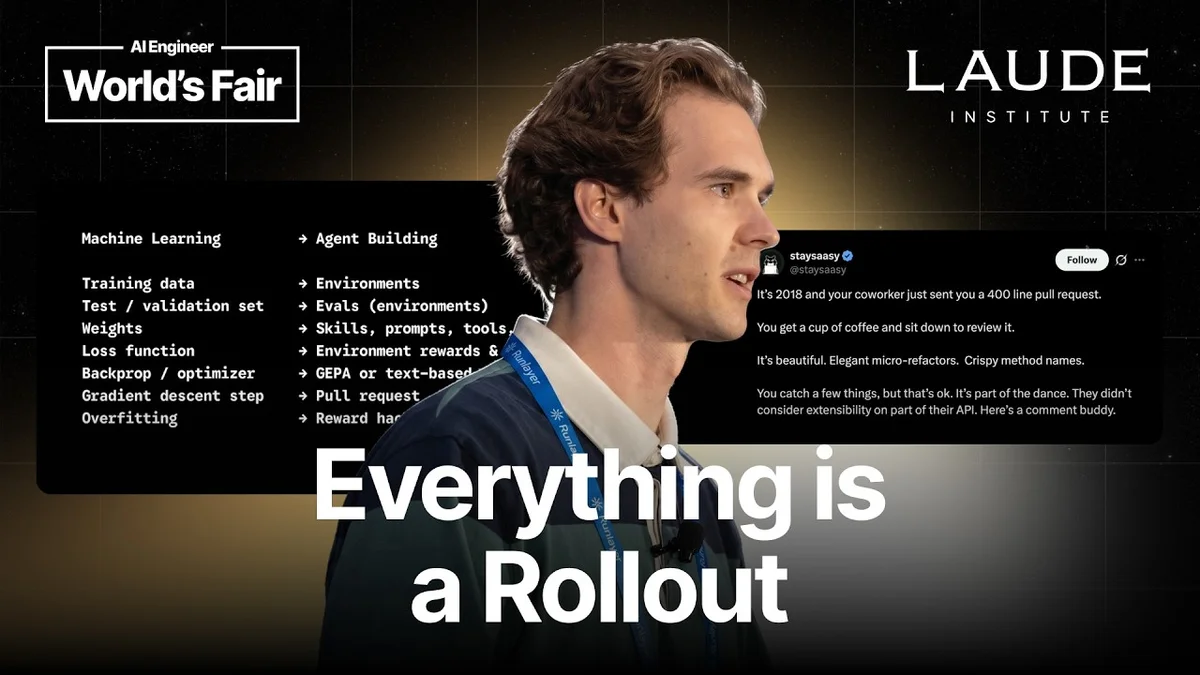
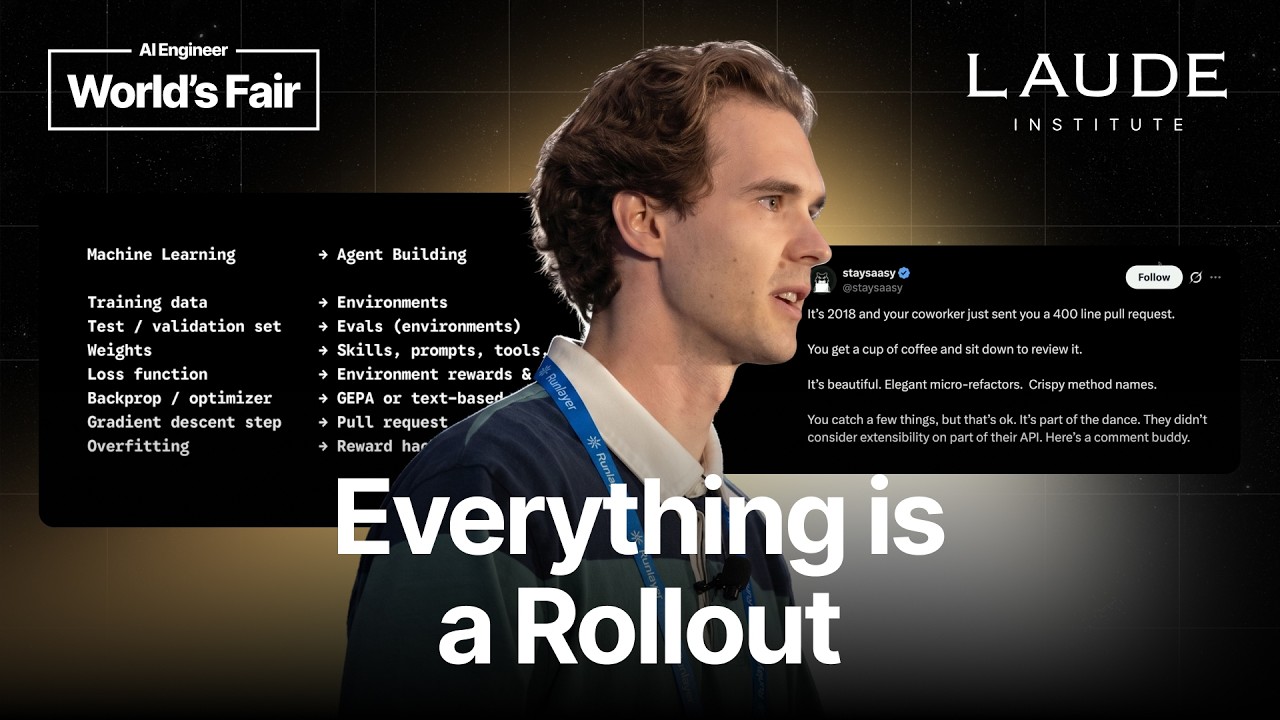
Alex Shaw presenting on stage at AI Engineer World's Fair
AI Engineer
Visual TL;DR
Agentic Coding RiseDriver
shift from traditional software engineering to agent-driven development
From the article 2 mentionsHe contrasted the software engineering practices of that era, exemplified by a humorous tweet about reviewing a 400-line pull request, with the current shift towards agentic coding.
Alex ShawCore
From the article 9 mentionsAlex Shaw from the Lode Institute presented at the AI Engineer World's Fair, delivering a talk titled "Everything Is a Rollout." The presentation focused on the Harbor framework, an agent evaluation and reinforcement learning environment framework, drawing parallels between traditional software engineering and the emerging field of agent development.
ML ParallelsContext
generated code treated as blackbox artifact requiring empirical evaluation
From the article 3 mentionsAn open-source framework for performing rollouts in parallel, supporting any agent, model, sandbox, or task.
Harbor FrameworkCore
From the article 9 mentionsAlex Shaw from the Lode Institute presented at the AI Engineer World's Fair, delivering a talk titled "Everything Is a Rollout." The presentation focused on the Harbor framework, an agent evaluation and reinforcement learning environment framework, drawing parallels between traditional software engineering and the emerging field of agent development.
Empirical EvaluationEffect
necessary for managing behavior and generalization of AI agents
From the article 8 mentionsGenerated code is best treated as a blackbox artifact whose behavior and generalization should be managed via empirical evaluation like with any ML model." Shaw extended this idea, claiming that "agent performance itself is best treated as a blackbox artifact."
Rollout ProcessContext
testing and deployment of AI agents mirroring ML development
From the article 6 mentionsThe Harbor rollout process involves passing a sandbox to an agent, which then runs until a stopping condition is met, producing a trajectory.
AI Agent DevelopmentOutcome
building and testing AI agents with robust evaluation tools
From the article 9+ mentionsThis fundamental shift, Shaw explained, means that agent development is more akin to machine learning than traditional software engineering.
Contents(4)

Alex Shaw from the Lode Institute presented at the AI Engineer World's Fair, delivering a talk titled "Everything Is a Rollout." The presentation focused on the Harbor framework, an agent evaluation and reinforcement learning environment framework, drawing parallels between traditional software engineering and the emerging field of agent development.

Alex Shaw: "Everything Is a Rollout" in AI Agent Evaluation - AI Engineer
Alex Shaw: "Everything Is a Rollout" in AI Agent Evaluation, AI Engineer

The Evolution of Software Engineering and the Rise of Agents

Shaw began by taking the audience back to 2018, a year marked by cultural milestones like the release of Avengers Infinity War and the rebranding of Musical.ly to TikTok. He contrasted the software engineering practices of that era, exemplified by a humorous tweet about reviewing a 400-line pull request, with the current shift towards agentic coding. He quoted Francois Chalet, who stated that "Agentic coding is a form of machine learning. Generated code is best treated as a blackbox artifact whose behavior and generalization should be managed via empirical evaluation like with any ML model." Shaw extended this idea, claiming that "agent performance itself is best treated as a blackbox artifact."

This fundamental shift, Shaw explained, means that agent development is more akin to machine learning than traditional software engineering. He illustrated this by comparing key machine learning concepts with their agent development counterparts:

  • Training data maps to environments.
  • Test and validation sets map to evaluations (also environments).
  • Model weights map to skills, prompts, tools, and the model itself.
  • Loss functions map to environment rewards and feedback.
  • Backpropagation/optimizers map to context-based optimization algorithms or running agents in loops.
  • Gradient descent steps map to pull requests.
  • Overfitting maps to reward hacking or overfitting within agent development.

Harbor: A Framework for Agent Evaluation

Shaw introduced Harbor as a solution to the need for new tools in agent development. Harbor is described as:

  • A format for specifying agentic environments.
  • An open-source framework for performing rollouts in parallel, supporting any agent, model, sandbox, or task.
  • A registry of popular training and evaluation environment sets, with hundreds already available.

The core concept of evaluating an agent, Shaw explained, relies on environments. An environment requires an instruction, a place for the agent to act (a sandbox), and a verifier to assess the outcome. Harbor standardizes environment specification with a file directory layout, promoting interoperability.

The Rollout Process and Use Cases

The Harbor rollout process involves passing a sandbox to an agent, which then runs until a stopping condition is met, producing a trajectory. This trajectory is then passed to a verifier, which generates rewards. These rewards are aggregated across multiple rollouts to form the evaluation dataset.

Shaw highlighted several use cases for the Harbor rollout process:

  • Evaluating Agent Product Building: Companies can use Harbor to test which coding agents or models perform best on their internal codebases and use cases.
  • Evaluating Agent Product Usage: Companies can assess how well agents interact with their products, particularly in headless modes, to improve product usability for AI.
  • Evaluating Agent-Powered Features: Assessing how agents enhance product features.
  • Evaluating Internal Process Automation: Automating internal company processes with agents.

He also demonstrated the command-line interface for Harbor, showcasing its ability to run benchmarks with multiple agents and models in parallel, emphasizing the importance of parallelization for tightening development loops and maximizing throughput.

The Ubiquity of Evals and Future Outlook

Shaw asserted that "every single company that uses computers" needs evaluations, as AI can automate processes and increase productivity. He quoted Satya Nadella, who stated, "If you want to build an agentic system, start with the eval that matters... and your ability to grade that outcome. And then say, I welcome all models." Shaw echoed this sentiment, noting that having a robust evaluation system empowers companies to consider any model without relying on third-party assurances.

The presentation concluded with a list of notable projects and integrations utilizing Harbor, including FrontierSuite, BankerToolBench, RuneBench, Scale Atlas, AutoAgent, AfterQuery, and LangChain, underscoring Harbor's growing significance as a common language for agent evaluation and development.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.