
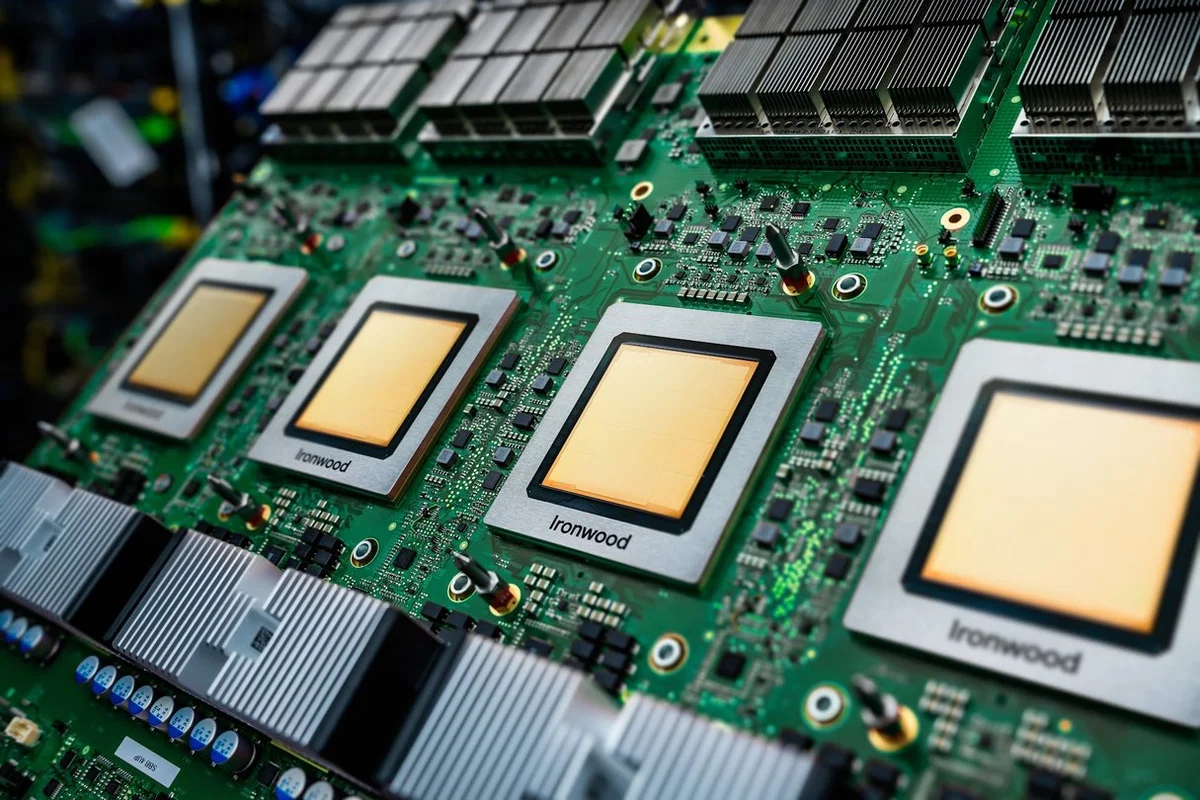
Google Cloud published 10 benchmark runs across Ironwood TPUs and NVIDIA Grace Blackwell GPUs. The MLPerf Training v6.1 results cover frontier pre-training and agentic reinforcement learning, built on its AI Hypercomputer architecture, Google Cloud said.
Pre-training is the headline.
MLPerf Training is an industry benchmark that measures time to train a model to a target quality score. Google Cloud said 8,192 seventh-generation Ironwood TPUs reached the DeepSeek-V3 target in 1.70 minutes. Scaling held to 96% efficiency up to 4,096 chips, Google Cloud said, which matters because efficiency usually falls as clusters grow.
Agentic reinforcement learning is the new test. It trains coding agents that generate code and learn from execution at the same time. Google Cloud said 640 Ironwood TPUs hit 0.765 accuracy against a 0.69 goal in 18.02 minutes on Qwen3.5-397B. Training chips waited under 3% of the time, Google Cloud said.
Google Cloud also rents NVIDIA hardware. Google Cloud said 256 NVIDIA GB300 GPUs in A4X Max Instances reached the DeepSeek-V3 target in 31.96 minutes. Five other runs used A4X and A4X Max systems with GB200 and GB300 GPUs on the agentic task, Google Cloud said.
NVIDIA answered from its own cloud stack. Its Vera Rubin NVL72 delivers up to 2x Blackwell Ultra performance in the same round, per the NVIDIA Technical Blog. That claim reframes Google Cloud numbers as a snapshot before Rubin systems scale.
StartupHub.ai data tracks NVIDIA, AMD and Intel as the reference vendors for AI training hardware, with NVIDIA setting the price for performance. Google Cloud changes that math by offering both Ironwood and Blackwell from one platform. Buyers can benchmark internal silicon against NVIDIA parts without changing clouds.
The caveat is scope. All times measure training from an official reference checkpoint to convergence, Google Cloud said, not full pretraining from scratch. Watch Ironwood quota and A4X Max pricing to see if lab speed becomes rented speed.




