TurboQuant: Supercharging AI Agent Retrieval with Compression

Shashi Jagtap of Superagentic AI introduces TurboQuant, a method to compress AI agent memory and embeddings, reducing usage by 5-8x with no quality loss.

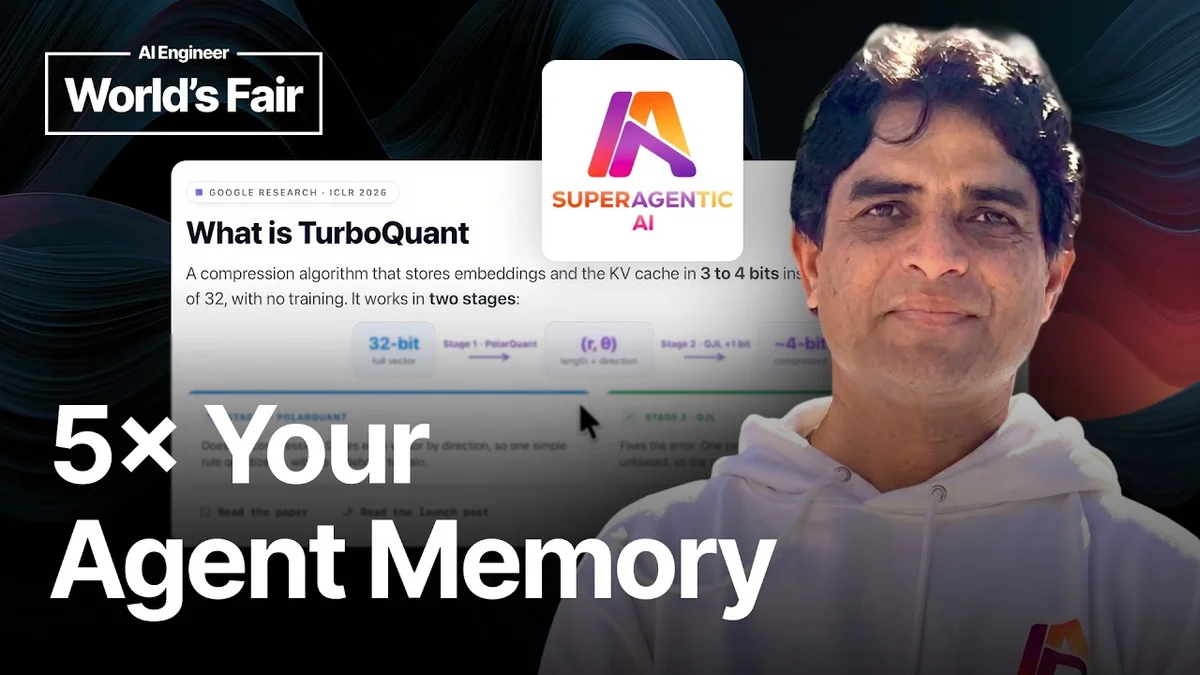
Presentation slide showing TurboQuant logo and concept
AI Engineer
Visual TL;DR
AI Agent Memory ChallengeDriver
KV cache and vector embeddings consume significant memory and compute
From the article 5 mentionsTurboQuant tackles this memory challenge through a two-stage compression algorithm that reduces the storage of embeddings and KV cache to 3 to 4 bits, all without requiring additional training.
Traditional Compression IssuesDriver
From the articleJagtap explained how traditional methods of compression often lead to a drop in quality or require extensive retraining, a trade-off that TurboQuant aims to overcome.
Introducing TurboQuantCore
a novel two-stage compression algorithm for AI agent memory
From the article 9+ mentionsShashi Jagtap, Founder of Superagentic AI, presented a novel approach called TurboQuant, designed to significantly enhance the efficiency of AI agents by turbocharging their retrieval capabilities.
Compresses Embeddings & KV CacheContext
reduces memory usage by 5-8x with no quality degradation
From the article 2 mentionsThe core problem addressed by TurboQuant lies in the substantial memory footprint and computational cost associated with large language models (LLMs) and their retrieval mechanisms, particularly the KV cache and vector embeddings.
Supercharges RetrievalEffect
enhances the efficiency and speed of AI agent operations
From the article 4 mentionsThe demo illustrated that while the baseline float32 index consumed 8.0 KB, the TurboQuant compressed index used only 1.6 KB, a 5x reduction, with retrieval quality preserved.
Practical ApplicationsContext
demonstrated in real-world AI agent scenarios and demos
From the articleThis practical example highlighted how easily TurboQuant can be integrated into existing RAG systems.
Key TakeawaysOutcome
developers can leverage TurboQuant for more efficient AI agents
From the articleJagtap provided three key takeaways for developers looking to implement TurboQuant:
Contents(5)

Shashi Jagtap, Founder of Superagentic AI, presented a novel approach called TurboQuant, designed to significantly enhance the efficiency of AI agents by turbocharging their retrieval capabilities. The core problem addressed by TurboQuant lies in the substantial memory footprint and computational cost associated with large language models (LLMs) and their retrieval mechanisms, particularly the KV cache and vector embeddings. Jagtap explained how traditional methods of compression often lead to a drop in quality or require extensive retraining, a trade-off that TurboQuant aims to overcome.

TurboQuant: Supercharging AI Agent Retrieval with Compression - AI Engineer
TurboQuant: Supercharging AI Agent Retrieval with Compression, AI Engineer

The Memory Challenge in AI Agents

Jagtap highlighted the critical issue of memory consumption in AI agents, especially those relying on retrieval-augmented generation (RAG) systems. Every token processed by an agent is cached in memory, forming the KV cache, which grows with each interaction. As the context window expands, so does the memory demand. On Mac devices, this problem is exacerbated as the model, cache, and vector index compete for a shared pool of RAM, often leading to performance degradation.

Embeddings, which are essentially lists of numbers representing data, are typically stored at 32-bit precision. However, Jagtap pointed out that for search operations, only the relative proximity of vectors matters, and a much lower precision, such as 3 to 4 bits, is often sufficient. Storing these embeddings at full 32-bit precision results in significant memory wastage, with estimates suggesting up to 5x more memory is used than necessary.

Introducing TurboQuant: A Two-Stage Compression Algorithm

TurboQuant tackles this memory challenge through a two-stage compression algorithm that reduces the storage of embeddings and KV cache to 3 to 4 bits, all without requiring additional training. The process involves two key stages:

  • Stage 1: PolarQuant - This stage focuses on compressing the data by quantizing each vector by its direction. It employs a simple rule-based quantization without needing a codebook for training, making it efficient and fast.
  • Stage 2: QJL - This stage addresses any errors introduced during the initial compression. By using an extra sign bit per number, QJL ensures that the compressed scores remain unbiased, preserving the ranking accuracy of the search results.

This innovative two-stage approach allows for significant memory reduction while maintaining the integrity of the search process.

Comparing TurboQuant with Alternative Approaches

Jagtap also drew comparisons between TurboQuant and other existing methods for memory optimization in AI agents:

  • Lower Precision (Quantization): Methods like FP16, INT8, or product-quantize vectors reduce precision but can sometimes lead to loss of information or require retraining.
  • Context Compaction: Techniques like dropping or summarizing old tokens in the KV cache can free up memory, but they risk losing crucial details.
  • Smaller Embeddings: Using fewer dimensions (e.g., via PCA) reduces storage but can also discard signal relevant to search.
  • Offloading to CPU or Disk: Moving computation or data off the GPU adds latency and can be slower.

TurboQuant stands out by offering a method that handles both KV cache and vector search compression with a single, data-oblivious approach, and critically, without the need for retraining or significant code changes.

Practical Application and Demo

The presentation included a live demonstration showcasing the effectiveness of TurboQuant. By swapping out a standard retriever for a TurboQuant-enabled one in a Pydantic AI agent, the memory usage was drastically reduced. The demo illustrated that while the baseline float32 index consumed 8.0 KB, the TurboQuant compressed index used only 1.6 KB, a 5x reduction, with retrieval quality preserved. This practical example highlighted how easily TurboQuant can be integrated into existing RAG systems.

Jagtap emphasized that the agent, documents, and the core query remain unchanged; only the retrieval layer is swapped. This simplicity of integration makes TurboQuant a highly accessible solution for developers looking to optimize their AI agents.

Key Takeaways for Developers

Jagtap provided three key takeaways for developers looking to implement TurboQuant:

  • Mindset: Focus on compression for ranking, understanding that search prioritizes the closest vector, not its exact representation. This principle is why TurboQuant works where other compression methods might fail.
  • Try TurboQuant: Experiment by swapping a vector store with TurboQuant and measuring RAM savings to see if it fits your use case. Rebuilding is not necessary.
  • Measure and Validate: Run recall and latency benchmarks on your own data to validate the performance. While defaults are good, fine-tuning the bit budget can yield further improvements.

The talk concluded with a call to action, encouraging the audience to try TurboQuant and experience its benefits in compressing memory while keeping the meaning intact.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.