
Artificial Intelligence

Spotify's Shivam Verma on LLMs and Personalization

Shivam Verma from Spotify discusses how LLMs are transforming personalization in recommendation systems, moving towards steerable and context-aware content discovery.

StartupHub.ai Staff

By StartupHub.ai Staff, reviewed by Daniel Singer, Editor

3 min read

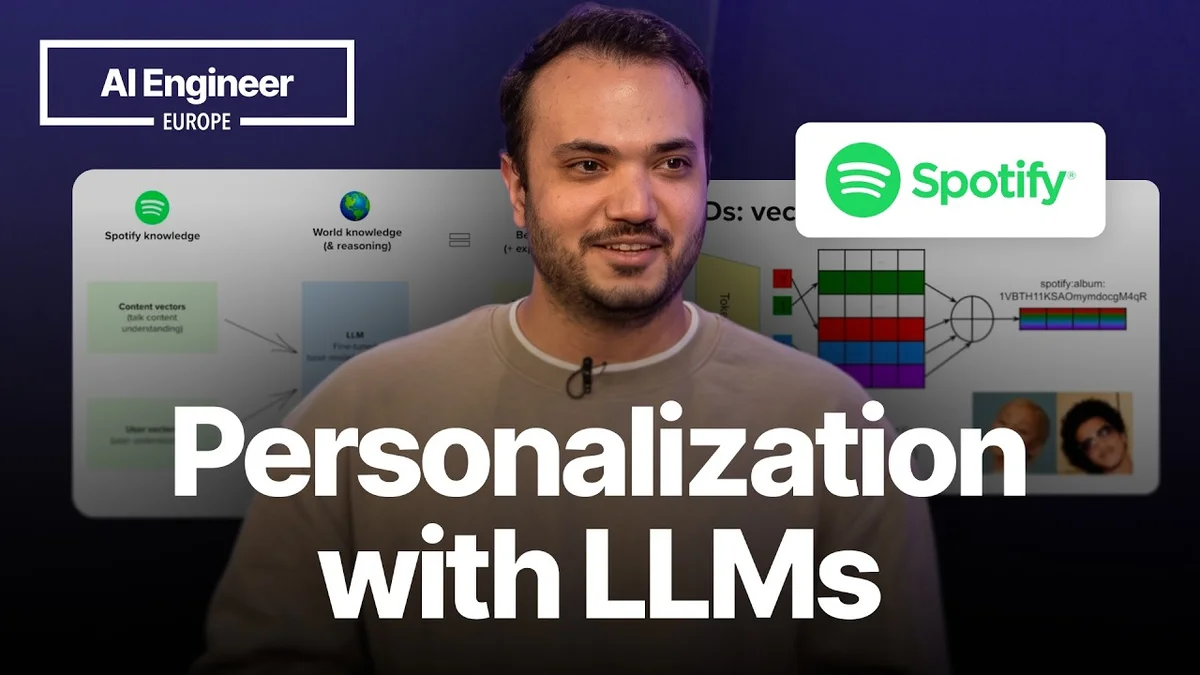
Shivam Verma from Spotify presenting on LLMs and personalization.
Image credit: AI Engineer EuropeCredit: AI Engineer
Visual TL;DR
Spotify's Shivam VermaCore
From the article 4 mentionsShivam Verma, Staff Machine Learning Engineer at Spotify, recently shared insights into how the music and podcast streaming giant is adapting its personalization strategies in the era of Large Language Models (LLMs).
Traditional RecsContext
multi-stage pipelines for candidate generation, ranking, and scoring
From the article 4 mentionsSpeaking at an AI Engineer Europe event, Verma detailed Spotify's journey from traditional recommendation systems to leveraging LLMs for more nuanced and personalized user experiences.
LLM EraDriver
advent of Large Language Models opens new personalization avenues
From the article 5 mentionsShivam Verma, Staff Machine Learning Engineer at Spotify, recently shared insights into how the music and podcast streaming giant is adapting its personalization strategies in the era of Large Language Models (LLMs).
Semantic IDsCore
leveraging semantic IDs and vector representations for content
From the article 5 mentionsTo bridge the gap between these user representations and the LLM's understanding of language, Spotify is employing techniques like semantic IDs and vector embeddings.
Understand Content/UsersCore
From the article 7 mentionsThe goal is to enable the LLMs to not only understand the semantic meaning of content but also to interpret user preferences and context more effectively.
Steerable RecommendationsEffect
moving towards steerable, context-aware content discovery
From the article 6 mentionsThis approach allows the models to process complex user context, including listening history, explicit prompts, and other implicit signals, to generate more relevant and steerable recommendations.
Personalized GenerativeOutcome
generative recommendations that are highly personalized
From the article 8 mentionsThe shift is from a strictly analytical approach to one that incorporates generative capabilities.
Contents(4)

Shivam Verma, Staff Machine Learning Engineer at Spotify, recently shared insights into how the music and podcast streaming giant is adapting its personalization strategies in the era of Large Language Models (LLMs). Speaking at an AI Engineer Europe event, Verma detailed Spotify's journey from traditional recommendation systems to leveraging LLMs for more nuanced and personalized user experiences.

Spotify's Shivam Verma on LLMs and Personalization - AI Engineer
Spotify's Shivam Verma on LLMs and Personalization, AI Engineer

From Traditional to LLM-Powered Personalization

Verma explained that Spotify's existing recommendation systems, referred to as "TradRecs," have long relied on multi-stage pipelines involving candidate generation, ranking, and scoring. These systems have been instrumental in delivering personalized playlists, search results, and content feeds across various media types like music, podcasts, and audiobooks. However, the advent of LLMs has opened new avenues for personalization, allowing for a more fluid and context-aware approach.

The core of this evolution lies in how Spotify represents its users and its vast catalog of content. Verma highlighted the use of user embeddings, which are sequences of numbers representing a user's taste and preferences. These embeddings are foundational to many of Spotify's personalized products. To bridge the gap between these user representations and the LLM's understanding of language, Spotify is employing techniques like semantic IDs and vector embeddings.

Leveraging Semantic IDs and Vector Representations

The process involves creating vector representations for content, enabling LLMs to understand not just the words but the underlying meaning and context. Similarly, user histories are transformed into semantic IDs, which are then fed into LLMs. This approach allows the models to process complex user context, including listening history, explicit prompts, and other implicit signals, to generate more relevant and steerable recommendations.

Verma illustrated this with an example where an LLM, equipped with user context like country, age, and listening history, can process a prompt like "Provide me with an episode I could listen next" and generate a personalized recommendation. This differs from traditional systems by allowing for a more conversational and interactive way to discover content.

The Role of LLMs in Understanding Content and Users

Verma emphasized that LLMs are being fine-tuned to understand Spotify's specific catalog and user data. This involves training the models on vast amounts of Spotify's internal data, including content vectors and user interaction logs. The goal is to enable the LLMs to not only understand the semantic meaning of content but also to interpret user preferences and context more effectively.

The shift is from a strictly analytical approach to one that incorporates generative capabilities. By translating user behaviors and content metadata into a common semantic space, LLMs can generate more creative and personalized recommendations. This includes features like "Taste Profile," where users can provide explicit feedback to further refine the model's understanding of their preferences.

From "Trad-Recs" to Steerable, Personalized Generative Recommendations

Verma concluded by summarizing the transition from traditional recommendation systems to a new era of "trad-generative" recommendations. He highlighted key takeaways:

  • Embeddings and semantic IDs are crucial building blocks for generative, LLM-native recommender systems.
  • Soft token approaches are showing significant promise in personalizing LLMs.
  • Traditional recommenders and sequential modeling remain important for real-world, real-time ranking, complementing LLM capabilities.

This evolution aims to provide users with more control and transparency in their content discovery journey, making the Spotify experience more engaging and personalized than ever before.

TopicsShivam VermaSpotifyLarge Language ModelsLLMPersonalizationRecommendation SystemsAIMachine Learning

StartupHub.ai StaffDaniel SingerWritten by StartupHub.ai Staff, Editorial teamReviewed by Daniel Singer, EditorAbout

StartupHub.ai Staff, Editorial team

The staff writers of StartupHub.ai, ranging from investment analysts to avid AI tool users, early adopters and critical enthusiasts. Backgrounds span engineering, business and the arts. We hold every piece to rigorous standards of research and review.

Daniel Singer, Editor

Daniel Singer is an AI expert who has been writing about, covering and building AI technology since 2018.

More from Daniel Singer

Get the free daily brief every morning

Every morning the day's AI news, new AI startups and new funding rounds. Free and takes a few minutes to read, unsubscribe at any time.

Join 64,000 other subscribers.

Test your Agent Readiness now

Paste your website. How well ChatGPT, Claude and the other agents can read and use a site, in about a minute.

The videos behind the news, one flip at a time

The feed mixes the videos from our articles with startup demos and you flip through them like TV channels for free with no signup.

