#GLM-5.3
9 articles with this tag
Most read in #GLM-5.3, last 30 days
Crusoe let AI tune GLM-5.3 serving
Crusoe let a dstack agent design GLM-5.3 serving on 64 GB200 GPUs, lifting throughput 134% and beating the OpenRouter median.
Prefix cache tips won't fix agents alone
Together AI and Ollama say prefix caching decides agent speed, but small prompt changes can wipe out the savings.
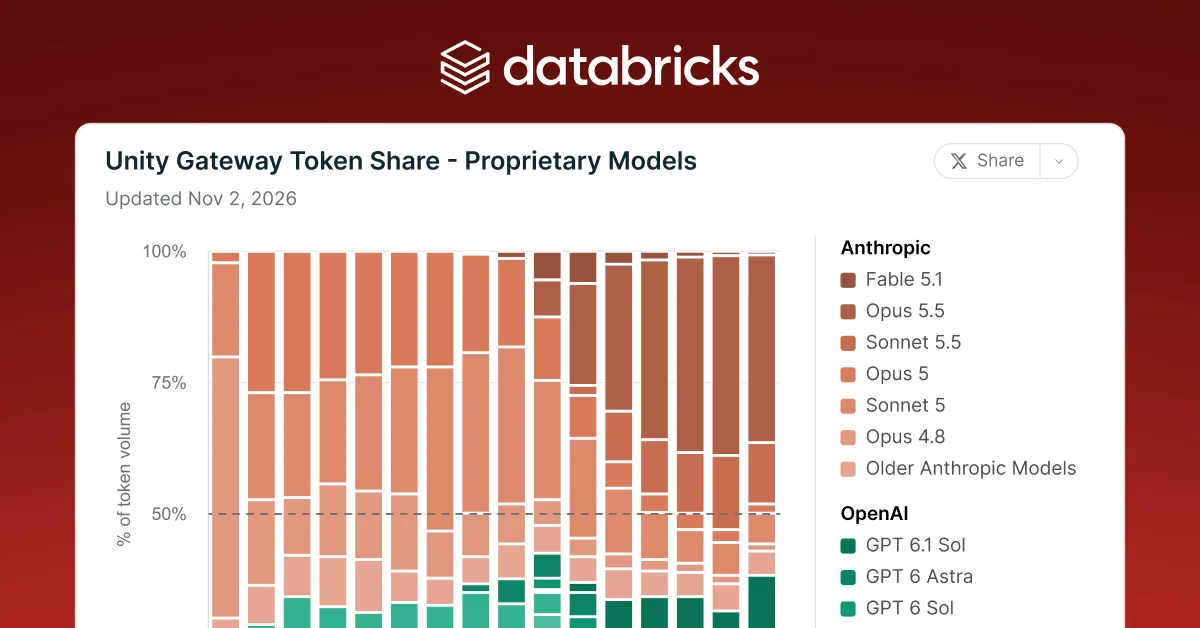
Databricks index shows enterprise AI churn
Databricks launched an AI Index tracking 10,000+ enterprises as Opus 5.5 surged and open-weight models hit 30.9% share.
Shared Flash Wins the KV Cache Fight
VAST Data says local SSDs strand KV cache hits and burn out, while shared NVMe pools scale sessions and wear.
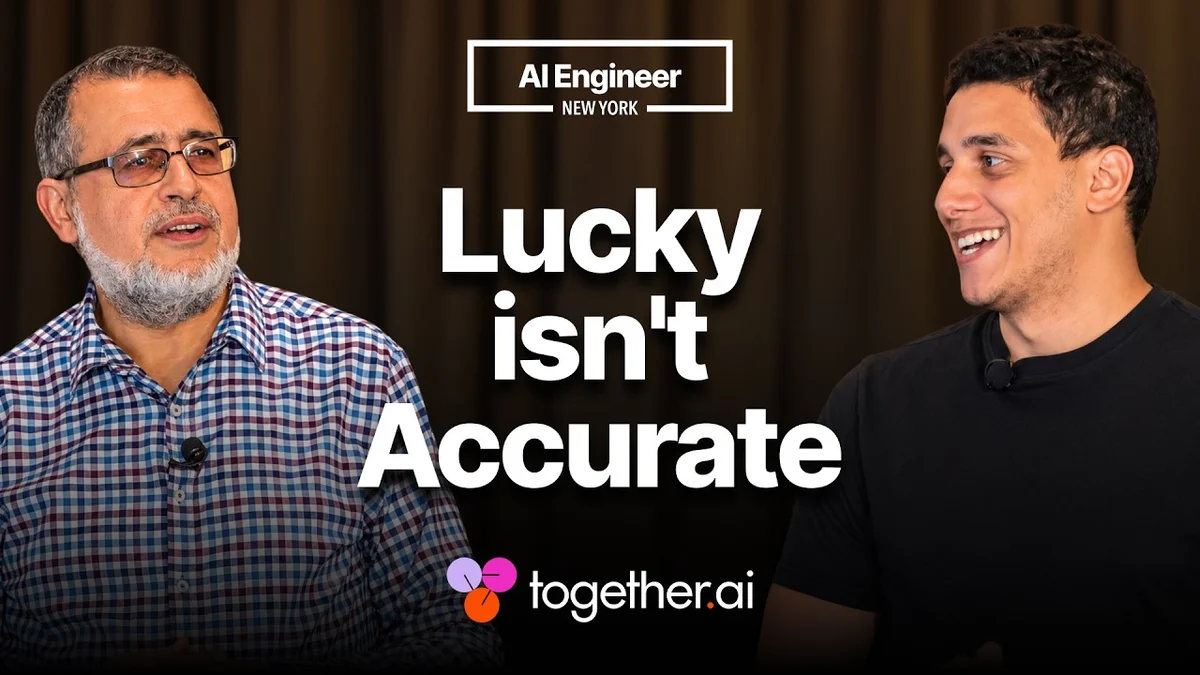
Costco forecast was right for wrong reasons
A Together AI demo nailed Costco profits within 4.4%, but auditor Omar El Mghari showed two errors canceled out.
Crusoe cuts GLM-5.3 startup to 31 seconds
Crusoe and NVIDIA cut GLM-5.3 startup from 8 minutes to 31 seconds by restoring GPU snapshots from local NVMe.
Mozilla AI sells open models by the month
Mozilla AI launched Otari Subscriptions to bundle open-weight coding models under one key and monthly price.
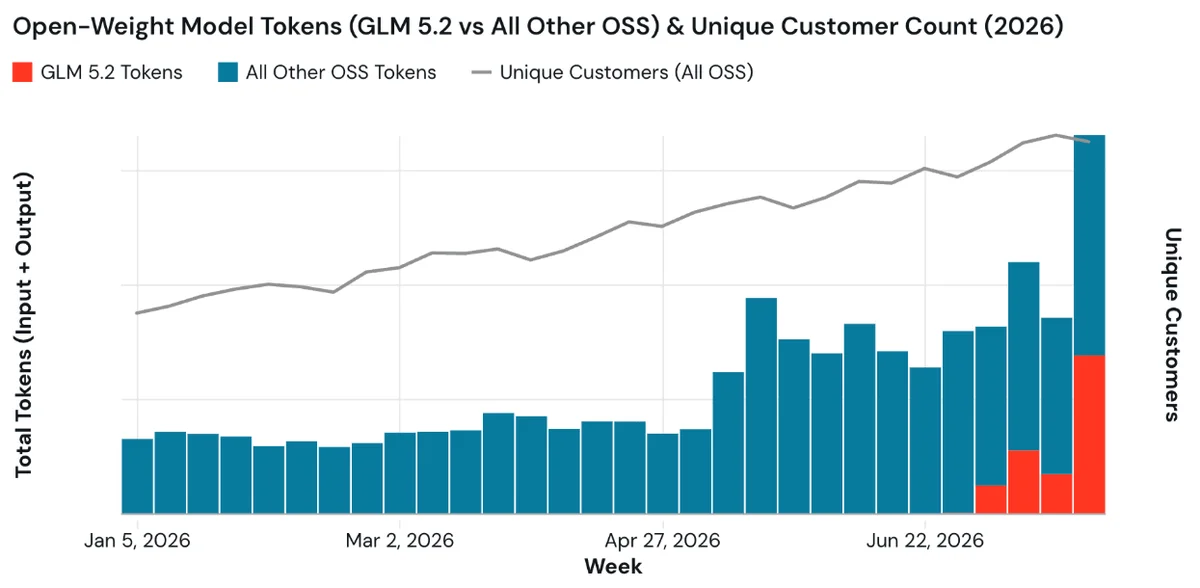
Databricks pushes open weights as frontier parity
Databricks field engineers cite seven pressures, including blocked malware analysis and retention shifts, to argue enterprises should run open-weight models via Unity Gateway.
Snowflake AI Cuts Costs With Smart Routing
Snowflake Cortex AI introduces Dynamic Model Routing and more open models to cut AI inference costs for businesses.

