#Cerebras
19 articles with this tag
a16z Bets on Gimlet Labs for Watts Crisis
a16z backs Gimlet Labs and its multi-silicon inference cloud that claims 10X gains per watt as hyperscaler capex nears $1 trillion.
Cerebras hits 10,000 tokens per second with CS5
Cerebras showed 4,400 TPS on CS4 and promised 10,000 TPS on CS5, with OpenAI already running its largest model 14x faster.
Cerebras Mikkeli AI data centre locks 165MW
Cerebras and Compute Nordic Finland will build a 165 MW AI data centre in Mikkeli, with 50 MW under construction under seven-year contracts.
Agentic Sites Puts Adobe's AI Speed to Test
Adobe's Carlos Sanchez demoed Agentic Sites that personalize AEM blocks in 1.1 seconds using Cerebras and Gemma 4, grounded on the site's own content.
Cerebras, Callosum Eye Agentic AI with New Partnership
Cerebras and Callosum partner to offer ultra-low-latency, heterogeneous agentic AI inference, expanding European reach and enabling new AI applications.
OpenAI Unveils GPT-5.6 Sol Ultrafast
OpenAI launches GPT-5.6 Sol Ultrafast mode, up to 14x faster, powered by Cerebras, enabling real-time AI for critical business tasks.

AMD, Cerebras Target Low-Latency AI
AMD and Cerebras announce a new partnership to deliver ultra-low latency AI inference solutions by combining AMD Helios and Cerebras Wafer-Scale Engine.

AMD and Cerebras Team on AI Inference
AMD and Cerebras unveil a new AI inference solution combining AMD Helios GPUs with Cerebras' Wafer-Scale Engine for ultra-low latency and high throughput.
Sarah Chieng: Fast Models Need "Slow" Developers
Cerebras' Sarah Chieng discusses how fast AI coding models like Codex Spark necessitate new developer habits and workflows for optimal results.

Cerebras IPO Soars 68% in Year's Biggest Public Debut
AI chipmaker Cerebras surged 68% after its IPO, the year's largest, with shares jumping from $185 to over $300, signaling strong investor confidence in its AI hardware technology.

Cerebras CEO on $5.55B IPO: "Extraordinary Demand"
Cerebras CEO Andrew Feldman discusses the company's landmark $5.55 billion IPO, highlighting the "extraordinary demand" for its AI chips and its vertically integrated strategy.
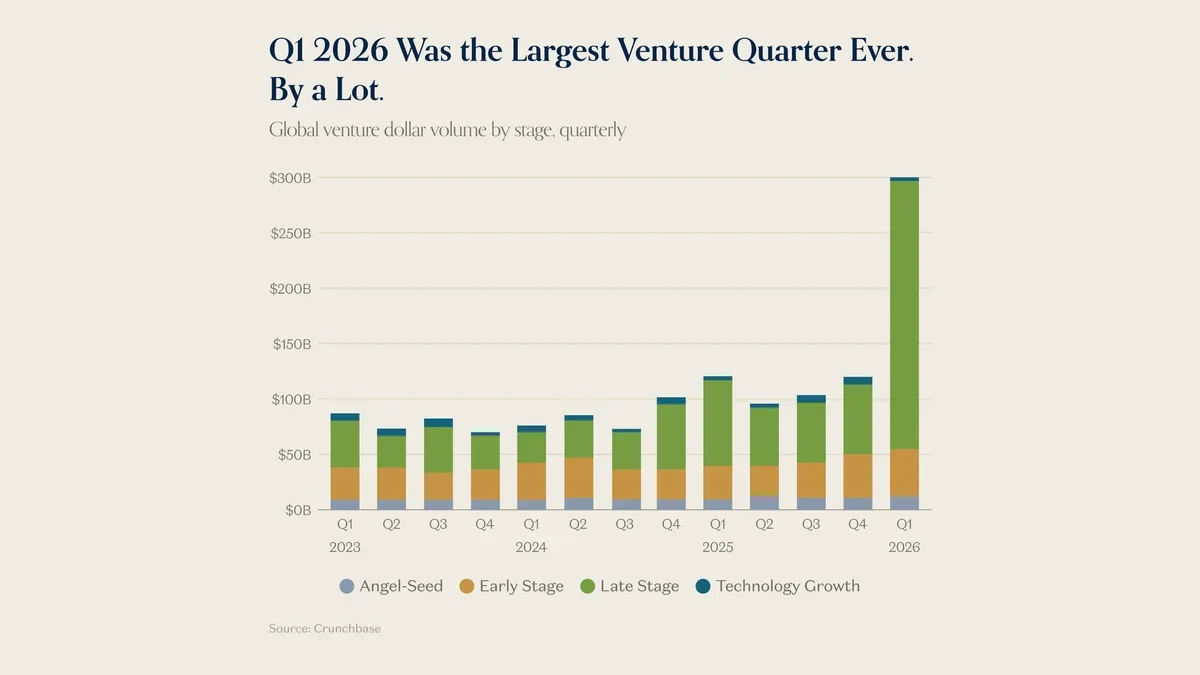
Venture Capital Hits $300B Quarter
Q1 2026 saw record venture investment, with AI driving mega-deals and hardware innovation, while construction lags technologically and geopolitical events impact global supply chains.
Speed Redefines AI Accuracy with Cerebras & OpenAI
Cerebras' wafer-scale engine boosts AI inference up to 15x faster than GPUs, enabling OpenAI's new reasoning models to achieve higher accuracy within latency budgets.
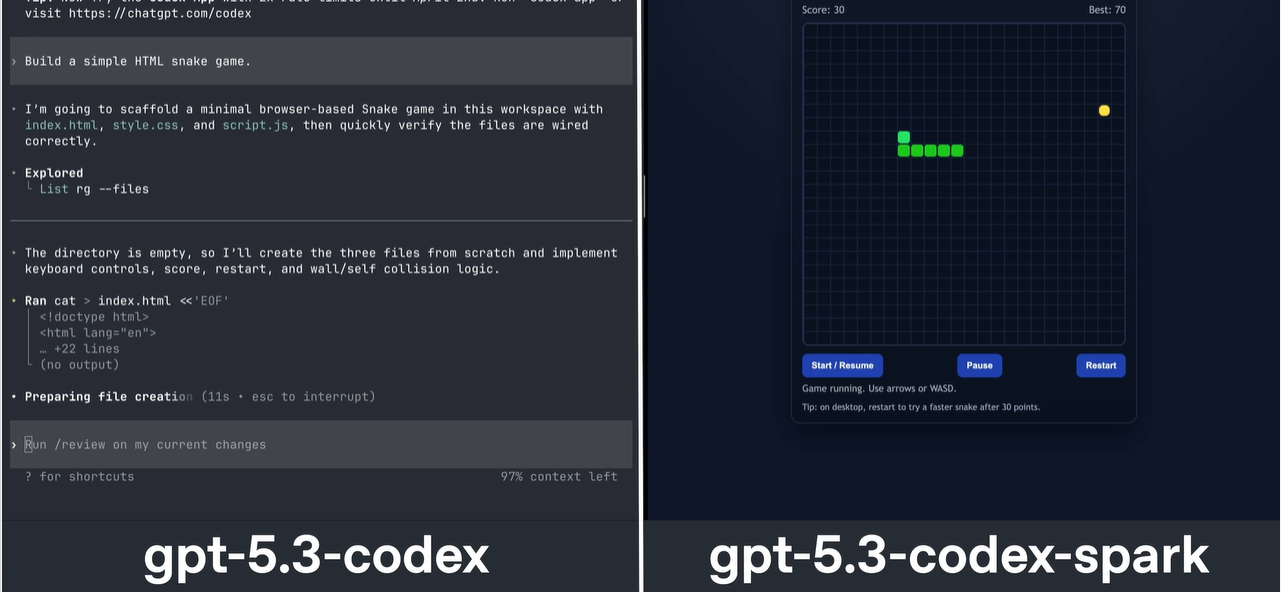
OpenAI Unveils GPT-5.3-Codex-Spark for Real-Time Coding
OpenAI releases GPT-5.3-Codex-Spark, an ultra-fast AI model for real-time coding, leveraging Cerebras hardware for instant feedback and rapid iteration.
OpenAI Cerebras Deal Targets Real Time AI Speed
OpenAI's Cerebras partnership prioritizes reducing AI inference latency, aiming for real-time interactions to drive deeper user engagement with deployed models.
SWE-1.5 model ends the AI speed vs. smarts tradeoff
The race for the best AI coding assistant has often forced a difficult choice on developers: do you want a model that’s fast, or one that’s smart?
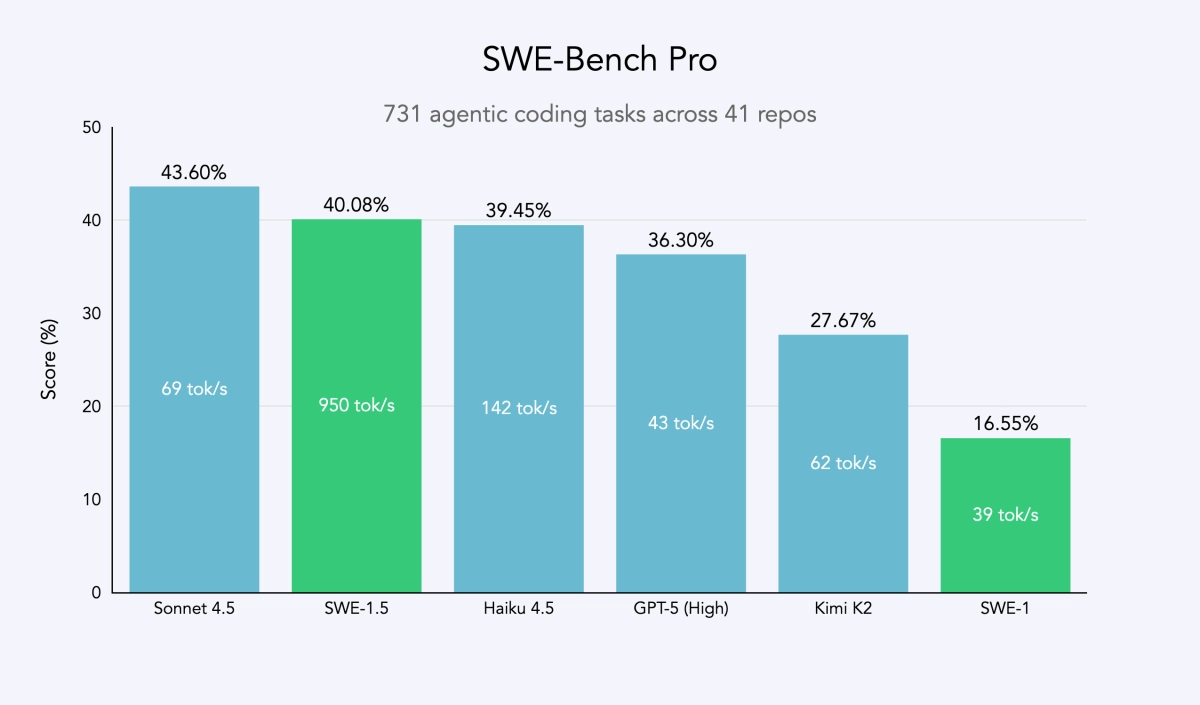
SWE-1.5 model ends the AI speed vs. smarts tradeoff
The race for the best AI coding assistant has often forced a difficult choice on developers: do you want a model that’s fast, or one that’s smart?
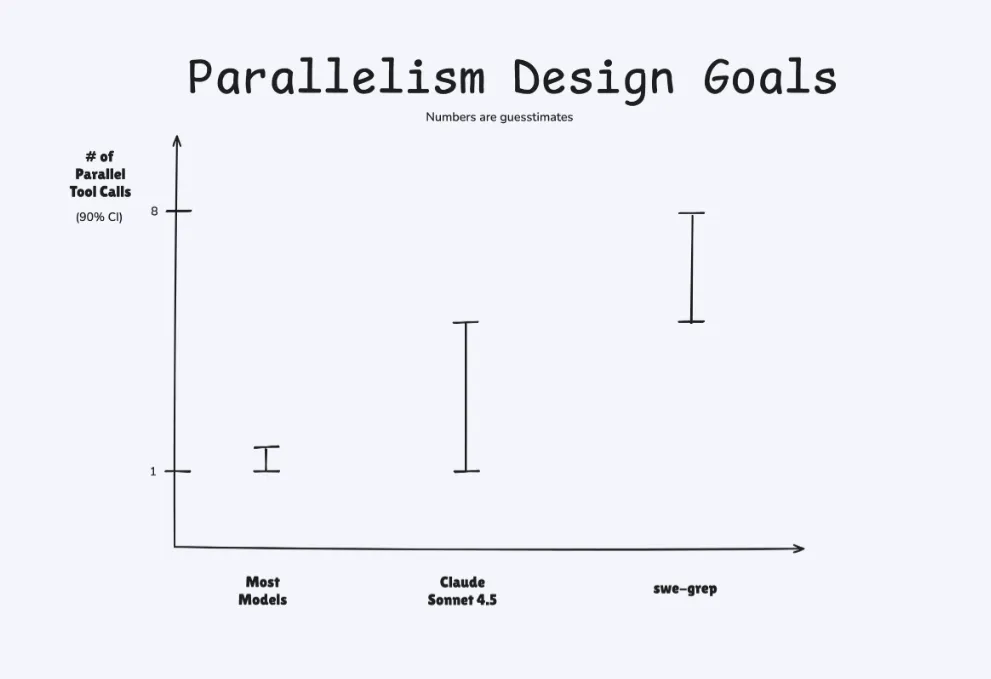
Cognition's New Bet on Fast Context Retrieval