#AI Inference
42 articles with this tag
Most read in #AI Inference, last 30 days
Cerebras, Callosum Eye Agentic AI with New Partnership
Cerebras and Callosum partner to offer ultra-low-latency, heterogeneous agentic AI inference, expanding European reach and enabling new AI applications.

Cerebras CS-4: AI Speed Leap
Cerebras launches CS-4 AI accelerator, claiming up to 30x faster inference than GPUs with new wafer-scale engine and rack design.
Cerebras Streams SUPERNOVA 2026 AI Event
Cerebras Systems will livestream its SUPERNOVA flagship event on August 18th, featuring new product announcements and demos for AI inference and production applications.

AMD Buys Taalas for AI Inference
AMD acquires AI inference silicon startup Taalas to boost performance and efficiency in its AI hardware roadmap.
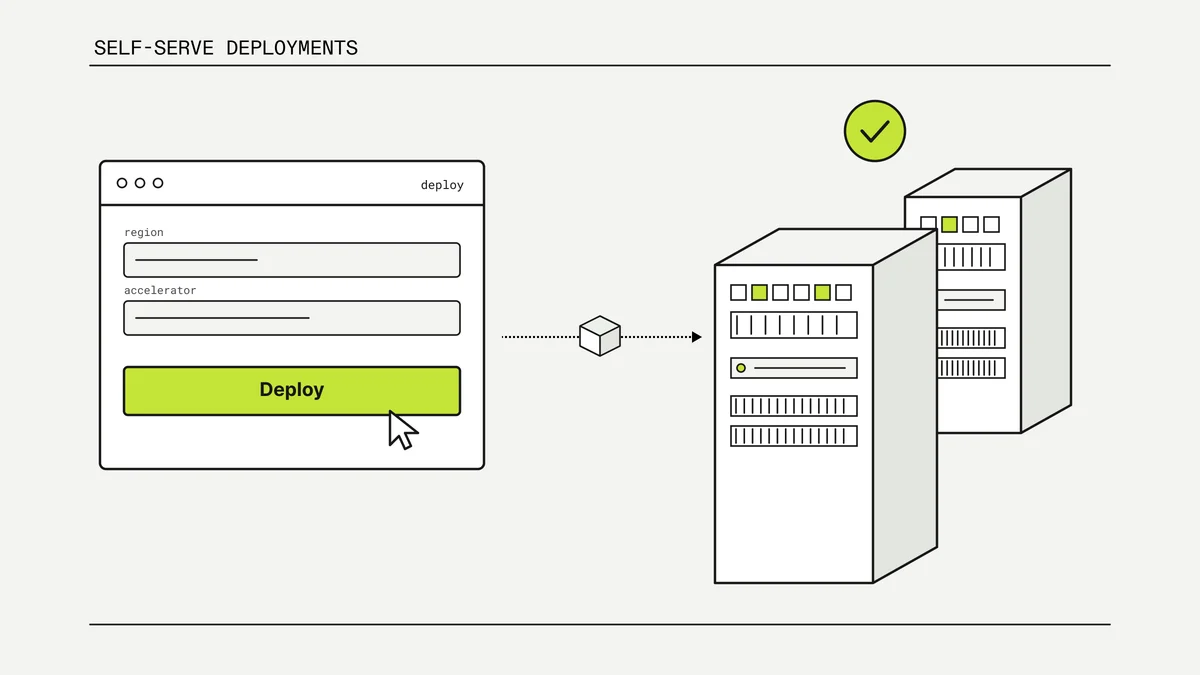
Crusoe Cloud Offers Dedicated AI Inference
Crusoe Cloud launches Self-Serve Deployments, offering dedicated AI inference capacity for growing applications, moving beyond shared serverless pools.

CoreWeave Dominates AI Inference Benchmarks
CoreWeave leads AI inference benchmarks for Moonshot AI's Kimi K2.6 model, showcasing superior speed and cost-efficiency through full-stack optimization.

OpenAI GPT-5.6: Smarter, Cheaper
OpenAI's new GPT-5.6 family cuts costs and boosts performance through significant inference and agentic harness optimizations.

AMD, Cerebras Target Low-Latency AI
AMD and Cerebras announce a new partnership to deliver ultra-low latency AI inference solutions by combining AMD Helios and Cerebras Wafer-Scale Engine.

AMD and Cerebras Team on AI Inference
AMD and Cerebras unveil a new AI inference solution combining AMD Helios GPUs with Cerebras' Wafer-Scale Engine for ultra-low latency and high throughput.

AMD Helios Powers Azure AI Inference
Microsoft is deploying AMD's Helios AI inference platform on Azure, integrating new EPYC CPUs and Instinct GPUs to power frontier models and AI services.
99.9% Uptime: What It Really Means for AI Inference
Achieving 99.9% uptime for AI inference means surviving data center failures, demanding active multi-facility traffic and direct infrastructure control.
Together AI adds Inkling multimodal model
Together AI integrates Inkling, a new multimodal AI model from Thinking Machines Lab, offering text, image, and audio processing with controllable reasoning.

Together AI Offers Predictable Inference
Together AI introduces Provisioned Throughput, offering reserved inference capacity for open models with token-based pricing and a 99% uptime SLA.

Mozilla.ai Unveils transcribe.cpp
Mozilla.ai launches transcribe.cpp, an open-source C/C++ library for fast, GPU-accelerated speech-to-text inference with broad model support.
OpenAI's Custom AI Chip with Broadcom
OpenAI unveils its first custom AI chip, 'Jalapeno', co-developed with Broadcom, aiming for 50% cost savings and enhanced AI inference performance.
Claude's Corner: Cumulus Labs, When the Inference Market Gets Outclassed by CUDA Kernels
Most GPU clouds rent H100s, wrap vLLM, and call it a product. Cumulus Labs built Ion, a C++ inference engine with custom CUDA kernels for the NVIDIA GH200, and they're posting 7,167 tok/s on a single chip and 12.5-second cold starts. Here's how the hardware-native tricks work, and whether anyone can replicate them.
Claude's Corner: Piris Labs, Inference at Light Speed, and the Memory Wall Nobody's Talking About
Piris Labs (YC W2026) is replacing copper data center interconnects with photonic CXL to break the GPU memory wall, delivering 5x lower latency and 2x lower cost per token. A deep-dive on the hardest-to-replicate startup in the W2026 batch.
Coding Agent Inference Benchmark Revealed
Together AI unveils a new benchmark for coding agent inference, highlighting performance under real-world load and significant cost advantages.
Together AI Taps Blockchain for Cheaper AI
Together AI and Pearl Research Labs are integrating blockchain to cut AI inference costs, offering discounted model access subsidized by cryptocurrency mining.
Together AI: Deploy Any Hugging Face Model Instantly
Together AI's Dedicated Container Inference lets developers deploy any Hugging Face model instantly, bypassing complex setups and accelerating AI experimentation.
Superlinked's Filip Makraduli on Small Model Inference Infrastructure
Filip Makraduli of Superlinked discusses the critical need for robust small model inference infrastructure, highlighting Superlinked's open-source solution.
AI Compute: The Bottleneck for Startup Scaling
Basen CEO Tuhin Srivastava discusses the critical role of AI inference infrastructure and the challenges startups face in scaling AI models.
Intel's AI Chip Demand: A Boon for Semiconductor Stocks?
Intel CEO Pat Gelsinger discusses the surging demand for Intel CPUs in AI inference and the company's strategy to leverage its integrated hardware offerings and partnerships for growth.

Orbital aims for space AI data centers
Orbital plans its first test mission for space-based AI data centers in 2027, aiming to overcome Earth's power constraints.
llm-d Enters CNCF Sandbox
The llm-d project's entry into the CNCF Sandbox marks a pivotal moment for cloud-native AI inference and open infrastructure.
OpenAI Cerebras Deal Targets Real Time AI Speed
OpenAI's Cerebras partnership prioritizes reducing AI inference latency, aiming for real-time interactions to drive deeper user engagement with deployed models.
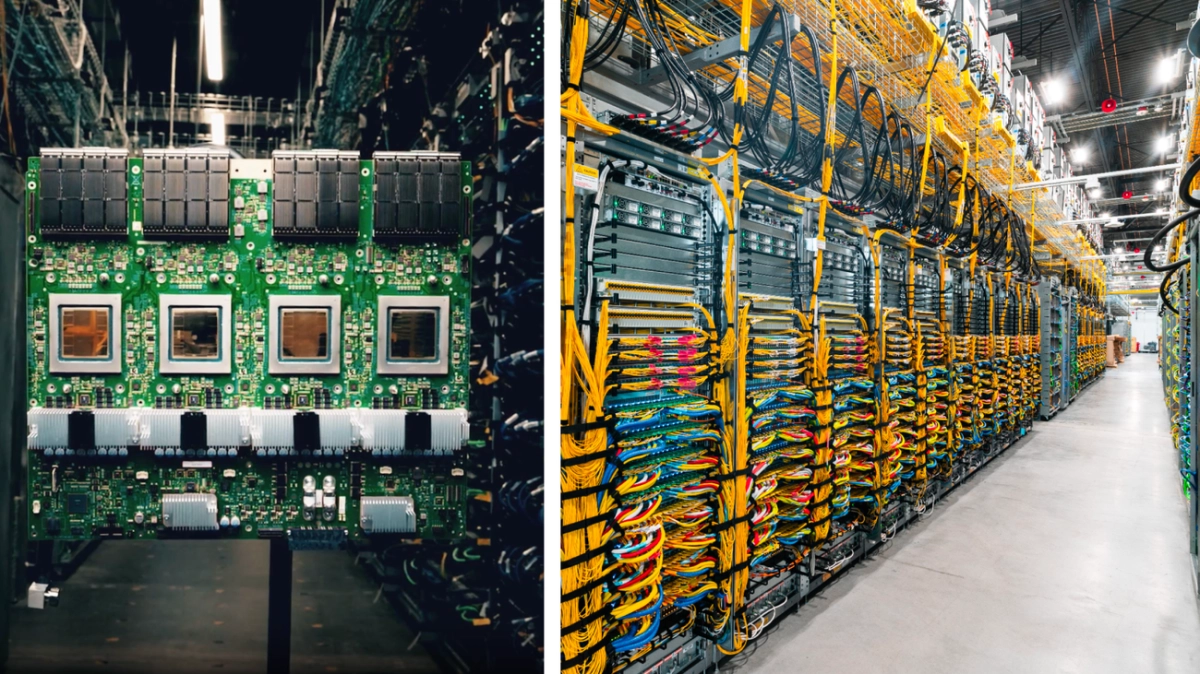
Google TPU Ironwood: Inference Powerhouse Arrives
Google Cloud’s AI Storage Strategy: Optimizing Performance and Cost
vLLM Solves the AI Model Serving Conundrum at Scale

Google Cloud Unveils Blueprint for Reliable, Scalable AI Inference
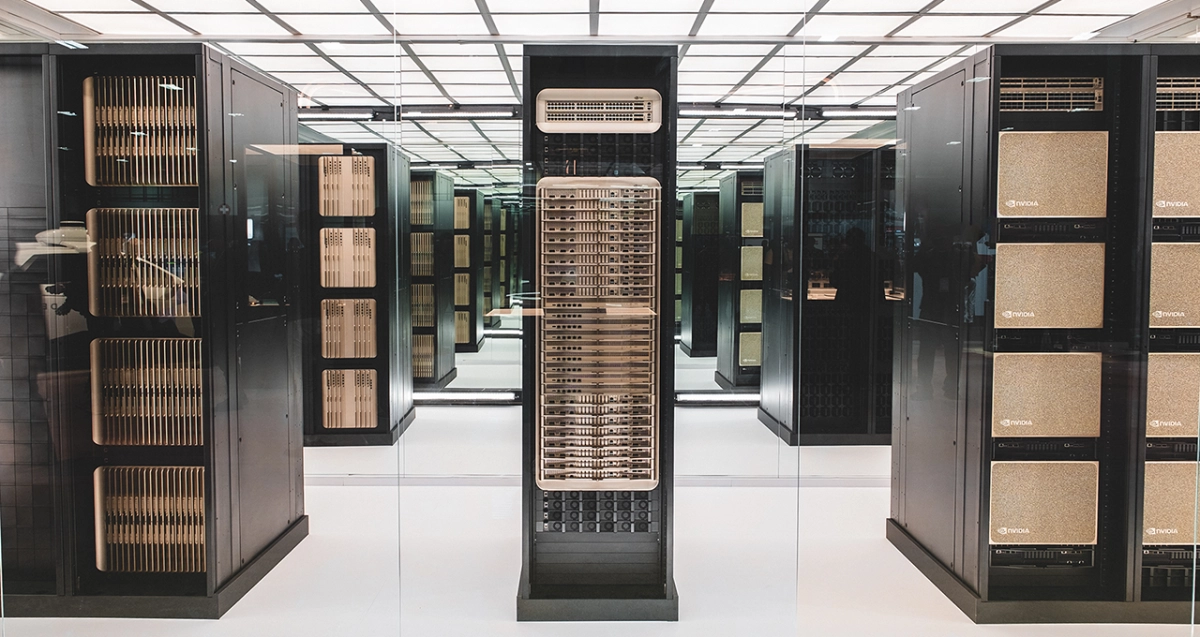
NVIDIA Dynamo AI Inference Scales Data Center AI
Impala AI Targets LLM Inference Costs with $11M Seed
Fireworks AI raises $250M to advance its AI inference platform
Tensormesh exits stealth with $4.5M to slash AI inference caching costs
The generative AI gold rush has an expensive secret: running the models costs a fortune.
Tensormesh exits stealth with $4.5M to slash AI inference caching costs
The generative AI gold rush has an expensive secret: running the models costs a fortune.
Qualcomm’s Bold AI Inference Play Challenges NVIDIA Dominance
Blackwell AI Inference: NVIDIA's Extreme-Scale Bet
Groq Secures $750M Investment to Expand the American AI Stack

NVIDIA Details SMART Framework for AI Inference at Scale
NVIDIA has outlined its comprehensive strategy for optimizing AI inference performance at scale, introducing the "Think SMART" framework as a guide for enterprises building and operating "AI factories."
NVIDIA Dynamo Redefines AI Inference Economics
Chalk Secures $50M Series A to Revolutionize AI Inference
Making Machine Learning Inference Meet Real-World Performance Demands
FPGAs offer the configurability needed for real-time machine learning inference, with the flexibility to adapt to future workloads. Making these advantages accessible to data-scientists and developers calls for tools that are both comprehensive and easy to use. Daniel Eaton, Sr Manager, Strategic Marketing Development, Xilinx


