UC Berkeley PhD Student Challenges AI Evaluation Methods

Parth Asawa, a PhD student at UC Berkeley, argues that current AI evaluation methods are insufficient for measuring continual learning and calls for a new benchmark approach.

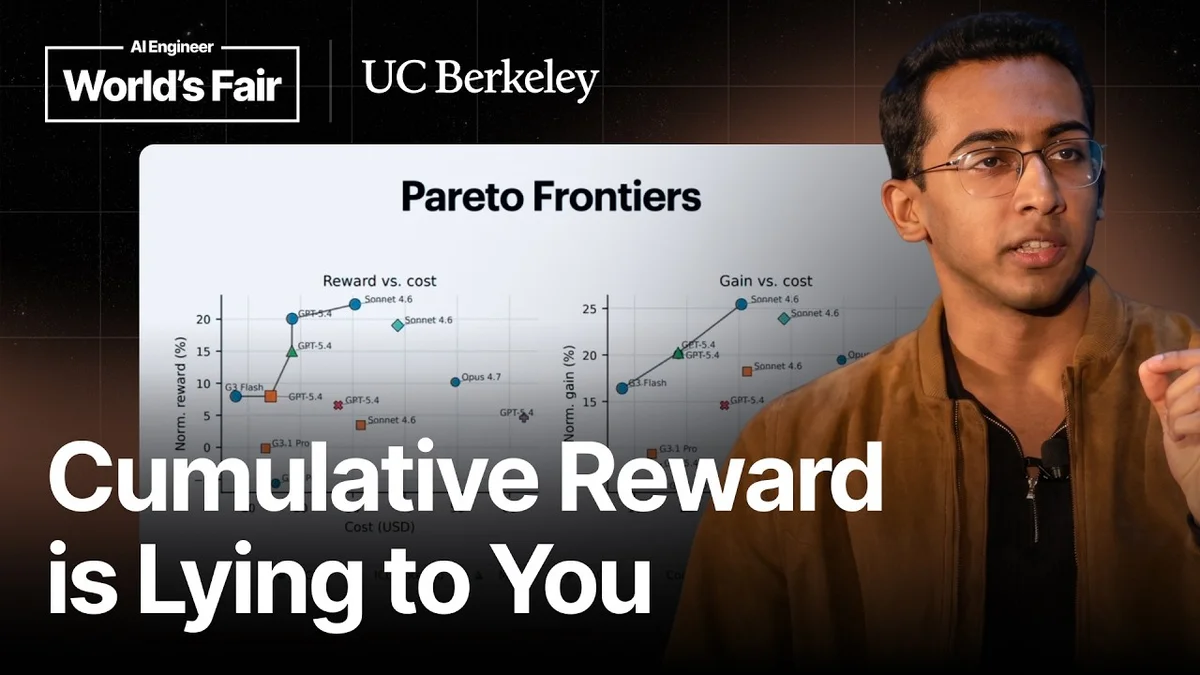
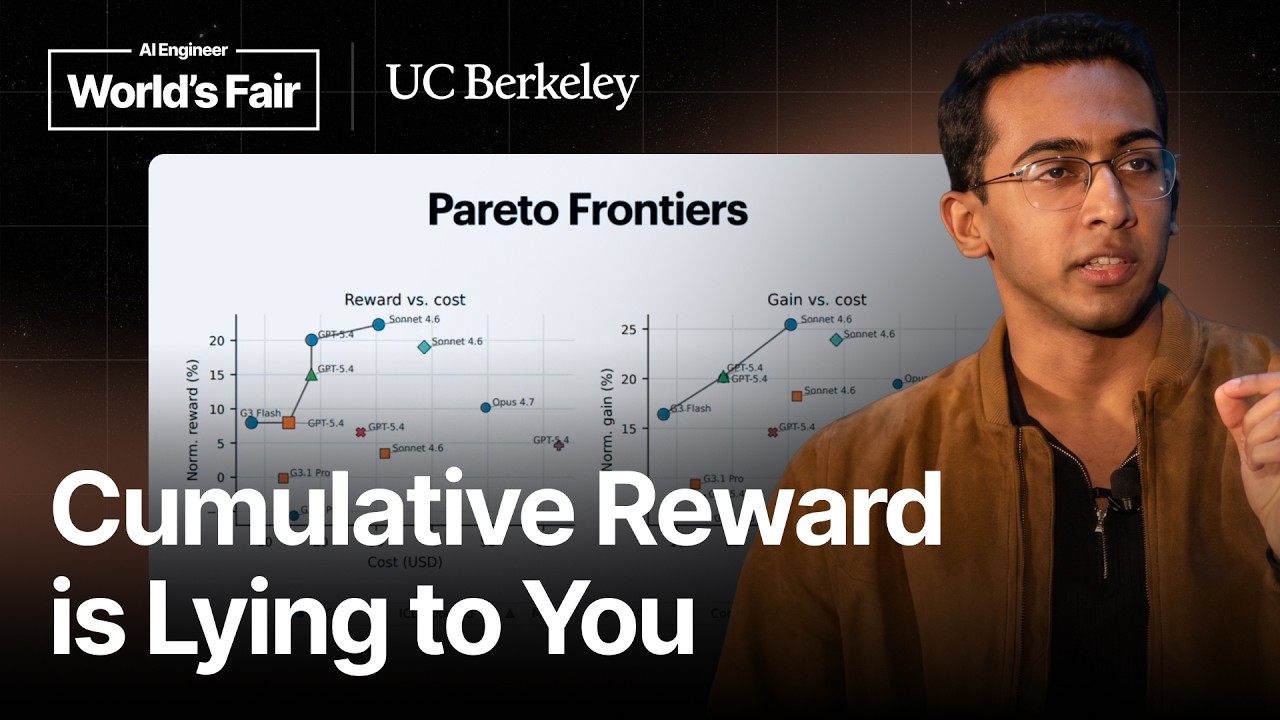
Parth Asawa speaking at a podium during the AI Engineer World's Fair
AI Engineer
Visual TL;DR
Parth Asawa (UCB PhD)Core
UC Berkeley PhD student challenges current AI evaluation methods for LLMs
From the articleAt the AI Engineer World's Fair, Parth Asawa, a PhD student at UC Berkeley, presented a critical look at how artificial intelligence, particularly large language models (LLMs), are evaluated.
Rethink EvaluationContext
critical look at how large language models are currently evaluated
From the article 3 mentionsAsawa highlighted how the typical evaluation of LLMs involves presenting them with a series of independent tasks.
AI Engineer FairCore
From the articleAt the AI Engineer World's Fair, Parth Asawa, a PhD student at UC Berkeley, presented a critical look at how artificial intelligence, particularly large language models (LLMs), are evaluated.
Current AI BenchmarksDriver
evaluate LLMs on isolated tasks, ignoring past experiences and learning
From the article 5 mentionsAsawa proposed three key criteria for designing effective continual learning benchmarks:
Fails Continual LearningDriver
this method cannot measure how models learn and adapt over time
From the article 9+ mentionsAsawa argued that the current approach, which often treats each task in isolation, fails to measure a crucial aspect of intelligence: the ability to learn and adapt over time, a concept known as continual learning.
Need New BenchmarkEffect
calls for a new approach to truly assess models' learning ability
From the article 4 mentionsShared Structure: To enable improvement from prior experience, tasks need to have underlying shared latent structures that models can exploit.
True Learning MeasureContext
From the article 3 mentionsHe contrasted this with what a true measure of learning ability should look like: performance that improves as a function of prior experience, rather than a scattered, inconsistent performance.
Contents(4)

At the AI Engineer World's Fair, Parth Asawa, a PhD student at UC Berkeley, presented a critical look at how artificial intelligence, particularly large language models (LLMs), are evaluated. Asawa argued that the current approach, which often treats each task in isolation, fails to measure a crucial aspect of intelligence: the ability to learn and adapt over time, a concept known as continual learning.

UC Berkeley PhD Student Challenges AI Evaluation Methods - AI Engineer
UC Berkeley PhD Student Challenges AI Evaluation Methods, AI Engineer

The Limitations of Current AI Benchmarks

Asawa highlighted how the typical evaluation of LLMs involves presenting them with a series of independent tasks. This method, he explained, is akin to asking a model to restart from scratch every single time, fundamentally ignoring its past experiences and learning capabilities. This approach is insufficient for assessing how well models can truly learn and improve from prior interactions.

He contrasted this with what a true measure of learning ability should look like: performance that improves as a function of prior experience, rather than a scattered, inconsistent performance. Asawa defined continual learning as "sample efficient, online learning that is stable over long horizons." This involves retaining information without forgetting while simultaneously adapting to new data.

Rethinking Continual Learning Evaluation

The current paradigm in LLM training involves offline processes where models are trained on vast datasets and then deployed as frozen checkpoints. Continual learning aims to change this by enabling models to learn and update their parameters over time. Asawa discussed various approaches being explored, including in-context learning, external memory stores, and updating model weights directly.

However, his core argument was that the field is not adequately evaluating these capabilities. He stressed that if continual learning is not about "point capabilities," then the evaluation methods must change to reflect this. Asawa proposed three key criteria for designing effective continual learning benchmarks:

  • Headroom: Tasks must require online adaptation or learning, meaning models shouldn't be able to perform well by simply relying on offline training on that specific data.
  • Shared Structure: To enable improvement from prior experience, tasks need to have underlying shared latent structures that models can exploit.
  • Learning Mechanism: There must be a signal within the environment, such as rewards, error messages, or textual feedback, that guides the model's learning process.

Asawa also elaborated on the metrics used for evaluation, emphasizing the importance of the 'gain' metric. Gain is calculated as the difference between stateful reward (where the model can maintain state) and stateless reward (where the model is reset between tasks). This metric helps to isolate the actual benefit derived from accumulated experience, rather than just reflecting the base model's initial capability.

The Continual Learning Bench 1.0 and Failure Modes

Asawa introduced the Continual Learning Bench 1.0, a benchmark suite featuring tasks from six different domains, including signal processing, software engineering, epidemiology, game playing, database exploration, and sales prediction. Each task is designed with specific reward metrics and validated by domain experts to ensure realism and learnability.

He then discussed observed failure modes in continual learning, categorizing them into stability and plasticity issues. Stability failures occur when models fail to retain new information, while plasticity failures happen when models cannot adapt to new information. He provided examples from the sales prediction task (demonstrating a stability failure) and the epidemiology task (illustrating a plasticity failure) to highlight these concepts.

Challenging the Status Quo in AI Research

Reflecting on broader implications, Asawa suggested that the current LLM training stack, which has evolved over years, might not be optimally designed for continual learning. He posed the question of whether the field is falling into a sunk cost fallacy by trying to adapt existing methods rather than redesigning models from the ground up with continual learning as a primary objective.

Furthermore, Asawa called for a re-evaluation of how AI research is conducted as a whole, touching upon issues of open science, power consolidation, and safety. He encouraged greater involvement in reimagining the future of AI research institutions and open science practices.

The presentation concluded with a summary of the key takeaway: "Continual learning doesn't look like point capabilities. We need to measure it the right way to optimize for the right objective as a field." This sentiment underscores the need for a fundamental shift in how AI’s learning abilities are assessed and developed.

© 2026 StartupHub.ai. All rights reserved. You may not republish this article in full without a license. Search engines and AI research tools may crawl and summarize for reference. Bulk reproduction or model training requires a license. See our terms.
Daniel Singer

Written by

Daniel Singer

Editor, StartupHub.ai

Daniel Singer is the editor of StartupHub.ai, a technology expert and thought leader on AI and its applications across sectors, from fintech and healthcare to developer tooling and consumer software. He writes and tests the tools covered here thoroughly and regularly, and built StartupHub.ai to give founders, operators and buyers a clearer read on what they are actually being sold.