


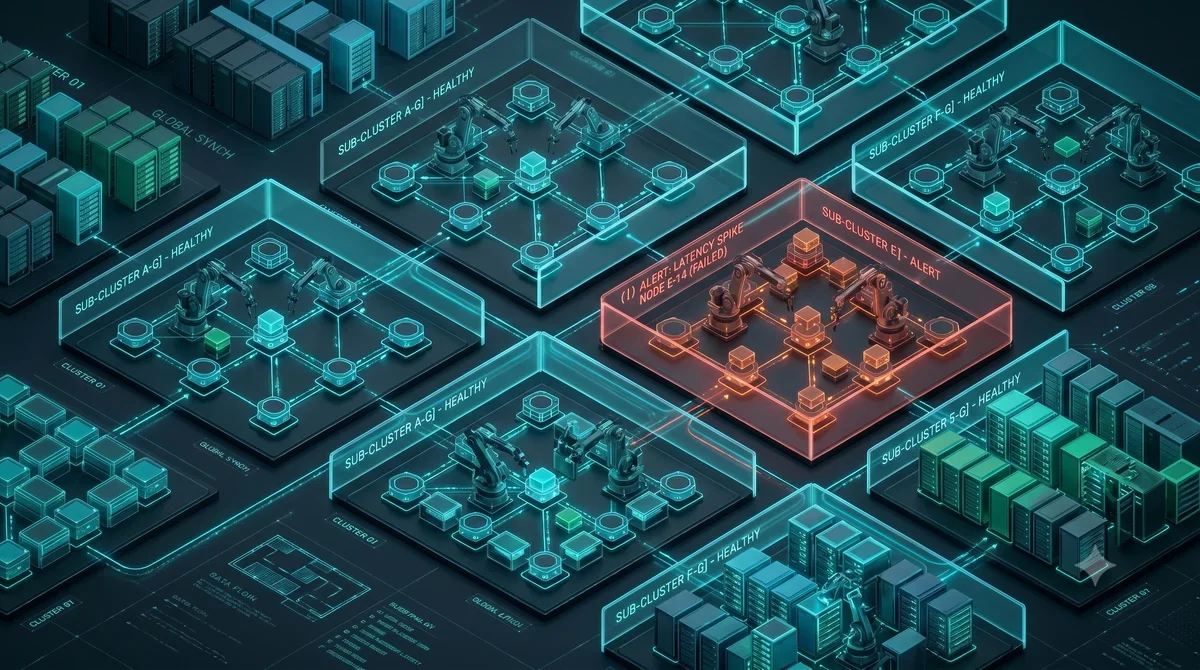
Uber Engineering rebuilt how M3DB places shards at scale, and the M3DB subcluster placement algorithm walls off failure domains by design.
The old sharded algorithm let any shard land on any node.
The only hard rule was that replicas couldn't share an isolation group, like a rack or zone. In permissive setups with one node per group, any change touched O(N) nodes. Even with zones matched to RF=3, a node still shared shards with up to 66.67% of the cluster.
That created two problems. A single node failure fanned out to (n-1)/n of the cluster. Maintenance had to be serialized because nodes in different zones still overlapped on shards.
How the new placement actually works
Subclusters partition nodes into fixed-size groups, each owning a distinct slice of the shard space with no overlap in steady state. Think of sealed aisles in a warehouse: a spill stays in one aisle instead of flooding the floor.