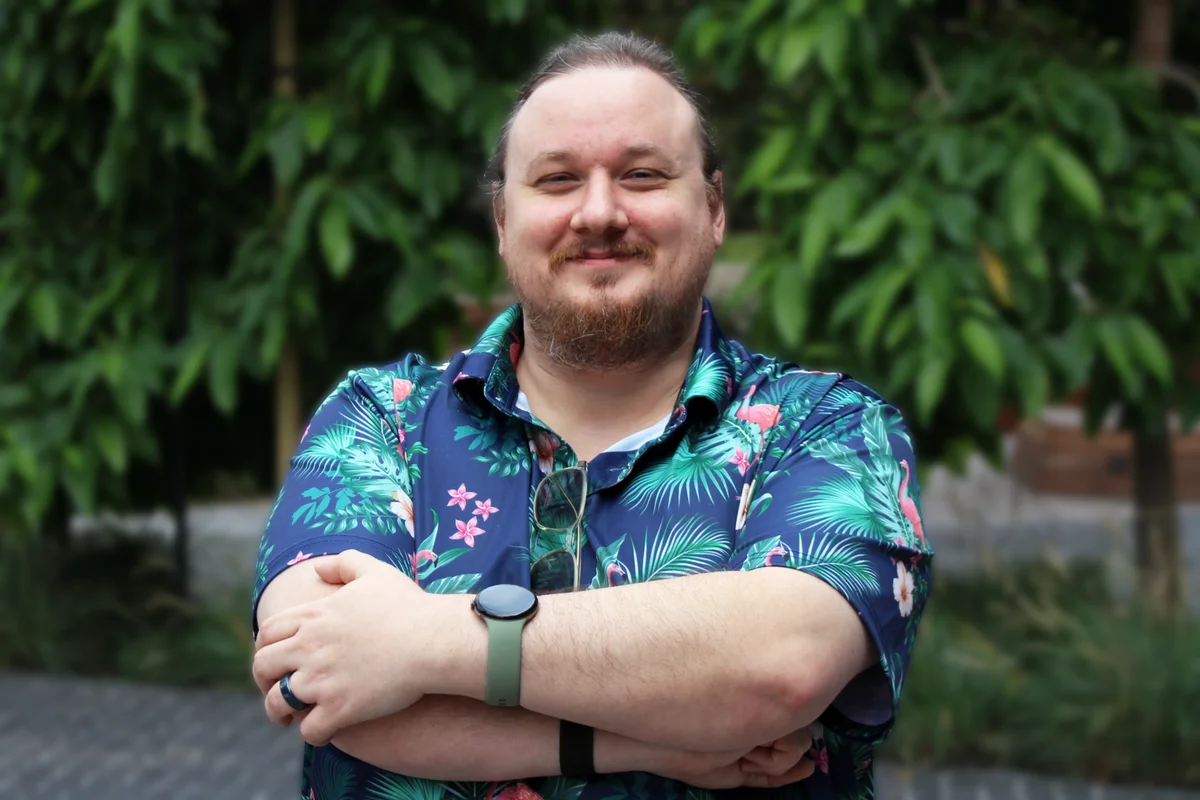
NVIDIA Blog profiles Chris Alexiuk, a Toronto-based senior product research engineer in deep learning at NVIDIA, as its loudest champion for open weights and for Nemotron 3.5 Lightning in particular.
His pitch is simple: openness is not a feature, it is the precondition.
Alexiuk, who teaches thousands on YouTube and posts as llm_wizard and Joe Nemotron, tells NVIDIA Blog that democratized intelligence requires access to weights, data and training recipes, and he calls Nemotron a magical library where you are a wizard in search of prepared spells. He frames Nemotron 3.5 Lightning for repetitive, high-frequency execution work, while Nemotron Ultra targets long-running autonomous agents and enterprise research, and he traces his own path from a computational physics class at Trent University to a webcam classifier that pinged him when a Yellow-Faced Gray Budgerigar hopped into frame during game sessions.
Nemotron 3.5 Lightning is positioned for builders who want to fine-tune, evaluate and ship agents locally, and outside specs note it is a text-only reasoning model from NVIDIA that can use tools, per Ziva docs, which matters more than branding when you are wiring it into production workflows.
That local-first promise moves pressure to the hardware layer.
When a capable open model can run on a laptop, as Alexiuk demonstrates, startups selling inference do not compete on model access, they compete on memory, latency and tooling. Groq with its LPU, Cerebras with wafer-scale inference, and Tenstorrent with RISC-V based accelerators all chase the same bottleneck: making high-frequency reasoning cheap enough to leave running.
StartupHub.ai data shows open-weight deployment and local fine-tuning remain the most requested capabilities among AI-hardware startups we track, which keeps demand tilted toward chips that handle long contexts and tool calls without cloud round trips.
The limit is still physical. Open weights do not remove VRAM requirements or the need to evaluate and guard the model yourself.
If Nemotron 3.5 Lightning earns its slot as the spell for everyday agent work, the win will not be a louder rooftop, it will be fewer API calls and more models living where the work happens.