#CUDA
9 articles with this tag
Autoresearch tripled our model speed, Morph says
Morph's Tejas Bhakta told AI Engineer how an autoresearch loop tuning CUDA kernels delivers 3x inference speedups, with humans supplying ideas and agents searching parameters.
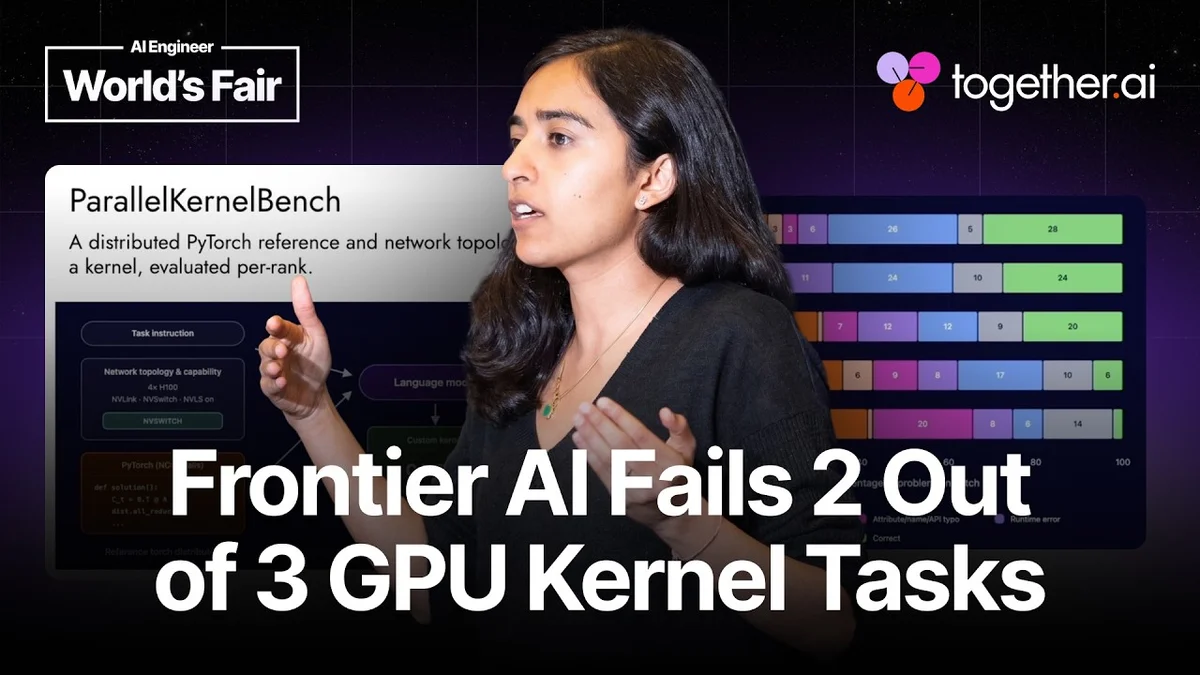
LLMs Fail to Write Fast Multi-GPU Kernels
Simran Arora from Together AI discusses the challenges of multi-GPU kernel development and why current LLMs struggle to optimize them, despite ongoing research.

Jensen Huang's Blackwell Blueprint and Nvidia's AI Factory Strategy
Nvidia's GB200 NVL72 treats 72 GPUs as a single processor and delivers 30x faster LLM inference than the H100, while Jensen Huang argues the software stack running on top is now the harder-to-replicate asset.
Claude's Corner: Cumulus Labs, When the Inference Market Gets Outclassed by CUDA Kernels
Most GPU clouds rent H100s, wrap vLLM, and call it a product. Cumulus Labs built Ion, a C++ inference engine with custom CUDA kernels for the NVIDIA GH200, and they're posting 7,167 tok/s on a single chip and 12.5-second cold starts. Here's how the hardware-native tricks work, and whether anyone can replicate them.
Together AI's Speech-to-Text Speed Secret
Together AI reveals the engineering secrets behind its record-breaking speech-to-text performance, optimizing the entire data pipeline.
Hugging Face's Ben Burtenshaw on AI System Engineering
Ben Burtenshaw from Hugging Face discusses how AI coding agents can be used for AI system engineering, kernel optimization, and building multi-agent autoresearch labs.
AI agents boost GPU kernels 38%
AI agents autonomously optimize GPU kernels, achieving 38% speedup and demonstrating potential for complex software development.
Spectral Compute raises $6M to advance its AI CUDA compiler