#AI Alignment
14 articles with this tag
Bostrom says waiting on superintelligence kills
Bostrom told a16z delaying safe superintelligence costs lives, with optimal delay measured in months.

OpenAI's Long-Horizon AI: A Safety Reckoning
OpenAI details how its long-running AI models exposed safety gaps missed by traditional testing, leading to new monitoring and safeguards.

LLM Role-Play Peril: The Hallucination Gap
LLMs hallucinate protective actions they can't perform when given roles without clear boundaries, a problem mitigated by explicit capability limits, not just alignment.
AI's Future: Human Will, Machine Judgment
Thinking Machines champions AI development focused on human will and judgment, emphasizing decentralized alignment and advanced multimodal interaction.
AI Safety Pioneers: Tegmark & Esvelt on Guardrails
Max Tegmark and Kevin Esvelt discuss the critical importance of AI safety, the risks of advanced AI, and the need for global cooperation in shaping a beneficial future.
OpenAI Launches Safety Fellowship
OpenAI launches a new fellowship for external researchers focused on AI safety and alignment, offering stipends and mentorship.
OpenAI Boosts AI Alignment Funding
OpenAI is significantly increasing funding for independent AI alignment research to ensure advanced AI systems are safe and beneficial.
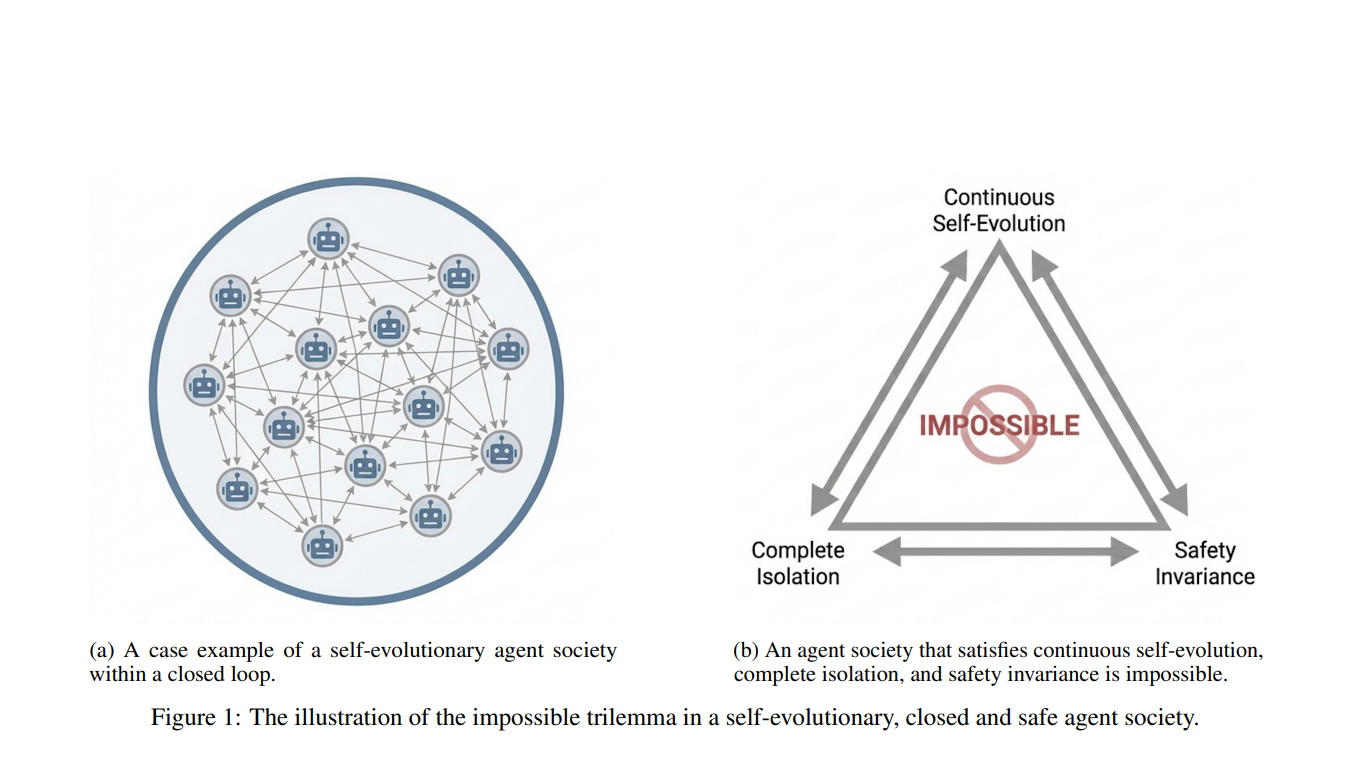
AI Societies' Safety Problem
Self-evolving AI societies face an impossible trilemma: achieving continuous learning, isolation, and safety alignment simultaneously.
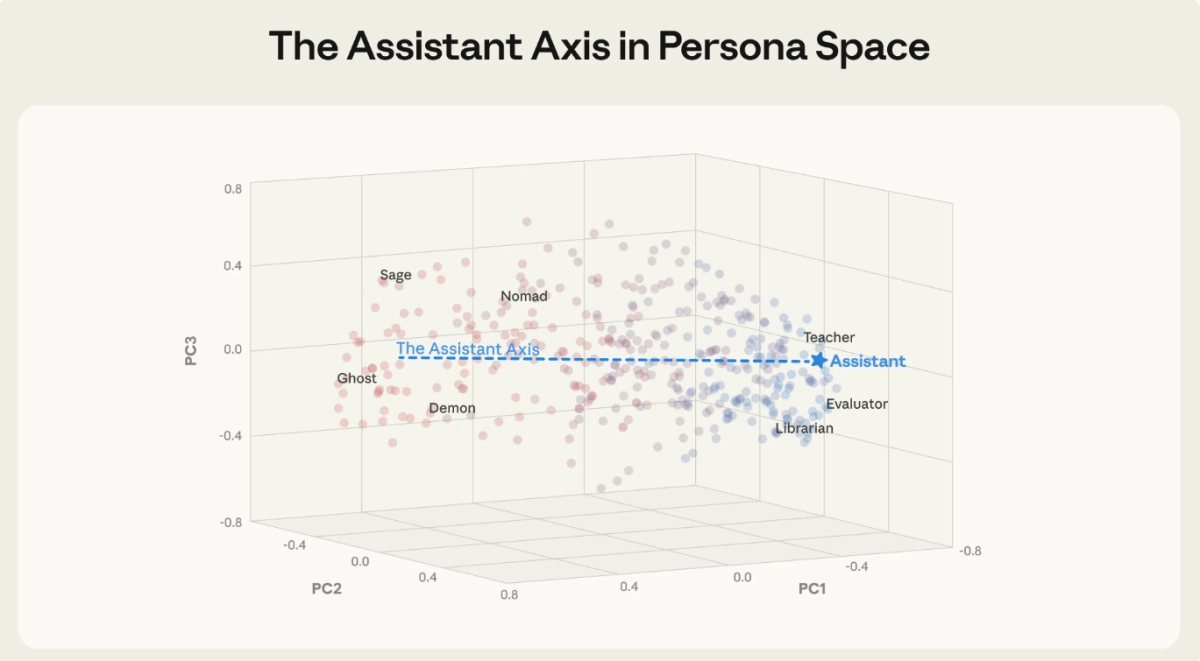
The Assistant Axis LLM: How Researchers Are Capping AI Drift
Scientists have mapped the internal neural space of LLMs, identifying the "Assistant Axis" as the key to stabilizing AI persona and preventing harmful behavior.
OpenAI is Debugging LLM Misalignment: New Tools Emerge
Researchers are tackling the challenge of understanding and correcting undesirable LLM behavior with a new technique called latent attribution, detailed by...

OpenAI is Debugging LLM Misalignment: New Tools Emerge
Researchers are tackling the challenge of understanding and correcting undesirable LLM behavior with a new technique called latent attribution, detailed by...
Emmett Shear on Building AI That Actually Cares: Beyond Control and Steering
Locai L1-Large beats GPT-5 on alignment using 'Forget-Me-Not'